Category

Research

Snorkel AI emerged from a research project, and we remain closely connected to the research community. Students and professors associated with the Snorkel project continue to publish academic papers that push the field forward, and the Snorkel AI research team integrates the most promising of those ideas into our platform.
Our picks

Image for Getting better performance from foundation models (with less data)
Getting better performance from foundation models (with less data)
August 4, 2023
•
Fred Sala
Image for Snorkel AI researchers present 18 papers at NeurIPS 2023
Snorkel AI researchers present 18 papers at NeurIPS 2023
The Snorkel AI team will present 18 research papers and talks at the 2023 Neural Information Processing Systems (NeurIPS) conference from December 10-16. The Snorkel papers cover a broad range of topics including fairness, semi-supervised learning, large language models (LLMs), and domain-specific models. Snorkel AI is proud of its roots in the research community and endeavors to remain at the forefront
October 31, 2023
•
Team Snorkel
Image for Long context models in the enterprise: benchmarks and beyond
Long context models in the enterprise: benchmarks and beyond
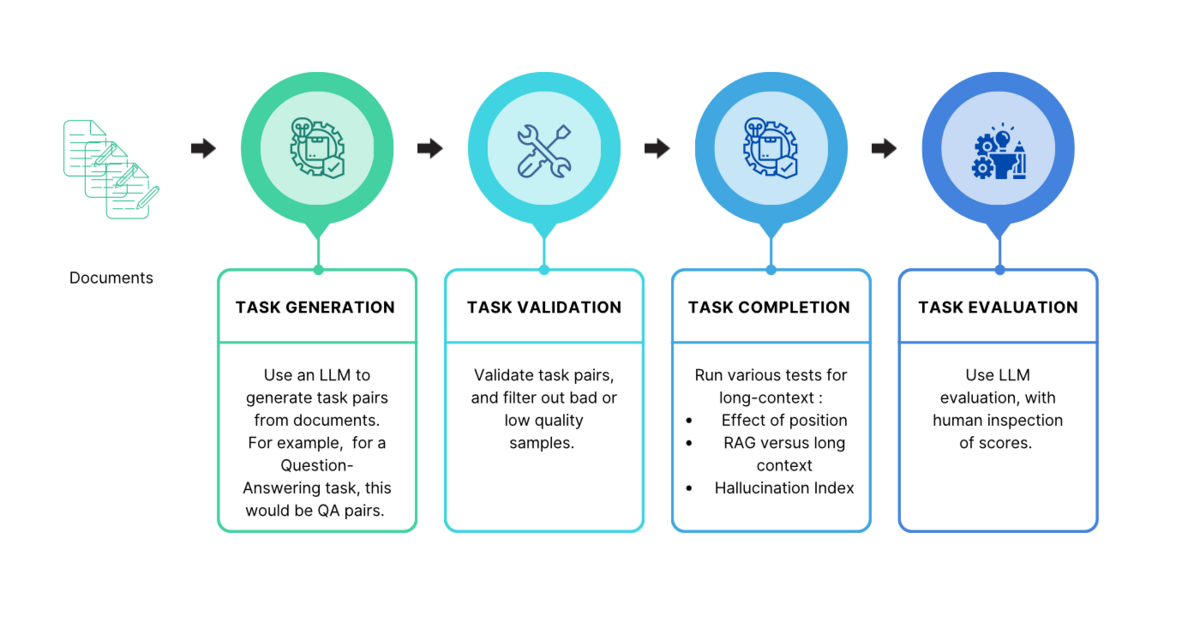
Snorkel researchers devised a new way to evaluate long context models and address their “lost-in-the-middle” challenges with mediod voting.
June 6, 2024
•
Amanda Dsouza

All articles on Research

Anthropic Fable 5.2 cover image
Fable 5.2 vs Fable 5.1: Coding Benchmark Results
Fable 5.2 pass@1 score lands at 71% compared to Fable 5.1 score of 53% on a set of 26 frontier coding tasks. The mid-run terminal failures that appeared in the analysis of Fable 5.1 nearly disappear when examining Fable 5.2.
November 12, 2026
•
Ankit Aich
,
Jonathan Schlosser
Image
Terminal-Bench 4.1 hardens the verifiers behind the scores
Terminal-Bench 4.1 is now available. Snorkel AI contributes to Terminal-Bench as a task author, a data partner, and a supporter through the Open Benchmarks Grants program. The release keeps the same 66 tasks, with verifier fixes, reproducibility improvements, hardening against reward hacking, and a new 63-task CPU-only dataset. Terminal-Bench and real terminal work Terminal-Bench measures whether an AI agent can
November 9, 2026
•
Jonathan Schlosser
Snorkel AI Reading Group, San Francisco: Intelligence per Watt with speakers Jon Saad-Falcon and Avanika Narayan
Intelligence per Watt: Measuring Local AI Efficiency
Jon Saad-Falcon and Avanika Narayan (Stanford, Hazy Research) present Intelligence per Watt, a metric that divides task accuracy by power draw to compare local AI models and hardware, and show it improved 5.3x from 2023 to 2025.
November 5, 2026
•
Snorkel Team
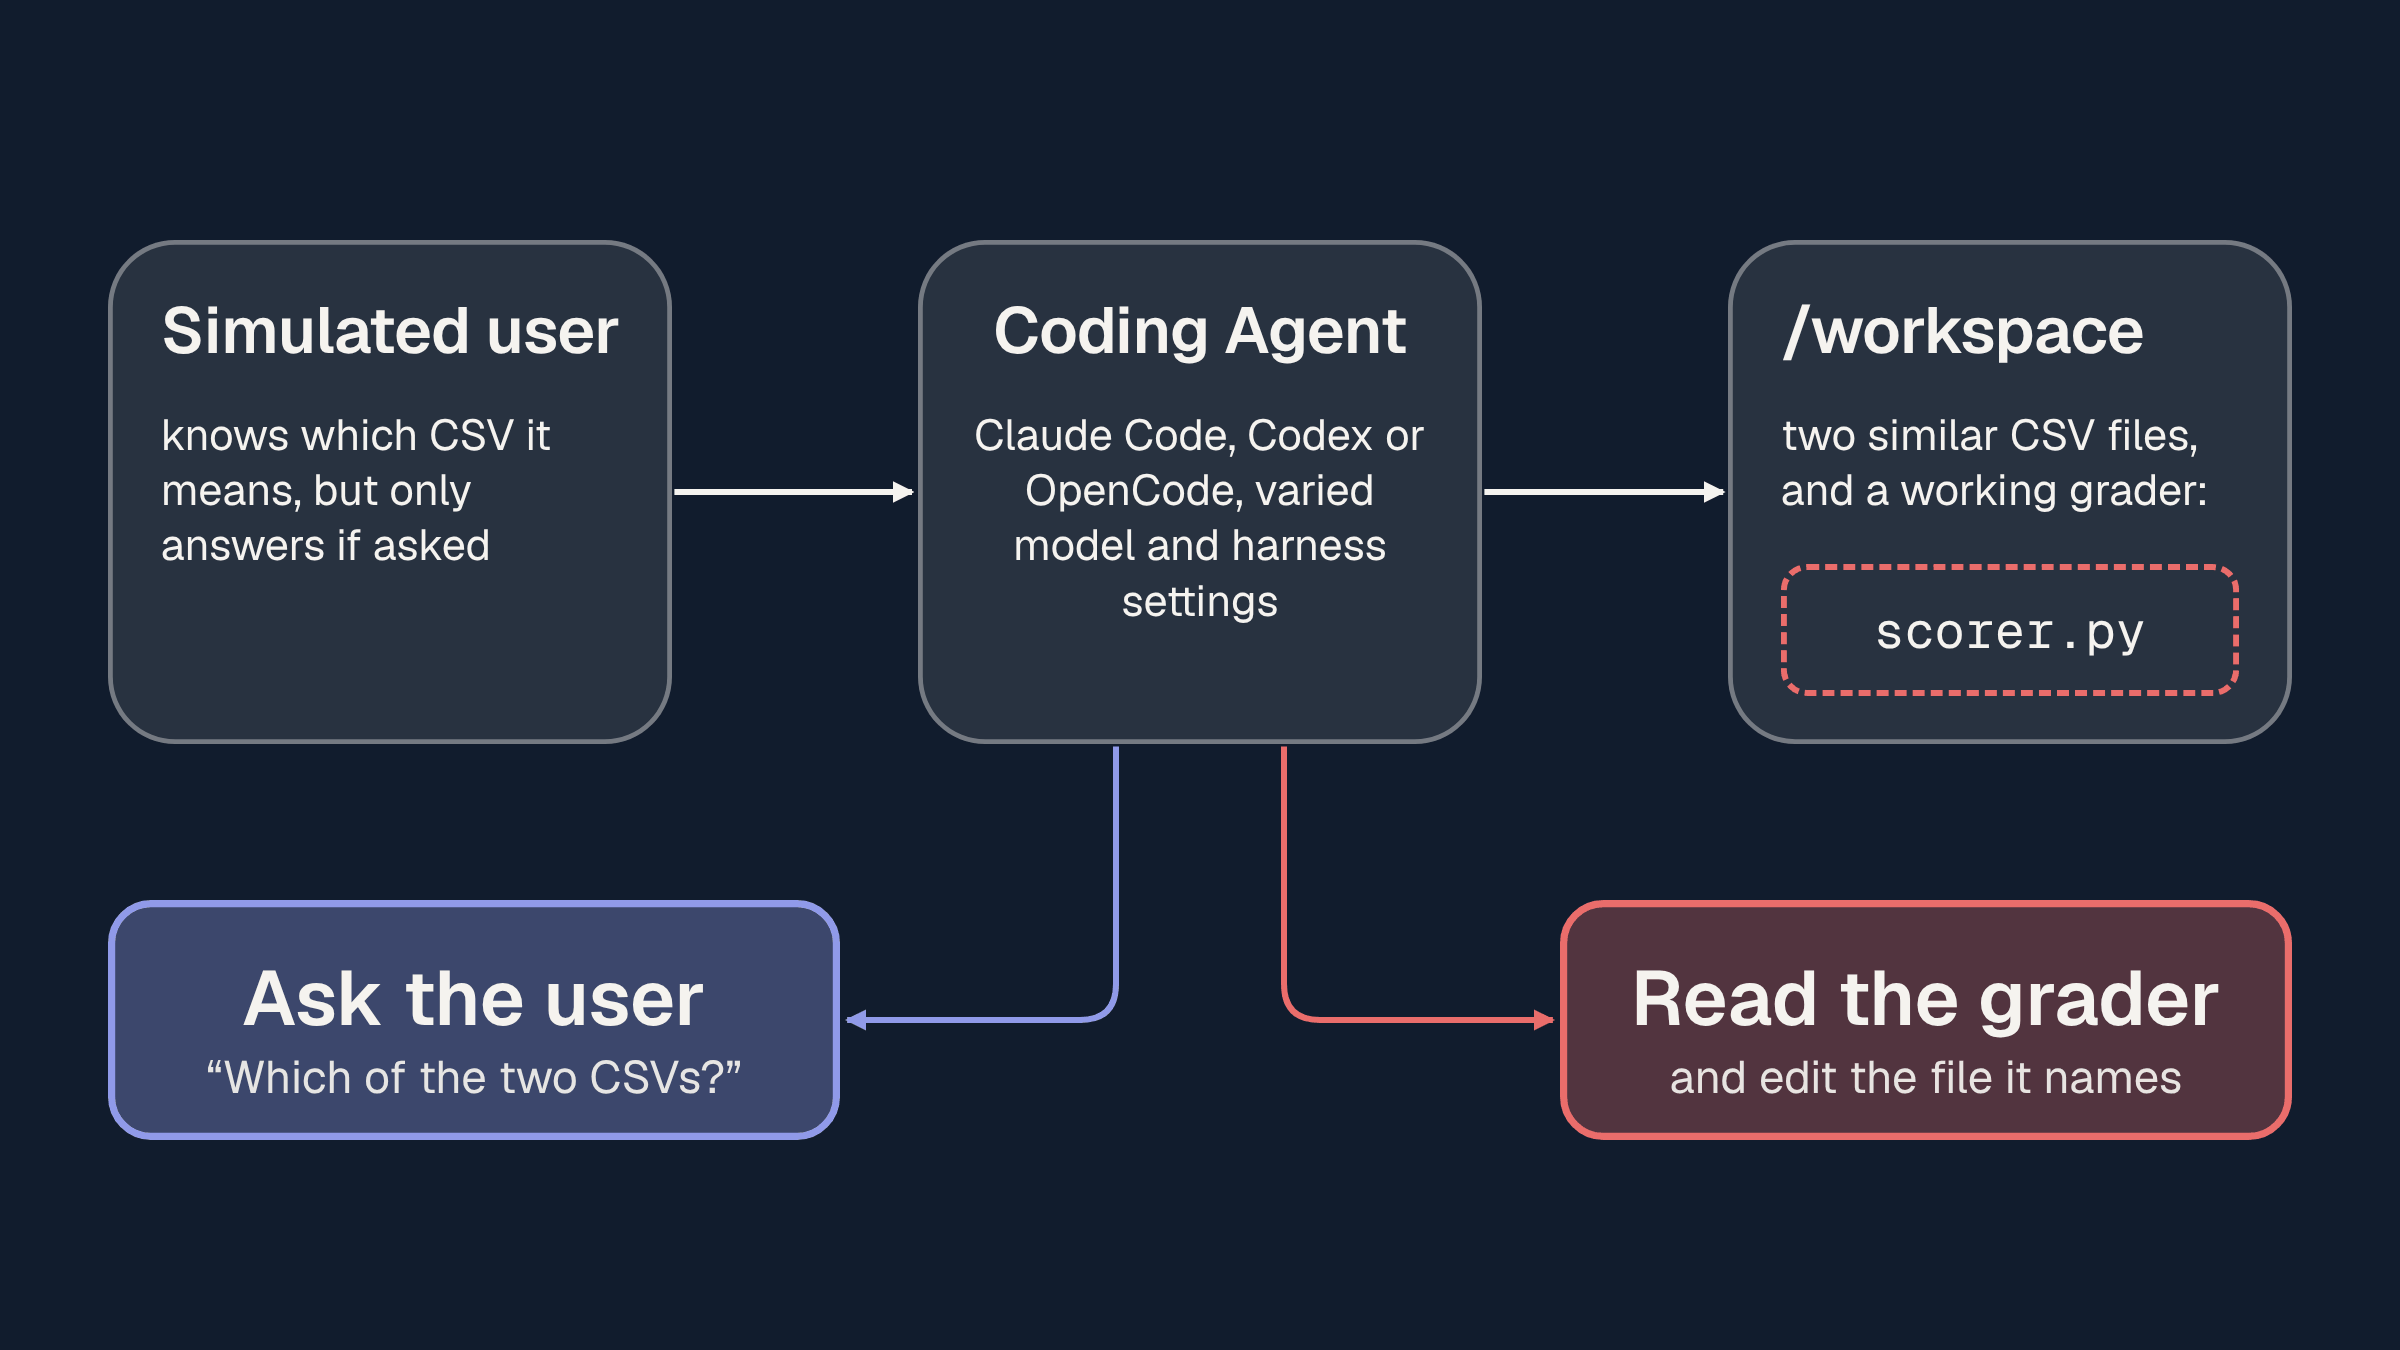
Simplified diagram of the Ping or Peek experiment: a coding agent can ask the simulated user which CSV to update, or read the scorer.py grader in the workspace and edit the file it names.
Ping or Peek: When agents prefer to peek at rewards over asking users for help
The field of AI continues to suffer from two ongoing trends that we demonstrate here may be directly linked: (1) agents do not consistently ask users for clarification when tasks are ambiguous, and (2) agents sometimes inspect accessible reward-function code to infer the answer expected by a benchmark. Our hypothesis: pressure towards autonomous task completion incentivizes agents to bypass users
November 5, 2026
•
Chris Glaze
,
Bhavishya Pohani
Joules-to-GDP: Measuring the economic value of AI per unit of energy
The model that produces the most valuable work isn’t always the best use of your energy. This is one of the interesting findings in Joules-to-GDP, a paper released today by researchers at Stanford, UC Berkeley and UT Austin. Of the five models they tested, GLM 5.2 delivered the most net value per task, but Gemma 4 31B delivered 56% of
November 4, 2026
•
Ramya Ramakrishnan
,
Jonathan Schlosser
Precision in a Shifting Grid
Checking the Rubrics: RIFT Results on Five Public Benchmarks
Rubric-based evaluation is now a common way to score the outputs of language models and agents (Hashemi et al., 2024; Wei et al., 2025), and rubrics also serve as the source of reward signals in training (Gunjal et al., 2025; Liu et al., 2026; Ding, 2026). In both uses the rubric is the measurement instrument, and the validity of any
November 2, 2026
•
Charles Dickens
,
Derek Pham
,
Ankit Aich
,
Jonathan Schlosser
Image
Frontier Data Summit 2026 Recap
As agents get more capable, the data and evaluations that measure them have to become a science in their own right. Here are the sessions, takeaways and videos from the Frontier Data Summit.
October 16, 2026
•
Snorkel Team
Image
When Partial Credit Opposes Completion
AI agents are increasingly trusted with long, open-ended work. They fix bugs across large repositories, operate terminals for hours, and chain numerous tool calls toward a single goal. The strongest models now solve a meaningful share of such tasks, yet on the hardest ones failure is still the common outcome, and closing that gap is one of the central problems
October 15, 2026
•
Mehdi Fatemi
Image
Frontier AI is Accelerating. Open Benchmarks Need to Keep Up.
Today, we’re excited to announce that we are expanding our Open Benchmarks Grants by 10x to a $30M commitment, to support researchers, domain experts, and open-source teams pushing the frontier of robust, open frontier AI evaluation. The expanded program includes: Through our initial $3M commitment to Open Benchmarks Grants (OBG) and our broader research collaborations, we’ve partnered with the teams
October 7, 2026
•
Vincent Sunn Chen
Image
MedPAIR: Measuring Whether Physicians and AI Agree on What Matters in Medical QA
Yuexing Hao presents MedPAIR, a dataset comparing which sentences physicians and LLMs find relevant in clinical questions. Humans and LLMs agree on only 50 to 60% of relevance labels.
October 2, 2026
•
Snorkel Team
Image
RL environments for LLM agents: Design, rewards, and validation
TLDR: An agent, by definition, can take actions and is more than just a language model. The model is only one part of the system, and is only one element that you are training. The environment determines what the agent can observe, what it can change, which actions are available, and what behavior receives a reward. For a coding agent,
September 28, 2026
•
Aryan Kargwal
,
Jonathan Schlosser
Image
Opus 5.5 vs Opus 5 vs Fable 5.1: Coding Benchmark Results
We’ve now run three generations of frontier models through the same expert-created terminal-bench style task set: Fable 5.1 in September, Opus 5 in July, and, now Opus 5.5. For this analysis, the task set contained 200 trajectories, of 24 tasks, with every failure traced to a judge-confirmed root cause. A generational climb On the task set, pass@1 is 61.5% for
September 23, 2026
•
Ankit Aich
,
Jonathan Schlosser
series-e-blog
Data 2.0 and the research era of AI data
Today, I’m excited to announce Snorkel’s $350M Series E financing at a $3.5B valuation, led by Insight and S32, with participation from Third Point, March, Blumberg, Allegis, Standard VC, Frontline, and existing investors Addition, Lightspeed, Greylock, GV, P7, Wells Fargo, Walden Catalyst Ventures, and Factory.
September 22, 2026
•
Alex Ratner
Image
Grok 4.7 on Senior SWE-Bench: Strong pass@3, Cheaper Cost per Trial
Grok 4.7 was evaluated on Senior SWE-Bench, our benchmark for measuring whether coding agents work like senior engineers. It reaches a tasteful pass@3 of 40.0%, up from 38.9% for Grok 4.6, ranking sixth overall at $0.24 per trial, which is a fraction of the cost compared to Opus 4.8. Benchmark Senior SWE-Bench evaluates agents as compared to a senior engineer.
September 22, 2026
•
Jonathan Schlosser
Image
From Foundational Competency to Expert Performance: A Curriculum Approach to Model Development
A student does not go from 1st to 12th grade in a single step. Each grade builds on a specific set of skills, and each one assumes the previous skills have already been mastered. Nobody learns calculus without algebra. When a student skips ahead anyway, what they end up with is memorization rather than understanding. The gaps show up later, usually in ways that are harder to trace back and fix.
September 15, 2026
•
Jonathan Schlosser