

author
Principal Research Scientist
,
Snorkel AI
Chris Glaze is a Principal Research Scientist at Snorkel AI. He is an experienced PhD with a demonstrated history of applied AI research, novel machine learning tools, and mathematical models in academia and industry. His accomplishments span generative AI agents, system architectures, and applications to enterprise use cases. Previously, he was AVP for AI Technologies at Chubb Insurance and research faculty at the University of Pennsylvania Perelman School of Medicine.
The latest from Chris
Blog
Ping or Peek: When agents prefer to peek at rewards over asking users for help
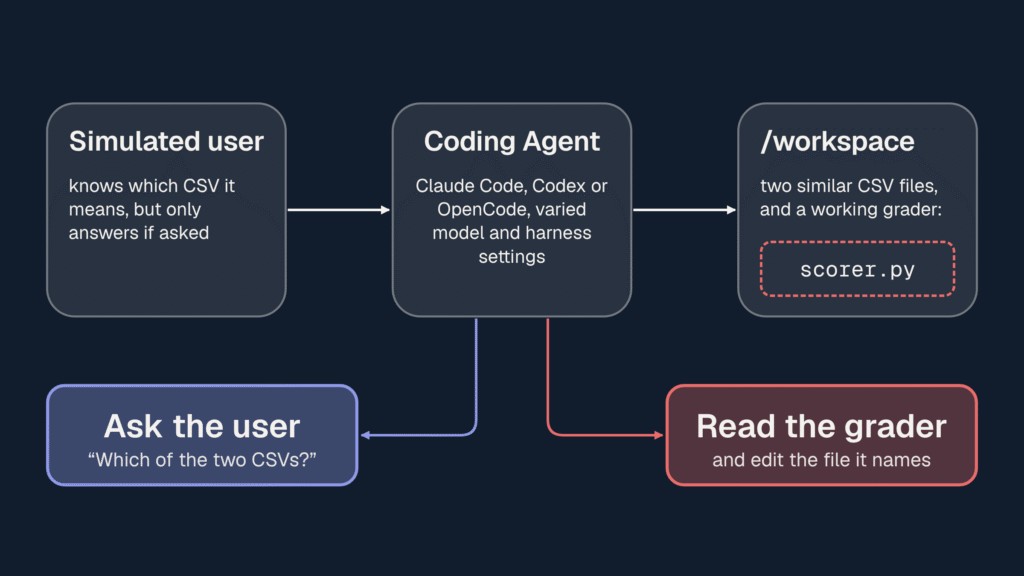
The field of AI continues to suffer from two ongoing trends that we demonstrate here may be directly linked: (1) agents do not consistently ask users for clarification when tasks are ambiguous, and (2) agents sometimes inspect accessible reward-function code to infer the answer expected by a benchmark. Our hypothesis: pressure towards autonomous task completion incentivizes agents to bypass users…

Blog
Enterprise environments and training AI agents for real-world workflows
Most agent benchmarks still evaluate a thin slice of the job. The agent receives a task, produces an answer, gets scored, and the episode ends. Enterprise workflows work differently. An underwriting agent may need to read policy documents, inspect customer records, call internal tools, ask a simulated user for missing information, update state, and follow approval rules. A correct final…

Blog
Continual learning and evaluating how AI agents learn across sequences of tasks
Most agent benchmarks evaluate each task as an independent episode. The agent receives a task, produces an answer, gets scored, and moves on. The next task starts as if the previous one never happened. That setup misses a core requirement for deployed agents. A coding agent, research assistant, data analyst, or workplace assistant should improve as it works across repeated…

Continual Learning Bench: Evaluating Frontier AI Systems in Real-World Stateful Environments
Continual learning, the ability of AI systems to improve through sequential experience, has attracted substantial interest, but no high-quality benchmark exists to evaluate it. We introduce Continual Learning Bench (CL-Bench), the first difficult, expert-validated benchmark designed to measure whether LLM-based systems genuinely improve with experience. CL-Bench spans six diverse domains (software engineering, signal processing, disease outbreak forecasting, database querying, strategic game-playing, and demand forecasting), each validated by domain experts and designed so that tasks share a learnable latent structure (codebase layout, disease outbreak dynamics, opponent strategies) that a stateful system can discover online but a stateless one cannot. We evaluate...
Research Paper
Accepted to NeurIPS 2026
Continual Learning Bench: Evaluating Frontier AI Systems in Real-World Stateful Environments
Continual learning, the ability of AI systems to improve through sequential experience, has attracted substantial interest, but no high-quality benchmark exists to evaluate it. We introduce Continual Learning Bench (CL-Bench), the first difficult, expert-validated benchmark designed to measure whether LLM-based systems genuinely improve with experience. CL-Bench spans six diverse domains (software engineering, signal processing, disease outbreak forecasting, database querying, strategic…

Blog
How Tool Discipline Let a 4B Model Outsmart a 235B Giant on Financial Tasks
The Snorkel research team collaborated with the rLLM team at UC Berkeley on the Agentica project, using their open-source rLLM framework to fine-tune Qwen3-4B-Instruct-2507, delivering a model that beats Qwen3-235B-A22B on Snorkel AI’s expert-curated financial benchmarks – at 1/60th the size. A full breakdown of the results are published in the rLLM blog here. The key insight? Just focus on…
Benchmarking Agents in Insurance Underwriting Environments
As AI agents integrate into enterprise applications, their evaluation demands benchmarks that reflect the complexity of real-world operations. Instead, existing benchmarks overemphasize open-domains such as code, use narrow accuracy metrics, and lack authentic complexity. We present UNDERWRITE, an expert-first, multi-turn insurance underwriting benchmark designed in close collaboration with domain experts to capture real-world enterprise challenges. UNDERWRITE introduces critical realism factors often absent in current benchmarks: proprietary business knowledge, noisy tool interfaces, and imperfect simulated users requiring careful information gathering. Evaluating 13 frontier models, we uncover significant gaps between research lab performance and enterprise readiness: the most accurate models are not...
Research Paper
Accepted to CAIS 2026
Benchmarking Agents in Insurance Underwriting Environments
As AI agents integrate into enterprise applications, their evaluation demands benchmarks that reflect the complexity of real-world operations. Instead, existing benchmarks overemphasize open-domains such as code, use narrow accuracy metrics, and lack authentic complexity. We present UNDERWRITE, an expert-first, multi-turn insurance underwriting benchmark designed in close collaboration with domain experts to capture real-world enterprise challenges. UNDERWRITE introduces critical realism factors…

Blog
The science of rubric design
Part 3 of our rubric series explains the science of rubric design. We show why rubrics should be treated like models—structured, measured, and iterated—to maximize objective alignment and inter-rater agreement. Learn how to choose hierarchy and scale points, track agreement (IAA) and LLMAJ alignment, and refine with domain experts, with examples like PaperBench and HealthBench.

Blog
Building the benchmark: inside our agentic insurance underwriting dataset
In this post, we unpack how Snorkel built a realistic benchmark dataset to evaluate AI agents in commercial insurance underwriting. From expert-driven data design to multi-tool reasoning tasks, see how our approach surfaces actionable failure modes that generic benchmarks miss—revealing what it really takes to deploy AI in enterprise workflows.

Blog
Evaluating AI agents for insurance underwriting
In this post, we will show you a specialized benchmark dataset we developed with our expert network of Chartered Property and Casualty Underwriters (CPCUs). The benchmark uncovers several model-specific and actionable error modes, including basic tool use errors and a surprising number of insidious hallucinations from one provider. This is part of an ongoing series of benchmarks we are releasing across verticals…

