


Since launching the Open Benchmarks Grants, we’ve received more than 100 applications from academic groups and industry labs spanning a wide range of domains and capabilities. As the best benchmarks drive how the field allocates research effort, the bar for benchmarks has risen as well. Here, we share what’s now table stakes for useful benchmarks, and what separates the ones that shape the frontier from the ones that just measure it.
Useful benchmarks are, first and foremost, effective measuring sticks
- Rigorously-validated tasks: The individual tasks are high quality (e.g. real-world complexity, well-structured instructions, verifiable solutions), as validated by real domain experts. GPQA introduced new adversarial quality control mechanisms to ensure that tasks were not only well-posed, but also tractable for other experts to solve.
- Fine-grained distributional diversity: The benchmark defines a clear taxonomy for its domain and distributes tasks across it deliberately, so results are actionable. MMLU constructed an ambitious taxonomy of 57 academic subjects (across STEM, humanities, and professional domains).
- Robust eval methodology: Metrics go beyond raw accuracy — capturing cost, latency, reasoning quality, or whatever dimensions actually matter for real-world use of the capability. The benchmark measures what it claims to, and the methodology is reproducible and robust to contamination. TAU-bench evaluates both task completion and adherence to policy constraints, e.g., a model that books the right flight but violates fare class rules still fails.
- Model headroom: The benchmark is unsaturated. It exposes real soft spots in model capabilities and reliably separates frontier models. At its release, ARC-AGI-3 had frontier models scoring below 1% over tasks that were 100% solvable by humans.
Lasting benchmarks push the frontier
- A thesis on the frontier: The benchmark defines a new subspace of capabilities for the frontier or revisits a previous research question with new assumptions. The most ambitious benchmarks have a thesis on where the world is going: Terminal-Bench was a bet on the CLI– not only for coding agents, but for general-purpose computer use.
- Roadmaps for the field: The benchmark produces new roadmaps. It inspires new attacks against important research problems, including follow-on benchmarks and methods that advance the field. SWE-Bench spawned a whole family of benchmarks (e.g. Lite, Verified, Multilingual, Multimodal), and its evolution has shaped how teams build coding agents.
- Researcher UX: The benchmark builders are committed to the “researcher experience”. This means the benchmark is simple to run models/agents against, simple to contribute to/extend, and simple to adapt supervision/reward signals for RL/tuning. HELM pioneered a standardized and modular harness for reproducible evals; Terminal-Bench2.0 shipped with Harbor, which has become de facto tooling for teams building agents.
Every benchmark highlighted here has had a lasting impact— a reminder that individual researchers and small teams have enormous agency to define and advance the field. We’re excited to support the next ones with the Open Benchmarks Grants. Share your proposals or reach out at benchmarks.snorkel.ai!
Vincent Sunn Chen
Research Fellow & Founding Team
Vincent Sunn Chen is a Research Fellow on the founding team at Snorkel AI. His work centers on systems for high quality AI evaluation & data development with experts in the loop. He currently leads the Open Benchmarks Grants, a $3M commitment to funding benchmarks and infrastructure for frontier agents. Prior to Snorkel, Vincent was a researcher at the Stanford AI Lab, where he studied the foundations of data-centric AI systems.
Recommended articles
View all articles
Intelligence per Watt: Measuring Local AI Efficiency
Jon Saad-Falcon and Avanika Narayan (Stanford, Hazy Research) present Intelligence per Watt, a metric that divides task accuracy by power draw to compare local AI models and hardware, and show it improved 5.3x from 2023 to 2025.
November 5, 2026
•
Snorkel Team
Ping or Peek: When agents prefer to peek at rewards over asking users for help
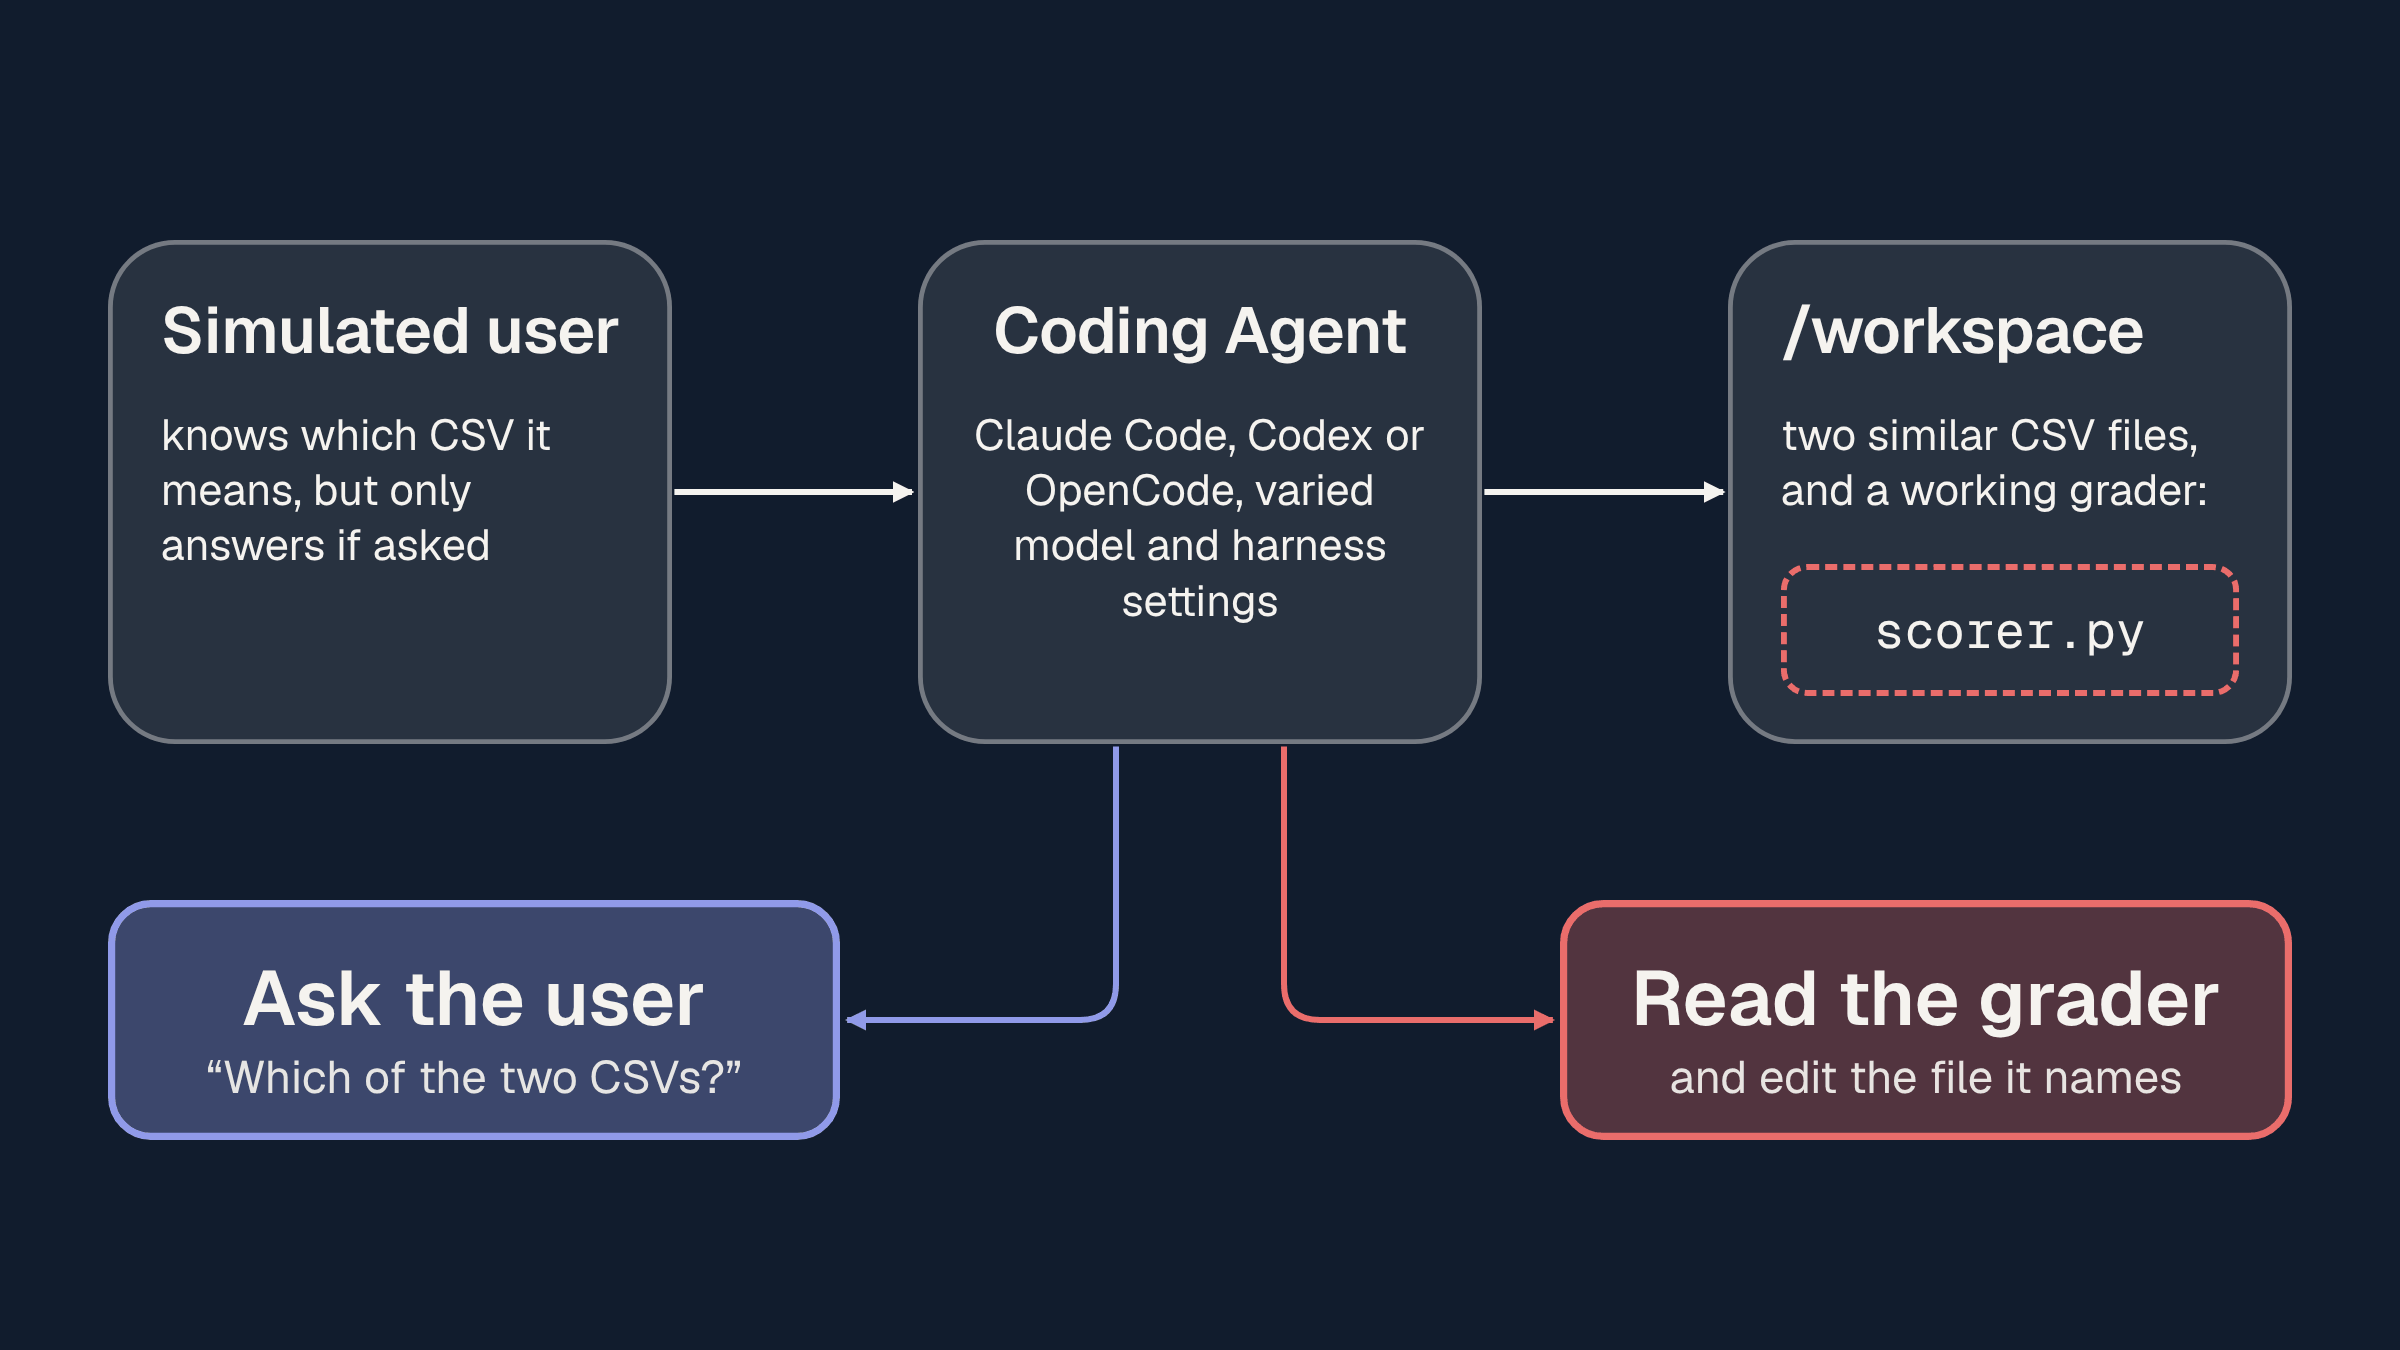
The field of AI continues to suffer from two ongoing trends that we demonstrate here may be directly linked: (1) agents do not consistently ask users for clarification when tasks are ambiguous, and (2) agents sometimes inspect accessible reward-function code to infer the answer expected by a benchmark. Our hypothesis: pressure towards autonomous task completion incentivizes agents to bypass users
November 5, 2026
•
,
Joules-to-GDP: Measuring the economic value of AI per unit of energy
The model that produces the most valuable work isn’t always the best use of your energy. This is one of the interesting findings in Joules-to-GDP, a paper released today by researchers at Stanford, UC Berkeley and UT Austin. Of the five models they tested, GLM 5.2 delivered the most net value per task, but Gemma 4 31B delivered 56% of
November 4, 2026
•
,

