resources

Resource library

Explore our complete library of resources including blogs, benchmarks, research papers, and more.

Image for Data 2.0 and the research era of AI data
Blog

Data 2.0 and the research era of AI data

Announcing Snorkel’s $350M fundraise to build the frontier lab for AI data.
September 22, 2026
Image for Terminal-Bench 4.0: Why Continuous Benchmarks Require Continuous QA
Blog

Terminal-Bench 4.0: Why Continuous Benchmarks Require Continuous QA

Announcing a $3M commitment to launch Open Benchmarks Grants
August 28, 2026
Image for Grok 4.5 Testing Results: How SpaceXAI’s New Model Performs on Real Professional Work
Blog

Grok 4.5 Testing Results: How SpaceXAI’s New Model Performs on Real Professional Work

Announcing a $3M commitment to launch Open Benchmarks Grants
July 8, 2026
Image for Why coding agents need better data, evals, and environments
Blog

Why coding agents need better data, evals, and environments

Announcing a $3M commitment to launch Open Benchmarks Grants
May 11, 2026
Image for Closing the Evaluation Gap in Agentic AI
Blog

Closing the Evaluation Gap in Agentic AI

Announcing a $3M commitment to launch Open Benchmarks Grants
February 11, 2026
Image for Why Frontier Agents Fail Real Engineering Work: Two Terminal-Bench 3.0 Task Deep Dives
Blog

Why Frontier Agents Fail Real Engineering Work: Two Terminal-Bench 3.0 Task Deep Dives

Announcing a $3M commitment to launch Open Benchmarks Grants
August 24, 2026
Image for Building FinQA: An Open RL Environment for Financial Reasoning Agents
Blog

Building FinQA: An Open RL Environment for Financial Reasoning Agents

Announcing a $3M commitment to launch Open Benchmarks Grants
March 30, 2026
Image for The science of rubric design
Blog

The science of rubric design

Announcing a $3M commitment to launch Open Benchmarks Grants
September 11, 2025
Image for Benchtalks #3: We taught AI everything except how to learn
Blog

Benchtalks #3: We taught AI everything except how to learn

Featuring Parth Asawa (Continual Learning Bench)

June 25, 2026
of
Type: All Types
Sort: Newest
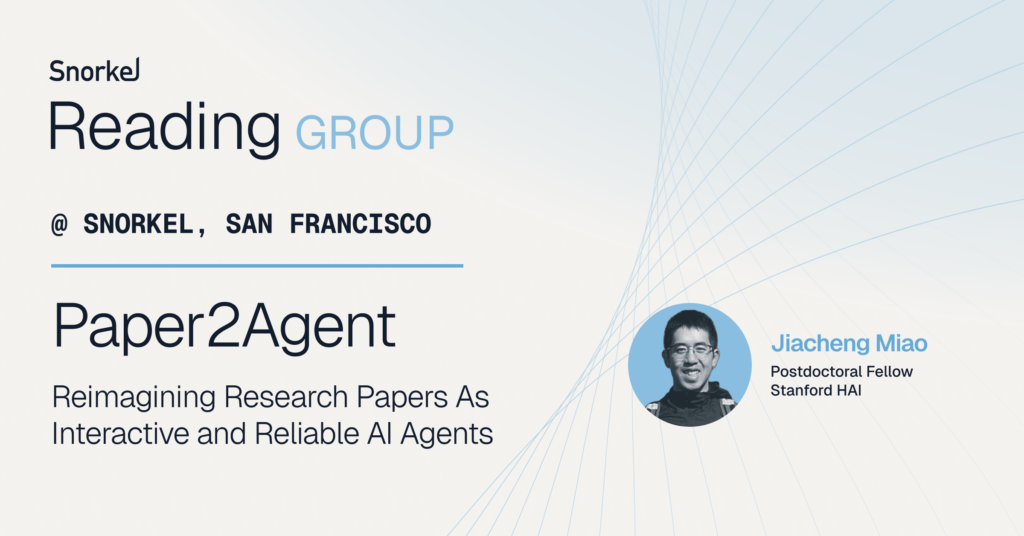
Paper2Agent: Turning Research Papers Into Interactive AI Agents
Blog
NEW
Paper2Agent: Turning Research Papers Into Interactive AI Agents

Jiacheng Miao (Stanford HAI) presents Paper2Agent, a framework that turns a research paper and its code into an interactive AI agent, scoring 91.2% on 300 benchmark questions against 80.3% for Claude Code with the repo.
Nov 19, 2026 •
Learn more about Paper2Agent: Turning Research Papers Into Interactive AI Agents
Training agents for professional work when success is rare
Blog
NEW
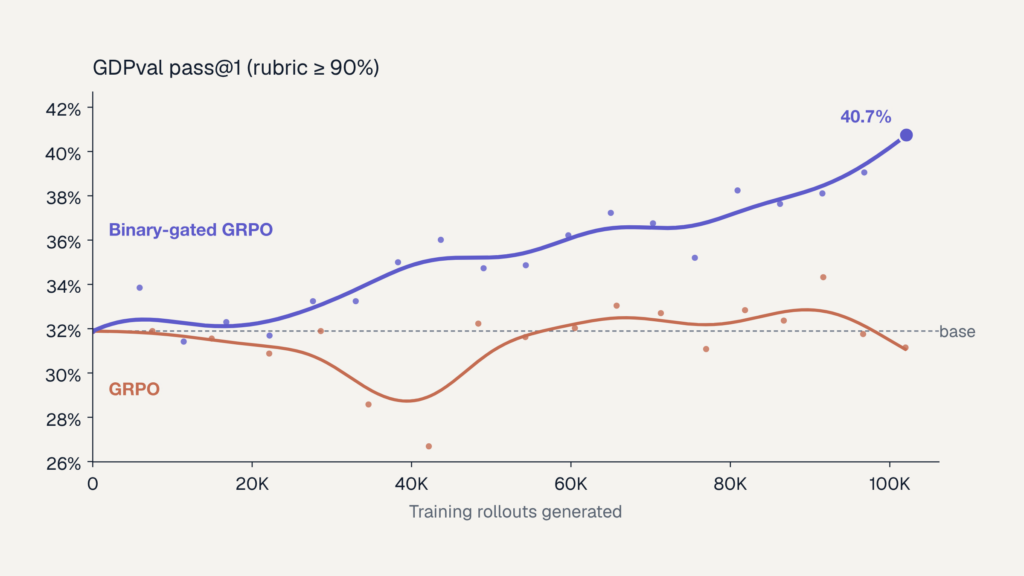
Training agents for professional work when success is rare

We trained Qwen3.8-27B on 1,105 professional tasks from Snorkel’s GDPval+ series. After about 102K training rollouts, the model reaches 40.7% pass@1 on OpenAI’s GDPval gold set, up from 31.9%. Its deliverables now beat those of human experts in 44.0% of LLM-judged head-to-head comparisons, compared with 36.4% for the base model. The gains come from two ingredients working together, expert-built training…
Nov 19, 2026 •
Learn more about Training agents for professional work when success is rare
Fable 5.2 vs Fable 5.1: Coding Benchmark Results
Blog
NEW
Fable 5.2 vs Fable 5.1: Coding Benchmark Results

Fable 5.2 pass@1 score lands at 71% compared to Fable 5.1 score of 53% on a set of 26 frontier coding tasks. The mid-run terminal failures that appeared in the analysis of Fable 5.1 nearly disappear when examining Fable 5.2.
Nov 12, 2026 •
Learn more about Fable 5.2 vs Fable 5.1: Coding Benchmark Results
Terminal-Bench 4.1 hardens the verifiers behind the scores
Blog
Terminal-Bench 4.1 hardens the verifiers behind the scores

Terminal-Bench 4.1 is now available. Snorkel AI contributes to Terminal-Bench as a task author, a data partner, and a supporter through the Open Benchmarks Grants program. The release keeps the same 66 tasks, with verifier fixes, reproducibility improvements, hardening against reward hacking, and a new 63-task CPU-only dataset. Terminal-Bench and real terminal work Terminal-Bench measures whether an AI agent can…
Nov 09, 2026 •
Learn more about Terminal-Bench 4.1 hardens the verifiers behind the scores
Intelligence per Watt: Measuring Local AI Efficiency
Blog
Intelligence per Watt: Measuring Local AI Efficiency

Jon Saad-Falcon and Avanika Narayan (Stanford, Hazy Research) present Intelligence per Watt, a metric that divides task accuracy by power draw to compare local AI models and hardware, and show it improved 5.3x from 2023 to 2025.
Nov 05, 2026 •
Learn more about Intelligence per Watt: Measuring Local AI Efficiency
Ping or Peek: When agents prefer to peek at rewards over asking users for help
Blog
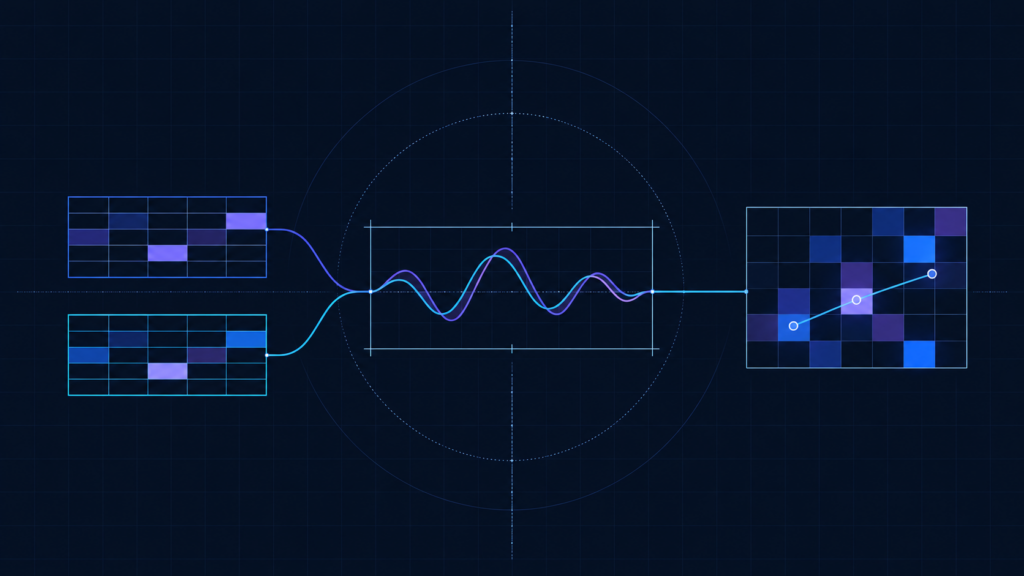
Ping or Peek: When agents prefer to peek at rewards over asking users for help

The field of AI continues to suffer from two ongoing trends that we demonstrate here may be directly linked: (1) agents do not consistently ask users for clarification when tasks are ambiguous, and (2) agents sometimes inspect accessible reward-function code to infer the answer expected by a benchmark. Our hypothesis: pressure towards autonomous task completion incentivizes agents to bypass users…
Nov 05, 2026 •
Learn more about Ping or Peek: When agents prefer to peek at rewards over asking users for help
Joules-to-GDP: Measuring the economic value of AI per unit of energy
Blog
Joules-to-GDP: Measuring the economic value of AI per unit of energy

The model that produces the most valuable work isn’t always the best use of your energy. This is one of the interesting findings in Joules-to-GDP, a paper released today by researchers at Stanford, UC Berkeley and UT Austin. Of the five models they tested, GLM 5.2 delivered the most net value per task, but Gemma 4 31B delivered 56% of…

Learn more about Joules-to-GDP: Measuring the economic value of AI per unit of energy
Joules-to-GDP: How Much Economic Value Do AI Systems Produce per Unit of Energy?
AI systems are increasingly used to complete economically valuable tasks in various professions, such as software engineering and finance. This motivates the question: how much economic value does an AI system produce per unit of energy? To answer it, we introduce Joules-to-GDP, a framework that measures output dollar value minus AI execution cost per unit of energy, which we call Net Value per Joule (NVJ), and expert time saved per unit of energy, or Time Saving per Joule (TSJ). We then apply the framework to 220 GDPval tasks across 44 occupations. Four findings stand out. First, the most valuable work...
Research Paper
Joules-to-GDP: How Much Economic Value Do AI Systems Produce per Unit of Energy?

AI systems are increasingly used to complete economically valuable tasks in various professions, such as software engineering and finance. This motivates the question: how much economic value does an AI system produce per unit of energy? To answer it, we introduce Joules-to-GDP, a framework that measures output dollar value minus AI execution cost per unit of energy, which we call…
Nov 02, 2026 •

Amirreza Zeinali, Jon Saad-Falcon, Avanika Narayan, Mersad Abbasi + 4 more

Learn more about Joules-to-GDP: How Much Economic Value Do AI Systems Produce per Unit of Energy?
Checking the Rubrics: RIFT Results on Five Public Benchmarks
Blog
Checking the Rubrics: RIFT Results on Five Public Benchmarks

Rubric-based evaluation is now a common way to score the outputs of language models and agents (Hashemi et al., 2024; Wei et al., 2025), and rubrics also serve as the source of reward signals in training (Gunjal et al., 2025; Liu et al., 2026; Ding, 2026). In both uses the rubric is the measurement instrument, and the validity of any…

Learn more about Checking the Rubrics: RIFT Results on Five Public Benchmarks
1 2 … 71
Image

Join our newsletter

For expert advice, the latest research, and exclusive events.
By submitting this form, I acknowledge I will receive email updates from Snorkel AI, and I agree to the Terms of Use and acknowledge that my information will be used in accordance with the Privacy Policy.