


LLM distillation will become a much more common and important practice for data science teams in 2024, according to a poll of attendees at Snorkel AI’s 2023 Enterprise LLM Virtual Summit.
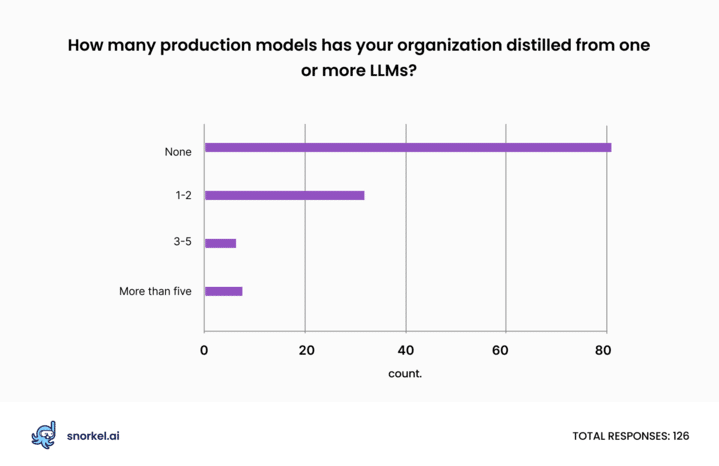
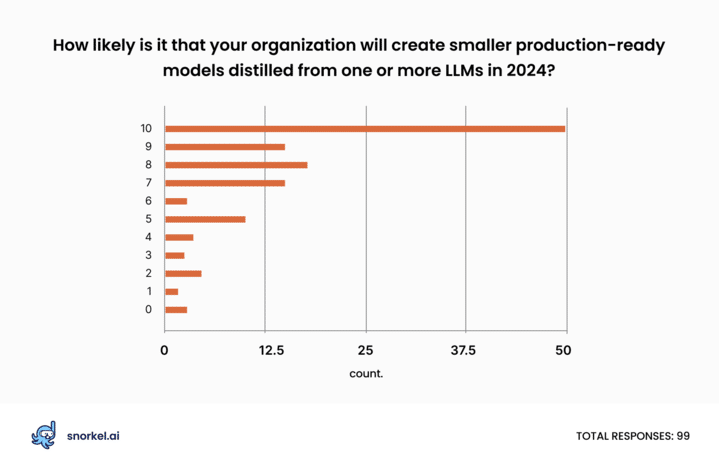
Only about a third of respondents (36%) said that their company had distilled any smaller models from LLMs so far. However, 74% said their organization would probably employ LLM distillation to create compact, production-ready models in the coming year.
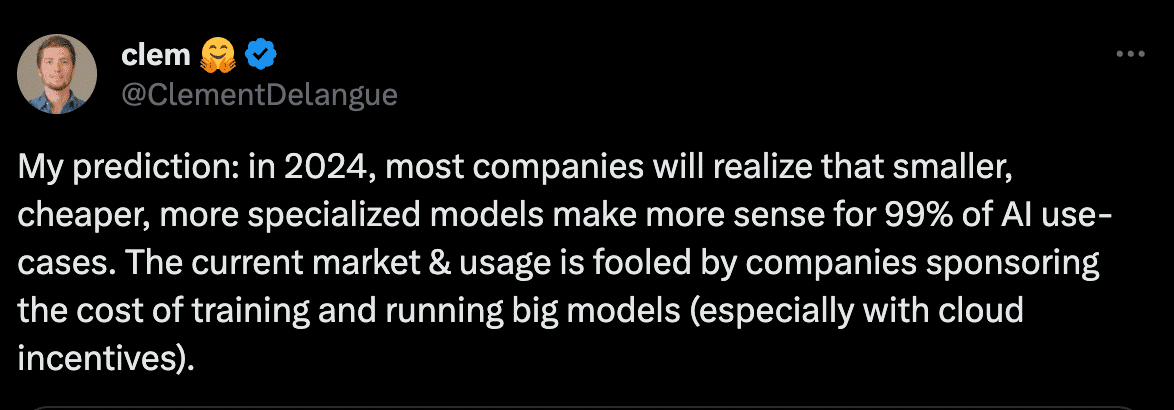
These results—especially when combined with answers to other questions from our poll—suggest that previously little-noticed LLM distillation techniques are about to take a bigger role in the enterprise space. And we are not alone in seeing this trend. Clem Dalangue, Co-Founder and CEO of Hugging Face, recently predicted that 2024 will be the year when companies realize that smaller models make sense for the vast majority of use cases.
What factors make LLM distillation more important?
Generative AI and large language models stood at the “Peak of Inflated Expectations” in Gartner’s 2023 Hype Cycle report for AI, and they’re beginning to slip into the “Trough of Disillusionment.”
LLMs remain amazing. Their ability to perform competently at tasks they were not trained for is incredible. But their performance on enterprise-critical tasks falls short of accuracy benchmarks set for deployment. Even when LLMs clear those benchmarks, they’re often prohibitively expensive to run for high-throughput applications. To use an analogy, they’re like using a supercomputer to play Frogger. It will work, but you’re burning more resources than necessary.
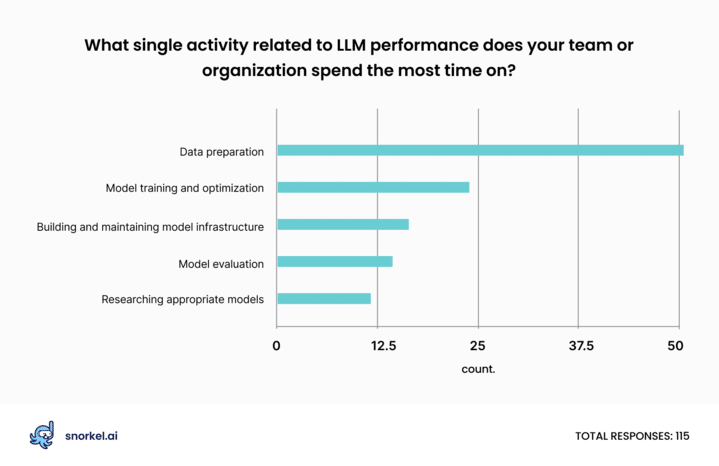
As data science teams reorient around the enduring value of small, deployable models, they’re also learning how LLMs can accelerate data labeling. According to our poll participants, data preparation still occupies more data scientists’ hours than anything else. LLM distillation creates an opportunity to shrink that burden and allow teams to ship more models, faster.
What is LLM distillation?
LLM distillation is a collection of approaches that use one or more large models to “teach” a smaller model to complete a specific task. This family of techniques allows data science teams to harness the power of models with tens or hundreds of billions of parameters in a format that’s easier to deploy and far less expensive to use at inference time.
In its simplest form, data scientists employ LLM distillation by prompting an LLM to apply labels to otherwise unlabeled data. This creates a training set used to train a smaller model, which could be a neural network or something as simple as logistic regression.
Data scientists can enhance distillation’s effectiveness by first fine-tuning the “teacher” model. They can also use more advanced approaches to distill the power of multiple LLMs through programmatic labeling or use an approach known as “distilling step-by-step,” as Snorkel researcher Jason Fries explained in his summit presentation. In addition to their size and cost reductions, these advanced approaches can yield models that achieve higher accuracy scores than their parent models.
Model safety remains a top concern; data follows closely
Respondents at organizations large and small named “model risk”—such as hallucinations, bias, and the risk of divulging intellectual property—as the biggest gap they would like to overcome when using LLMs. This is consistent with findings from our earlier event polls, though the thrust of this question was slightly different.
LLMs’ continued tendency to sometimes deliver wildly wrong or offensive responses has been a consistent theme for those who say LLMs are not ready for prime time. As Yoav Shoham, co-founder of AI21 Labs, put it at our Future of Data-Centric AI event in June: “If you’re brilliant 90% of the time and nonsensical or just wrong 10% of the time, that’s a non-starter. It kills all credibility or trust, and you can’t have that.”
Data quality and quantity closely followed model risk—and even tied model risk as a primary gap among the subset of respondents working at companies with valuations of at least a $1 billion.
These issues are closely related. Fine-tuning offers one of the best ways to reduce model risk, and fine-tuning requires meaningful quantities of high-quality hard-to-label data. Data science teams can also side-step the problems of model risk through distillation. While narrowly-trained classification models can be wrong, they’re typically not capable of hallucinating.

Will “LLM distillation” be the AI word of 2024?
Data science teams feel pressure to deliver value through LLMs in the next year, even as concerns around LLM model risk endure. Our poll results suggest that many practitioners think LLM distillation may be the answer they’ve been overlooking.
While companies have—so far—done very little model distillation, it seems that data scientists and data science leaders see its potential. If our poll results reflect reality, we expect to see enterprises deploy many more models created through distillation in 2024 than we did in 2023.
Get a demo from Snorkel AI
Advanced distillation approaches in Snorkel Flow enabled our researchers to build a model as accurate as a fine-tuned version of GPT-3 that cost 25% as much to train and 0.1% as much to run. We can deliver similar results for your organization.
With Snorkel Flow, you can:
- Label and curate data at scale in a repeatable, auditable iterative process that lets you reduce months of work to days or hours.
- Fine-tune large language models to boost their performance on your specific domain and use cases.
- Distill the power of LLMs into small models to get accurate, reliable, and affordable models into production faster.
- Sharpen your generative AI systems to meet the tone and factual accuracy your company needs.
- Curate and enrich data for retrieval augmented generation (RAG) to ensure that your application feeds your LLM the exact context it needs at minimal latency.
Contact us at info@snorkel.ai or request a demo to get started or to learn more.
Matt Casey
Data Science Content Lead
Matt Casey leads content production at Snorkel AI. In prior roles, Matt built machine learning models and data pipelines as a data scientist. As a journalist, he produced written and audio content for outlets including The Boston Globe and NPR affiliates.
Recommended articles
View all articles

MedPAIR: Measuring Whether Physicians and AI Agree on What Matters in Medical QA
Yuexing Hao presents MedPAIR, a dataset comparing which sentences physicians and LLMs find relevant in clinical questions. Humans and LLMs agree on only 50 to 60% of relevance labels.
October 2, 2026
•
Snorkel Team

RL environments for LLM agents: Design, rewards, and validation
TLDR: An agent, by definition, can take actions and is more than just a language model. The model is only one part of the system, and is only one element that you are training. The environment determines what the agent can observe, what it can change, which actions are available, and what behavior receives a reward. For a coding agent,
September 28, 2026
•
,

Opus 5.5 vs Opus 5 vs Fable 5.1: Coding Benchmark Results
We’ve now run three generations of frontier models through the same expert-created terminal-bench style task set: Fable 5.1 in September, Opus 5 in July, and, now Opus 5.5. For this analysis, the task set contained 200 trajectories, of 24 tasks, with every failure traced to a judge-confirmed root cause. A generational climb On the task set, pass@1 is 61.5% for
September 23, 2026
•
,

