Category

Research

Snorkel AI emerged from a research project, and we remain closely connected to the research community. Students and professors associated with the Snorkel project continue to publish academic papers that push the field forward, and the Snorkel AI research team integrates the most promising of those ideas into our platform.
Our picks

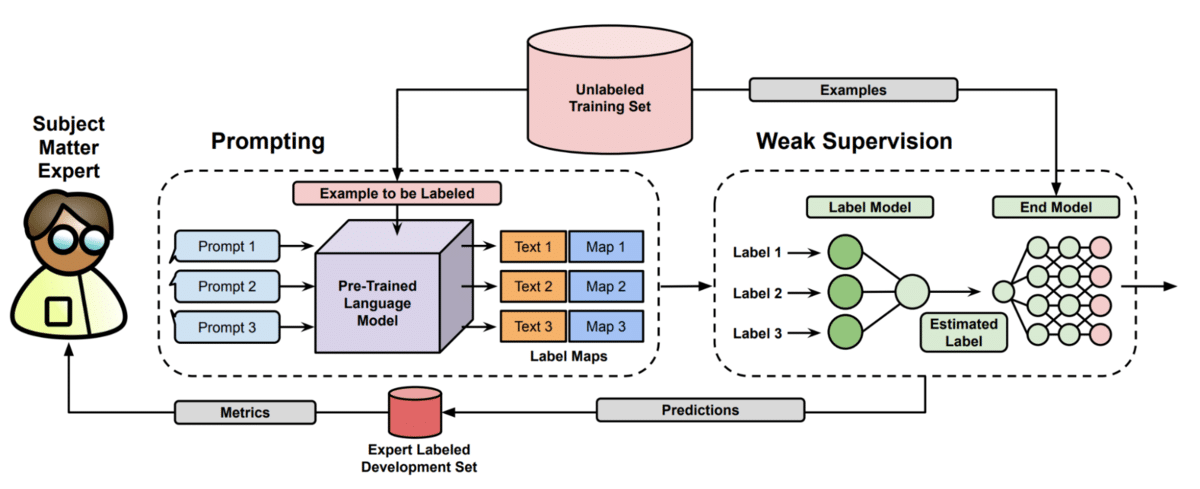
Image for Getting better performance from foundation models (with less data)
Getting better performance from foundation models (with less data)
August 4, 2023
•
Fred Sala
Image for Snorkel AI researchers present 18 papers at NeurIPS 2023
Snorkel AI researchers present 18 papers at NeurIPS 2023
The Snorkel AI team will present 18 research papers and talks at the 2023 Neural Information Processing Systems (NeurIPS) conference from December 10-16. The Snorkel papers cover a broad range of topics including fairness, semi-supervised learning, large language models (LLMs), and domain-specific models. Snorkel AI is proud of its roots in the research community and endeavors to remain at the forefront
October 31, 2023
•
Team Snorkel
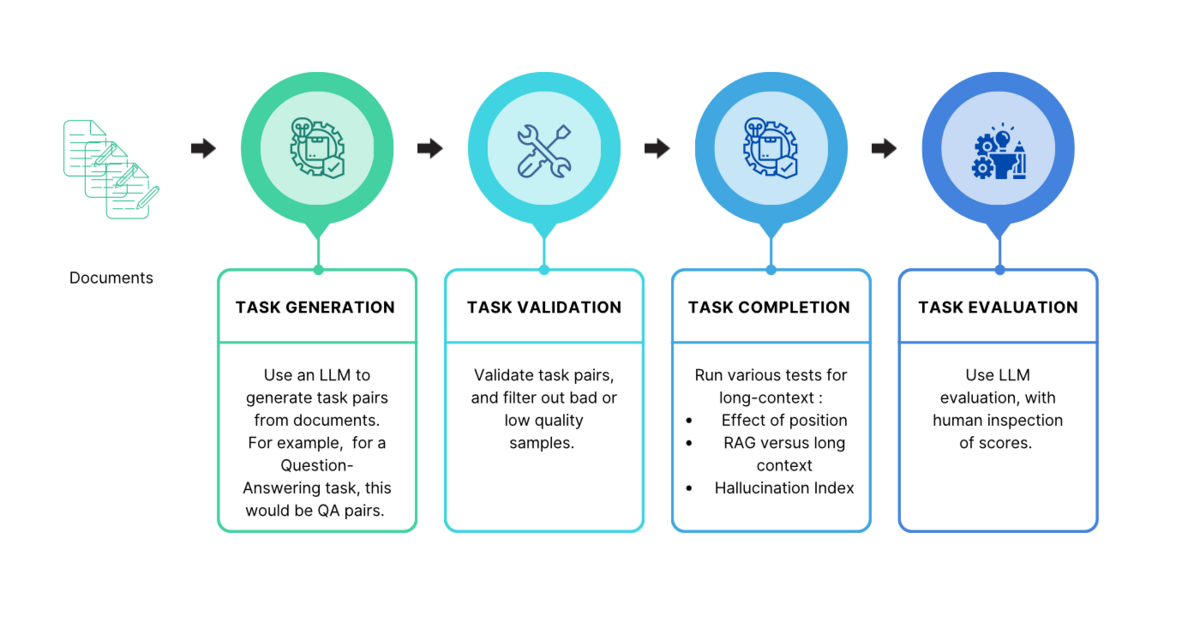
Image for Long context models in the enterprise: benchmarks and beyond
Long context models in the enterprise: benchmarks and beyond
Snorkel researchers devised a new way to evaluate long context models and address their “lost-in-the-middle” challenges with mediod voting.
June 6, 2024
•
Amanda Dsouza

All articles on Research

Closing the Evaluation Gap in Agentic AI Image
Closing the Evaluation Gap in Agentic AI
Today, AI is marked by a growing asymmetry: the excitement around agentic AI is real — backed by quantitative progress on model cards and genuine leaps forward, especially in coding. But ask individuals or enterprises where they feel ready to deploy agentic automation in high-stakes, domain-specific settings outside of coding… and you will find hesitation. The reason: our ability to
February 11, 2026
•
Vincent Sunn Chen
Image
SlopCodeBench: Measuring Code Erosion as Agents Iterate
SlopCodeBench reveals how AI coding agents degrade code quality over time—measuring “slop,” technical debt, and architectural erosion across iterations.
January 20, 2026
•
Kobie Crawford
Image
Introducing the Snorkel Agentic Coding Benchmark
Today, we’re sharing details about the Snorkel Agentic Coding benchmark—a comprehensive evaluation suite designed to test whether agents can handle the full complexity of software engineering work.
January 9, 2026
•
Kobie Crawford
Image
2026: The year of environments
We just returned from NeurIPS 2025, and we’re still processing everything we saw. The energy around data-centric AI has never been stronger—and we couldn’t be more grateful to the research community for pushing these ideas forward.
December 10, 2025
•
Snorkel Team
Image
Part V: Future direction and emerging trends
Explores how rubrics support agentic, multi-turn, tool-using, multimodal, and code-generating AI systems, and how they evolve with AI feedback and ensemble evaluation.
December 5, 2025
•
Justin Bauer
The Self-Critique Paradox-2
The self-critique paradox: Why AI verification fails where it’s needed most
TL;DR: We stress-tested the “generate → criticize → improve” loop on 50 visual reasoning tasks. The results were counterintuitive: self-critique acts as a corrosive agent on high-performance tasks, turning 98% accuracy into 57%. Yet, for tasks where models fail completely, it works like magic. This difficulty-dependent behavior poses a critical, hidden risk for RLFT pipelines. The promise vs. the reality
November 26, 2025
•
Armin Parchami
Image
A chat with the Terminal-Bench team
Snorkel Chief Scientist Fred Sala and Kobie Crawford chat with the Terminal-Bench team to unpack the design behind Terminal-Bench 2.0 and the new Harbor framework.
November 19, 2025
•
Fred Sala
,
Kobie Crawford
Intelligence per Watt Snorkel Banner
Intelligence per watt: A new metric for AI’s future
Snorkel AI contributes specialized datasets to Hazy Research’s “Intelligence-per-Watt” study, advancing how efficiently AI turns energy into intelligence.
November 12, 2025
•
Kobie Crawford
Terminal Bench Blog #2 Featured Image
Terminal-Bench 2.0: Raising the bar for AI agent evaluation
Terminal-Bench 2.0 launches today, marking a major leap in AI agent evaluation. Snorkel AI contributed key research and task design to this release.
November 7, 2025
•
Kobie Crawford
Image
Snorkeling in RL environments
We unpack what makes a high-quality RL environment for LLMs and show how we build realistic, enterprise-grade environments at Snorkel AI.
November 4, 2025
•
Armin Parchami
Image
Introducing SnorkelSpatial
A procedurally generated and programmatically verified benchmark for evaluating spatial reasoning capabilities in LLMs Large language models (LLMs) are showing remarkable results on solving complex reasoning problems across domains—from mathematical proofs and logical puzzles to graduate-level science and engineering questions. On the other hand, their spatial reasoning capabilities are less understood, even though such reasoning underlies many everyday tasks. We
October 24, 2025
•
Harit Vishwakarma
Image
Scaling trust: rubrics in Snorkel’s quality process
Snorkel’s “Trusted Scale” philosophy Welcome to Part 4 of Snorkel AI’s rubric series. In previous posts, we explored how rubrics enable structured evaluation (Part 1), the spectrum of rubric types and use cases (Part 2), and the science behind designing and validating them (Part 3). In this latest installment, we pull back the curtain on how Snorkel puts these principles
October 16, 2025
•
Derek Pham
Image
Evaluating multi-agent systems in enterprise tool use
In recent months, there has been increasing interest in the area of multi-agent systems and how they can be used to solve more complex tasks than a single agent could accomplish on its own. The topic is particularly interesting and raises several questions and ideas to consider: Anthropic’s blog post about how they architected a multi-agent deep research system is
October 9, 2025
•
Bhavishya Pohani
Image
Evaluating coding agent capabilities with Terminal-Bench: Snorkel’s role in building the next generation benchmark
Terminal-Bench, developed through a collaboration between Stanford University and Laude Institute, has quickly become the gold standard benchmark for evaluating AI agent capabilities in a command line environment. This comprehensive evaluation framework measures how effectively AI agents can perform complex, real-world tasks within terminal environments. At Snorkel AI, we’re excited to share that we’re one of the top collaborators contributing
September 30, 2025
•
Tom Walshe
,
Kobie Crawford
,
Jeong Shin
Image
Parsing isn’t neutral: why evaluation choices matter
Behind every AI benchmark is a hidden choice: how to read the model’s answers. That choice—parsing—can quietly tilt results more than the model itself. Parsing is where we take an AI system’s raw response and extract the “answer” we use for scoring. It sounds mechanical, but as our research shows, the choice of parser can dramatically change measured accuracy. In
September 26, 2025
•
Justin Bauer