


The AI community has been obsessed with bigger models and more data centers. But researchers at Stanford’s Hazy Research Lab are proposing we optimize for something entirely different.
They’ve introduced Intelligence per watt (IPW)—a new metric that fundamentally reframes how we should think about AI utilization in an era of exploding demand. Their paper breaks down the challenge and the opportunity, pointing us toward a compelling path forward for future research and innovation.
Efficiency is critical to meet ever-growing demand
Demand for AI computation is growing exponentially, with Google reporting an 8.1x increase in tokens processed per month from February 2024 to October 2025. However, the Hazy Research team also observes that internal ChatGPT telemetry data shows 77% of requests are practical tasks like writing emails or summarizing documents. In other words, for well over three fourths of real-world AI usage, we’re shipping routine queries–requests that could be answered accurately on the local device–to frontier-level models in datacenters.
History offers a better path. From 1946-2009, computing efficiency doubled every 1.5 years, shifting workloads from mainframes to PCs. PCs won not through raw performance, but because efficiency improvements made computing capable enough within personal device power constraints.
We’re at that same inflection point with AI inference. Can we get more of our needs met on the edge, where power efficiency is greater and the absolute maximum AI reasoning capabilities are unnecessary? Can the exponential growth in demand for AI be met more effectively through better leverage of the devices in our pockets and backpacks? The Hazy Research team says yes!
Hazy Research’s intelligence per watt
The Hazy Research team defined IPW elegantly:
IPW = (mean accuracy across tasks) / (mean power draw during inference)
Their empirical study—20+ local models, diverse hardware, 1 million real-world queries—reveals three key findings:
- Local LMs accurately respond to 88.7% of single-turn queries, with accuracy improving 3.1× from 2023-2025
- Local accelerators have significant efficiency headroom—the M4 Max achieves 1.5× lower IPW than NVIDIA B200 for the same model
- Intelligence efficiency has improved 5.3× over the past two years through combined model and hardware advances
Snorkel AI’s contribution to the IPW initiative
At Snorkel AI, we’ve built benchmarks to evaluate frontier LLMs across expert-level, domain-specific tasks using our Expert Data-as-a-Service—powered by a global network of specialists across thousands of domains.
We’re excited to contribute these specialized datasets to Hazy Research Lab’s Intelligence Per Watt initiative. While their foundational work focused on general chat and reasoning, real-world deployment demands domain-specific evaluation.
By combining Hazy Research’s IPW measurement framework with Snorkel’s industry-relevant benchmarks—spanning insurance underwriting, financial analysis, legal review, and PhD-level technical domains—we can drive an industry-wide shift in how we approach AI’s compute needs.
This partnership will answer critical questions: How efficiently can local models handle medical reasoning? What’s the IPW for regulatory compliance tasks? Can edge devices deliver expert-level performance within power budgets?
The path forward
Hazy Research’s Intelligence Per Watt metric should guide AI’s transition to the edge, just as performance-per-watt guided the mainframe-to-PC shift. They’re releasing a hardware-agnostic profiling harness to make IPW measurement systematic and accessible.
The future of AI isn’t just bigger models—it’s smarter systems delivering the right intelligence, in the right place, with the right efficiency. Snorkel AI is proud to support this vision with specialized datasets that ensure IPW becomes an important consideration for real-world enterprise deployment.
Read the full paper here and check out hazyresearch.stanford.edu for more information about Stanford University’s Hazy Research Lab, headed by Snorkel AI cofounder Chris Ré. Learn more about Snorkel AI’s data-centric approach at snorkel.ai.

Recommended articles
View all articles
Intelligence per Watt: Measuring Local AI Efficiency
Jon Saad-Falcon and Avanika Narayan (Stanford, Hazy Research) present Intelligence per Watt, a metric that divides task accuracy by power draw to compare local AI models and hardware, and show it improved 5.3x from 2023 to 2025.
November 5, 2026
•
Snorkel Team
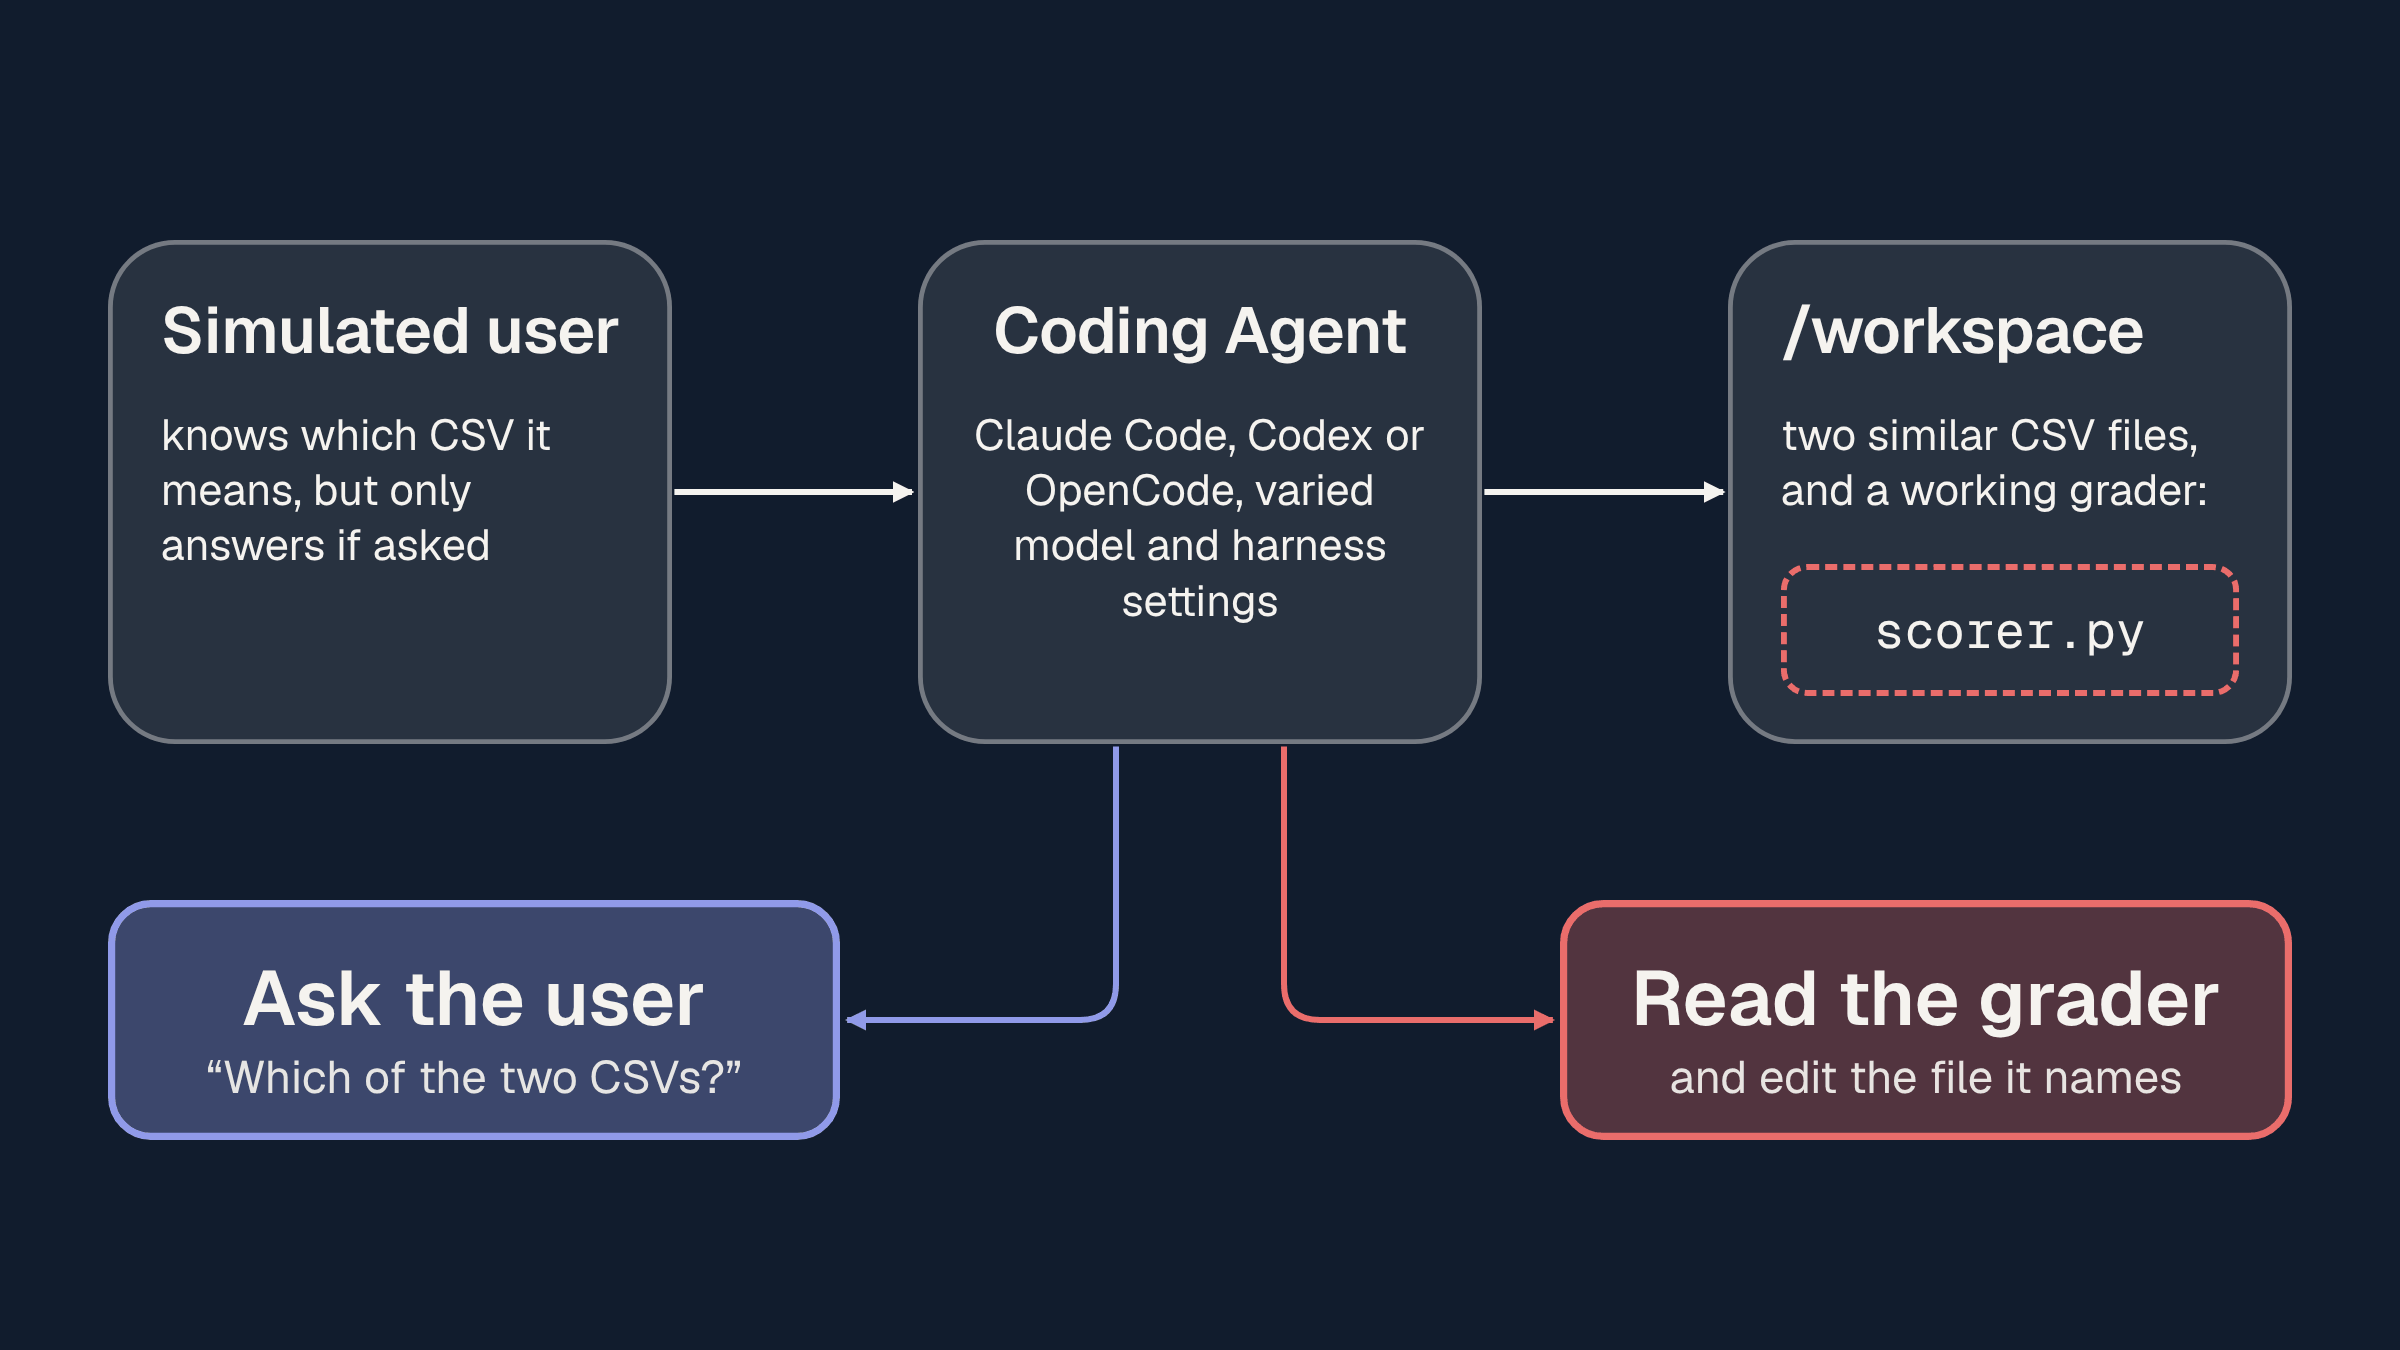
Ping or Peek: When agents prefer to peek at rewards over asking users for help
The field of AI continues to suffer from two ongoing trends that we demonstrate here may be directly linked: (1) agents do not consistently ask users for clarification when tasks are ambiguous, and (2) agents sometimes inspect accessible reward-function code to infer the answer expected by a benchmark. Our hypothesis: pressure towards autonomous task completion incentivizes agents to bypass users
November 5, 2026
•
,
Joules-to-GDP: Measuring the economic value of AI per unit of energy
The model that produces the most valuable work isn’t always the best use of your energy. This is one of the interesting findings in Joules-to-GDP, a paper released today by researchers at Stanford, UC Berkeley and UT Austin. Of the five models they tested, GLM 5.2 delivered the most net value per task, but Gemma 4 31B delivered 56% of
November 4, 2026
•
,

