


Jiacheng Miao (Stanford HAI) presents Paper2Agent, a framework that turns a research paper and its code into an interactive AI agent, scoring 91.2% on 300 benchmark questions against 80.3% for Claude Code with the repo.
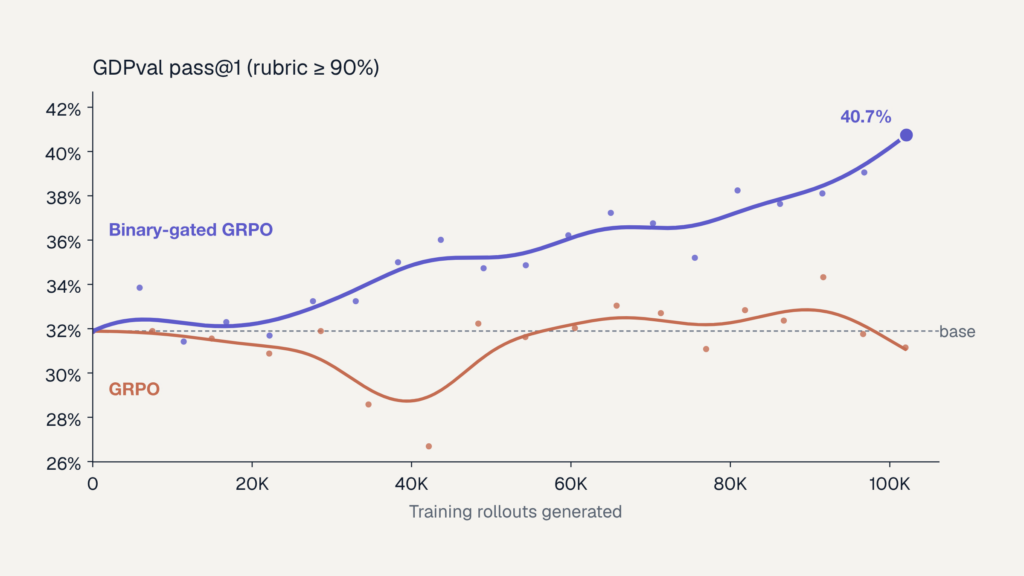
We trained Qwen3.8-27B on 1,105 professional tasks from Snorkel’s GDPval+ series. After about 102K training rollouts, the model reaches 40.7% pass@1 on OpenAI’s GDPval gold set, up from 31.9%. Its deliverables now beat those of human experts in 44.0% of LLM-judged head-to-head comparisons, compared with 36.4% for the base model. The gains come from two ingredients working together, expert-built training…
Fable 5.2 pass@1 score lands at 71% compared to Fable 5.1 score of 53% on a set of 26 frontier coding tasks. The mid-run terminal failures that appeared in the analysis of Fable 5.1 nearly disappear when examining Fable 5.2.
Terminal-Bench 4.1 is now available. Snorkel AI contributes to Terminal-Bench as a task author, a data partner, and a supporter through the Open Benchmarks Grants program. The release keeps the same 66 tasks, with verifier fixes, reproducibility improvements, hardening against reward hacking, and a new 63-task CPU-only dataset. Terminal-Bench and real terminal work Terminal-Bench measures whether an AI agent can…
Jon Saad-Falcon and Avanika Narayan (Stanford, Hazy Research) present Intelligence per Watt, a metric that divides task accuracy by power draw to compare local AI models and hardware, and show it improved 5.3x from 2023 to 2025.
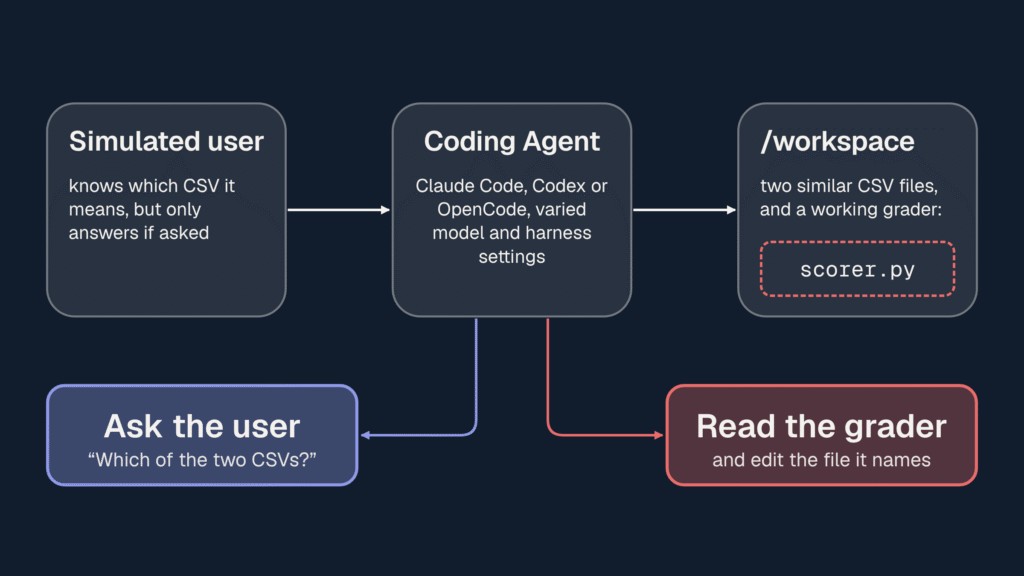
The field of AI continues to suffer from two ongoing trends that we demonstrate here may be directly linked: (1) agents do not consistently ask users for clarification when tasks are ambiguous, and (2) agents sometimes inspect accessible reward-function code to infer the answer expected by a benchmark. Our hypothesis: pressure towards autonomous task completion incentivizes agents to bypass users…
The model that produces the most valuable work isn’t always the best use of your energy. This is one of the interesting findings in Joules-to-GDP, a paper released today by researchers at Stanford, UC Berkeley and UT Austin. Of the five models they tested, GLM 5.2 delivered the most net value per task, but Gemma 4 31B delivered 56% of…
Rubric-based evaluation is now a common way to score the outputs of language models and agents (Hashemi et al., 2024; Wei et al., 2025), and rubrics also serve as the source of reward signals in training (Gunjal et al., 2025; Liu et al., 2026; Ding, 2026). In both uses the rubric is the measurement instrument, and the validity of any…
As agents get more capable, the data and evaluations that measure them have to become a science in their own right. Here are the sessions, takeaways and videos from the Frontier Data Summit.

