

author
Ph.D. candidate
,
Brown University
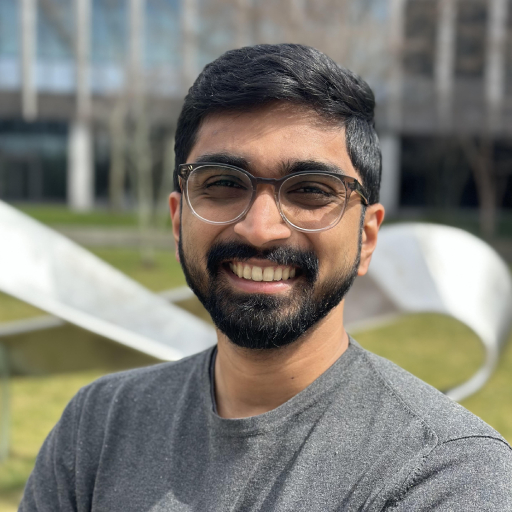
Nihal V. Nayak is a fifth-year Ph.D. student in the Department of Computer Science at Brown University, where he is advised by Stephen H. Bach. His research focuses on zero-shot generalization in deep neural networks and, more broadly, on learning with limited labeled data. His work has been published in leading machine learning conferences and journals, including ICLR, TMLR, ACL Demo, EACL Findings, and MLSys.
The latest from Nihal

Learning to Generate Instruction Tuning Datasets for Zero-Shot Task Adaptation
We introduce Bonito, an open-source model for conditional task generation that converts unannotated text into task-specific training datasets for instruction tuning. We aim to enable zeroshot task adaptation of large language models on users’ specialized, private data. We train Bonito by fine-tuning a pretrained large language model on a new large-scale dataset with 1.65M examples created by remixing existing instruction tuning datasets into metatemplates. The meta-templates for a dataset produce training examples where the input is the unannotated text and the task attribute and the output consists of the instruction and the response. We use Bonito to generate synthetic tasks...
Research Paper
Learning to Generate Instruction Tuning Datasets for Zero-Shot Task Adaptation
We introduce Bonito, an open-source model for conditional task generation that converts unannotated text into task-specific training datasets for instruction tuning. We aim to enable zeroshot task adaptation of large language models on users’ specialized, private data. We train Bonito by fine-tuning a pretrained large language model on a new large-scale dataset with 1.65M examples created by remixing existing instruction…

Blog
How Bonito helps fine-tune specialized LLMs faster than ever
Fine-tuning specialized LLMs demands a lot of time and cost We developed Bonito to make this process faster, cheaper, and easier.
Learning to Generate Instructions to Adapt Language Models to New Tasks
We present Bonito, the first open-source model for conditional task generation: the problem of converting unannotated corpus into a collection of tasks for instruction tuning. Our goal is to enable efficient task adaptation of instruction tuned language models on users' specialized, private data without relying on proprietary API-access-only models like GPT-4. We create Bonito by remixing existing, general-purpose instruction tuning data into a new training mixture for conditional task generation. Bonito learns to generate new tasks conditioned on the text and desired task type. The generated instructions in the specialized domain can be used to further train language models. We...
Research Paper
Learning to Generate Instructions to Adapt Language Models to New Tasks
We present Bonito, the first open-source model for conditional task generation: the problem of converting unannotated corpus into a collection of tasks for instruction tuning. Our goal is to enable efficient task adaptation of instruction tuned language models on users’ specialized, private data without relying on proprietary API-access-only models like GPT-4. We create Bonito by remixing existing, general-purpose instruction tuning…
Bloom: A 176b-parameter open-access multilingual language model
Large language models (LLMs) have been shown to be able to perform new tasks based on a few demonstrations or natural language instructions. While these capabilities have led to widespread adoption, most LLMs are developed by resource-rich organizations and are frequently kept from the public. As a step towards democratizing this powerful technology, we present BLOOM, a 176B-parameter open-access language model designed and built thanks to a collaboration of hundreds of researchers. BLOOM is a decoder-only Transformer language model that was trained on the ROOTS corpus, a dataset comprising hundreds of sources in 46 natural and 13 programming languages (59...
Research Paper
Bloom: A 176b-parameter open-access multilingual language model
Large language models (LLMs) have been shown to be able to perform new tasks based on a few demonstrations or natural language instructions. While these capabilities have led to widespread adoption, most LLMs are developed by resource-rich organizations and are frequently kept from the public. As a step towards democratizing this powerful technology, we present BLOOM, a 176B-parameter open-access language…
Does CLIP Bind Concepts? Probing Compositionality in Large Image Models
Large-scale neural network models combining text and images have made incredible progress in recent years.However, it remains an open question to what extent such models encode compositional representations of the concepts over which they operate, such as correctly identifying red cube by reasoning over the constituents red and cube.In this work, we focus on the ability of a large pretrained vision and language model (CLIP) to encode compositional concepts and to bind variables in a structure-sensitive way (e.g., differentiating cube behind sphere from sphere behind cube).To inspect the performance of CLIP, we compare several architectures from research on compositional distributional...
Research Paper
Does CLIP Bind Concepts? Probing Compositionality in Large Image Models
Large-scale neural network models combining text and images have made incredible progress in recent years.However, it remains an open question to what extent such models encode compositional representations of the concepts over which they operate, such as correctly identifying red cube by reasoning over the constituents red and cube.In this work, we focus on the ability of a large pretrained…

Tasks Algorithmically Given Labels Established via Transferred Symbols (TAGLETS)
We conducted research to reduce the amount of labeled data required to train machine learning systems. The pinnacle of this effort is the development of TAGLETS, a machine learning system that seamlessly integrates widely known collections of labeled data with a diverse array of machine learning algorithms, known as weak labelers. The system's evolution has been significantly influenced by comprehensive theoretical explorations into effectively aggregating these weak labelers within the system. The research's scope expands to the application of large pre-trained models in low-resource settings. The result of these efforts is Alfred, a second-generation system tailored for programmatic weak supervision...
Research Paper
Tasks Algorithmically Given Labels Established via Transferred Symbols (TAGLETS)
We conducted research to reduce the amount of labeled data required to train machine learning systems. The pinnacle of this effort is the development of TAGLETS, a machine learning system that seamlessly integrates widely known collections of labeled data with a diverse array of machine learning algorithms, known as weak labelers. The system’s evolution has been significantly influenced by comprehensive…

Learning to Compose Soft Prompts for Compositional Zero-Shot Learning
We introduce compositional soft prompting (CSP), a parameter-efficient learning technique to improve the zero-shot compositionality of large-scale pretrained vision-language models (VLMs) like CLIP. We develop CSP for compositional zero-shot learning, the task of predicting unseen attribute-object compositions (e.g., old cat and young tiger). VLMs have a flexible text encoder that can represent arbitrary classes as natural language prompts but they often underperform taskspecific architectures on the compositional zero-shot benchmark datasets. CSP treats the attributes and objects that define classes as learnable tokens of vocabulary. During training, the vocabulary is tuned to recognize classes that compose tokens in multiple ways (e.g.,...
Research Paper
Learning to Compose Soft Prompts for Compositional Zero-Shot Learning
We introduce compositional soft prompting (CSP), a parameter-efficient learning technique to improve the zero-shot compositionality of large-scale pretrained vision-language models (VLMs) like CLIP. We develop CSP for compositional zero-shot learning, the task of predicting unseen attribute-object compositions (e.g., old cat and young tiger). VLMs have a flexible text encoder that can represent arbitrary classes as natural language prompts but they…

Zero-Shot Learning with Common Sense Knowledge Graphs
Zero-shot learning relies on semantic class representations such as hand-engineered attributes or learned embeddings to predict classes without any labeled examples. We propose to learn class representations by embedding nodes from common sense knowledge graphs in a vector space. Common sense knowledge graphs are an untapped source of explicit high-level knowledge that requires little human effort to apply to a range of tasks. To capture the knowledge in the graph, we introduce ZSL-KG, a general-purpose framework with a novel transformer graph convolutional network (TrGCN) for generating class representations. Our proposed TrGCN architecture computes non-linear combinations of node neighbourhoods. Our results...
Research Paper
Zero-Shot Learning with Common Sense Knowledge Graphs
Zero-shot learning relies on semantic class representations such as hand-engineered attributes or learned embeddings to predict classes without any labeled examples. We propose to learn class representations by embedding nodes from common sense knowledge graphs in a vector space. Common sense knowledge graphs are an untapped source of explicit high-level knowledge that requires little human effort to apply to a…

PromptSource: An Integrated Development Environment and Repository for Natural Language Prompts
PromptSource is a system for creating, sharing, and using natural language prompts. Prompts are functions that map an example from a dataset to a natural language input and target output. Using prompts to train and query language models is an emerging area in NLP that requires new tools that let users develop and refine these prompts collaboratively. PromptSource addresses the emergent challenges in this new setting with (1) a templating language for defining data-linked prompts, (2) an interface that lets users quickly iterate on prompt development by observing outputs of their prompts on many examples, and (3) a community-driven set...
Research Paper
PromptSource: An Integrated Development Environment and Repository for Natural Language Prompts
PromptSource is a system for creating, sharing, and using natural language prompts. Prompts are functions that map an example from a dataset to a natural language input and target output. Using prompts to train and query language models is an emerging area in NLP that requires new tools that let users develop and refine these prompts collaboratively. PromptSource addresses the…

