


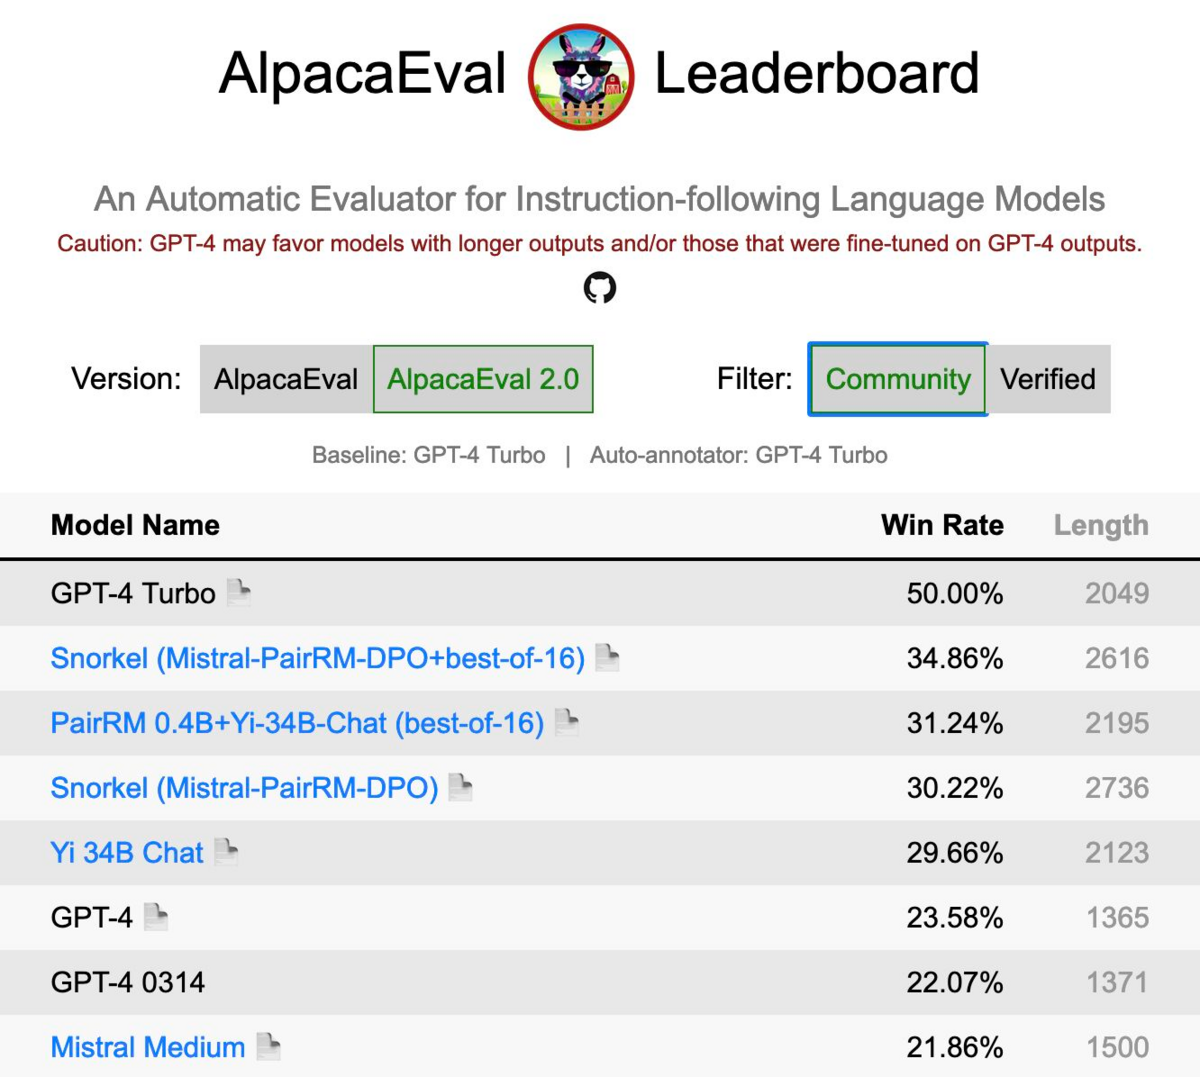
We have some cool news to share! Snorkel AI ranked 2nd, behind only GPT-4 Turbo, in our recent submission to AlpacaEval 2.0 LLM leaderboard. This benchmark measures the ability of well-known LLMs such as Gemini, Claude 2, Llama 2, Mixtral, etc. to follow general user instructions. This result was achieved with only an open-source 7B parameter model, thanks to Snorkel AI’s state-of-the-art methods for LLM customization.
Try out the new 7B model that put Snorkel AI in second place on AlpacaEval 2.0! Download, sandbox, or API calls.
Snorkel AI has long championed the idea that AI teams can get better results faster by replacing highly manual data annotation with programmatic approaches that more efficiently capture and apply subject matter expertise. Snorkel Flow is our data development platform that helps companies like Wayfair and BNY Mellon to fine-tune and align generative models with these programmatic approaches, and today’s result demonstrates the value of a key component of that technology.
Alignment methods such as reinforcement learning from human feedback (RLHF) and direct process optimization (DPO) are typically used as the last step in LLM development to customize a model to match user preferences. That preference data has historically been collected in the form of manual annotations, which are then used to train a reward model for RLHF. DPO has recently emerged as a more stable and performant alternative that utilizes pairs of annotated responses directly. With programmatic alignment, we use a hybrid approach aimed at getting the best of both worlds. First, users rapidly supervise a custom reward model with programmatic labels generated in Snorkel Flow. Second, that reward model is used in conjunction with the LLM being aligned to create high volumes of high quality pairs for use with DPO. The result is a model that is aligned to your preferences, on your data, without a slow and expensive manual labeling process.
AlpacaEval is a general-purpose benchmark, so an off-the-shelf, general-purpose reward model (we used PairRM) sufficed to achieve this strong result without any additional task-specific programmatic data development. The model was fine-tuned and trained using Microsoft Azure A100 GPUs. Ongoing work includes building on this result with publicly shareable demonstrations of the full programmatic alignment pipeline in more business-specific use cases that are not well-represented by general-purpose benchmarks such as AlpacaEval.
To learn more about this research, join us at our LLM Summit, where researcher Hoang Tran will walk through programmatic alignment in more detail. Follow us on social media for future updates from our research team on state-of-the-art methods for LLM customization!
More Snorkel AI events coming!
Snorkel has more live online events coming. Look at our events page to sign up for research webinars, product overviews, and case studies.
If you're looking for more content immediately, check out our YouTube channel, where we keep recordings of our past webinars and online conferences.
Recommended articles
View all articles

MedPAIR: Measuring Whether Physicians and AI Agree on What Matters in Medical QA
Yuexing Hao presents MedPAIR, a dataset comparing which sentences physicians and LLMs find relevant in clinical questions. Humans and LLMs agree on only 50 to 60% of relevance labels.
October 2, 2026
•
Snorkel Team

RL environments for LLM agents: Design, rewards, and validation
TLDR: An agent, by definition, can take actions and is more than just a language model. The model is only one part of the system, and is only one element that you are training. The environment determines what the agent can observe, what it can change, which actions are available, and what behavior receives a reward. For a coding agent,
September 28, 2026
•
,

Opus 5.5 vs Opus 5 vs Fable 5.1: Coding Benchmark Results
We’ve now run three generations of frontier models through the same expert-created terminal-bench style task set: Fable 5.1 in September, Opus 5 in July, and, now Opus 5.5. For this analysis, the task set contained 200 trajectories, of 24 tasks, with every failure traced to a judge-confirmed root cause. A generational climb On the task set, pass@1 is 61.5% for
September 23, 2026
•
,

