


Applied AI
April 7, 2022
•
4 min read
•
The adoption of trustworthy AI and its successful integration into our country’s most critical systems is paramount to achieving the goal of employing AI applications to accelerate economic prosperity and national security. However, traditional approaches to developing AI applications suffer from a critical flaw that leads to significant ethics and governance concerns. Specifically, AI today relies on massive, hand-labeled training datasets and/or black-box “pre-trained” models that are effectively ungovernable and unauditable.
The need for trustworthy AI
Snorkel AI supports customers in highly-regulated industries such as finance, healthcare, government, and others. These industries are adapting to new AI ethics standards which require explaining and justifying how AI/ML systems are designed and/or how they produce a given result.
New methodologies are being developed to ensure trustworthy AI (sometimes called Responsible AI). While models and applications built with these methodologies are not error-proof, they are designed to be explainable, auditable, and governable.
Snorkel AI’s trustworthy AI advantage
In order to build Trustworthy AI frameworks institutions face five key requirements:
- Govern & audit the data that AI learns from
- Explain AI decisions & errors
- Correct biases in AI systematically
- Allow feedback between labeling & training
- Ensure supply chain integrity for AI/ML
In this series of articles, published over the coming weeks, we will describe each of these requirements in detail and demonstrate:
- How traditional approaches to developing AI applications based on hand-labeled ML training data are key blockers to these requirements for governable, ethical AI.
- How methodologies developed to mitigate these blockers continue to have shortcomings and fall short of the goal.
- How Snorkel Flow, with its core capability to programmatically label and manage training data, instead of by hand, overcomes these challenges.
Don’t miss the opportunity to explore approaches to help our government agencies effectively and efficiently leverage Trustworthy AI. Join us at this insightful online event bringing experts on the federal and defense lines on April 21, 2022, at 12:00 ET.
Trustworthy AI: Governance and auditability
In order to achieve Trustworthy AI, an organization must have visibility into several aspects of the training data, including understanding how it was created and labeled, along with having a mechanism for monitoring and analyzing its use. In other words, they must govern & audit the data that the AI learns from.
Challenge: Auditing hand-labeled training data
If a dataset is labeled by hand, the only way to check the assigned labels for policy compliance or bias is to review it by hand. A full review could require point-by-point manual inspection of hundreds of thousands, or even millions, of individual records.
Snorkel Flow advantage
Labeled training data is the key component to building AI/ML applications. Programmatic labeling allows you to actually govern and audit this data effectively.
Snorkel’s use of labeling functions, which capture the user-defined rationale behind the data labeling process (expressible as both formal business logic or Python code), allows you to govern and audit training data the same way you’d govern and audit software code.
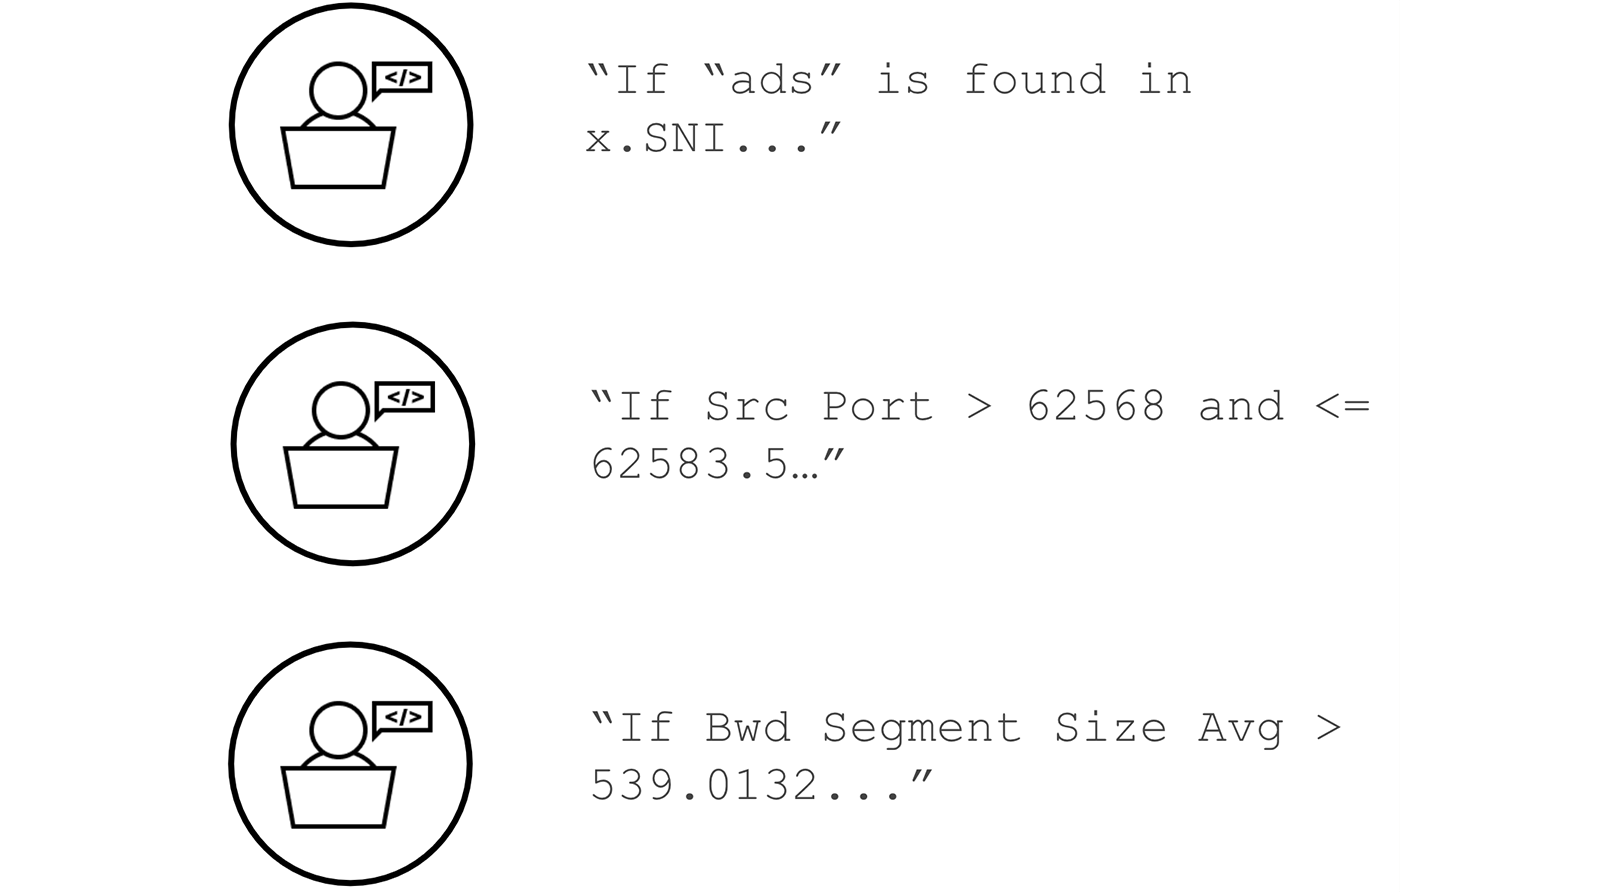
All labeling functions compile to easily exportable and human-readable Python Code
Each step of the process of building an AI application in Snorkel Flow – the labeling functions, the programmatically-labeled datasets, the trained ML models, and more – is also subject to version control to enable transparency, analysis, and reproducibility of the entire development lifecycle.
Snorkel AI has been successful in delivering products and results to multiple federal government partners. To speak with our federal team about how Snorkel AI can support your efforts at understanding and developing trustworthy and responsible AI applications, contact federal@snorkel.ai.
Recommended articles
View all articles
Checking the Rubrics: RIFT Results on Five Public Benchmarks
Rubric-based evaluation is now a common way to score the outputs of language models and agents (Hashemi et al., 2024; Wei et al., 2025), and rubrics also serve as the source of reward signals in training (Gunjal et al., 2025; Liu et al., 2026; Ding, 2026). In both uses the rubric is the measurement instrument, and the validity of any
October 23, 2026
•
,
,
,
Frontier Data Summit 2026 Recap
As agents get more capable, the data and evaluations that measure them have to become a science in their own right. Here are the sessions, takeaways and videos from the Frontier Data Summit.
October 16, 2026
•
Snorkel Team

When Partial Credit Opposes Completion
AI agents are increasingly trusted with long, open-ended work. They fix bugs across large repositories, operate terminals for hours, and chain numerous tool calls toward a single goal. The strongest models now solve a meaningful share of such tasks, yet on the hardest ones failure is still the common outcome, and closing that gap is one of the central problems
October 15, 2026
•

