


Vincent Sunn Chen spoke at AI Engineer London about what it actually takes to build AI benchmarks that move the field forward, not just measure it.
The throughline is an asymmetry that keeps showing up across deployments and the 150+ proposals reviewed for the Open Benchmarks Grants: agent capabilities are climbing fast, but the ability to measure those agents with rigorous AI benchmarks in realistic, high-stakes settings has lagged behind. Closing that evaluation gap is one of the most important problems in AI right now — and open benchmarks are one of the most powerful levers available to address it.
In the talk, Vincent breaks the problem into two halves. The first is the science of an effective measuring stick — rigorous task quality, deliberate distributional diversity, real model headroom, and a robust evaluation methodology — illustrated with benchmarks like GPQA, MMLU, ARC-AGI, and τ-bench. The second is the art that separates benchmarks that merely measure from the ones that reshape the field: a clear thesis on where things are going, a roadmap others can build on, and first-class researcher UX — think Terminal-Bench, SWE-bench, and HELM. The talk closes with a look at where the next great benchmarks may emerge: environment complexity, autonomy horizon, and output complexity.

If you want to go deeper than the talk, the two pieces below are the fuller written versions:
- For the framework: what makes an AI benchmark a useful measuring stick, and what makes one shape the frontier (Benchmarks should shape the frontier, not just measure it).
- For the forward-looking view: the three axes where tomorrow’s AI benchmarks need to push hardest (Closing the Evaluation Gap in Agentic AI).
And if any of this maps to what you’re building, the Open Benchmarks Grants are open: a $3M commitment to fund open benchmarks, datasets, and evaluation artifacts for frontier agents. Share a proposal or reach out at benchmarks.snorkel.ai.
Recommended articles
View all articles
Intelligence per Watt: Measuring Local AI Efficiency
Jon Saad-Falcon and Avanika Narayan (Stanford, Hazy Research) present Intelligence per Watt, a metric that divides task accuracy by power draw to compare local AI models and hardware, and show it improved 5.3x from 2023 to 2025.
November 5, 2026
•
Snorkel Team
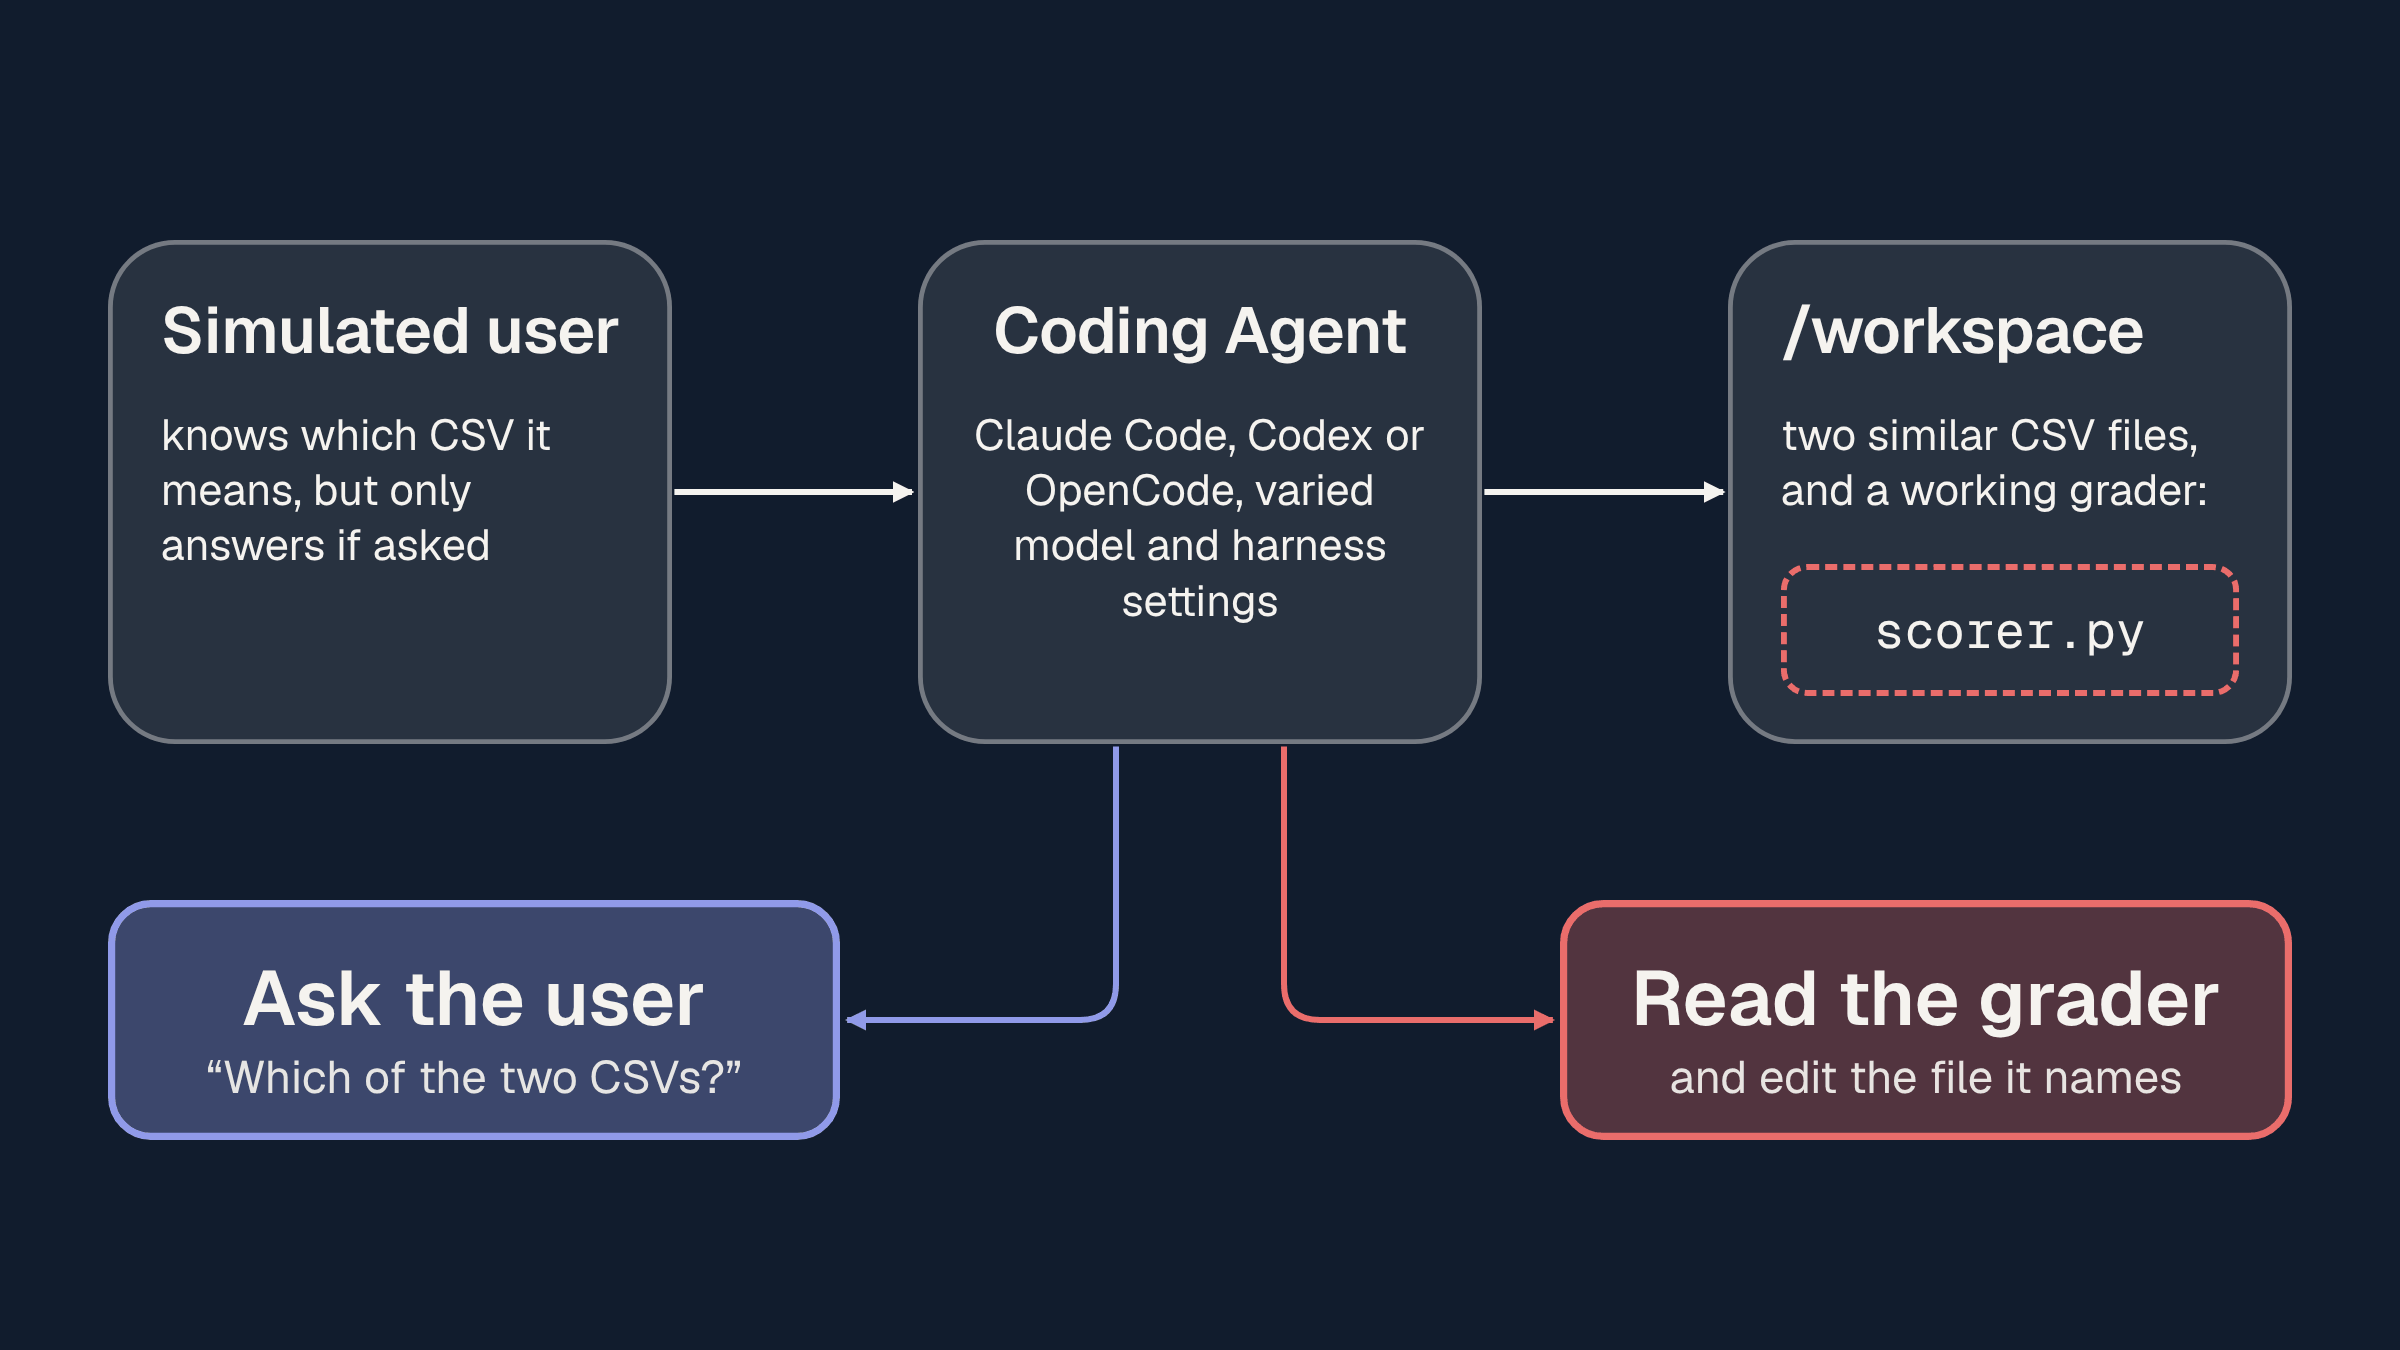
Ping or Peek: When agents prefer to peek at rewards over asking users for help
The field of AI continues to suffer from two ongoing trends that we demonstrate here may be directly linked: (1) agents do not consistently ask users for clarification when tasks are ambiguous, and (2) agents sometimes inspect accessible reward-function code to infer the answer expected by a benchmark. Our hypothesis: pressure towards autonomous task completion incentivizes agents to bypass users
November 5, 2026
•
,
Joules-to-GDP: Measuring the economic value of AI per unit of energy
The model that produces the most valuable work isn’t always the best use of your energy. This is one of the interesting findings in Joules-to-GDP, a paper released today by researchers at Stanford, UC Berkeley and UT Austin. Of the five models they tested, GLM 5.2 delivered the most net value per task, but Gemma 4 31B delivered 56% of
November 4, 2026
•
,

