

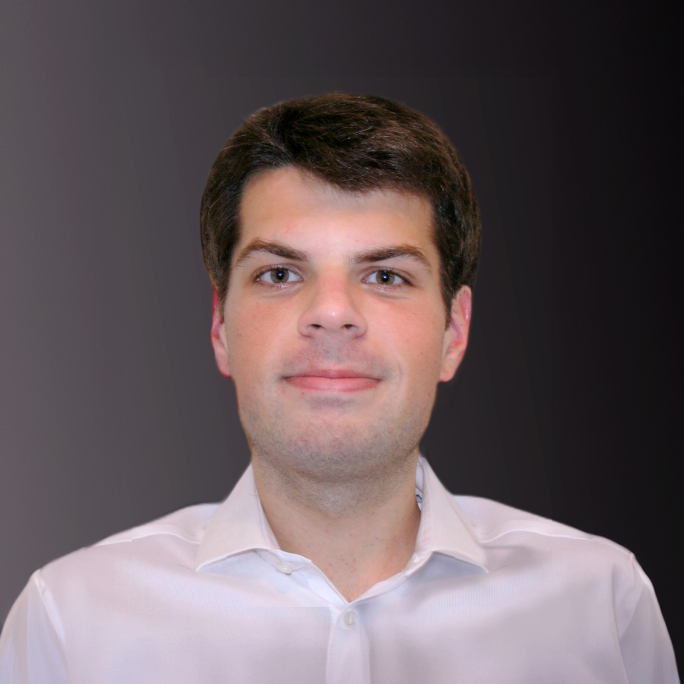
author
Chief Scientist
,
Snorkel AI
Assistant Professor @ University of Wisconsin-Madison
Frederic Sala is Chief Scientist at Snorkel AI and an assistant professor in the Computer Sciences Department at the University of Wisconsin-Madison. His research studies the fundamentals of data-driven systems and machine learning, with a focus on data-centric AI, foundation models, and automated machine learning. He and his group received the 2024 DARPA Young Faculty Award, a best student paper runner-up award at UAI ’22, the outstanding Ph.D. dissertation award from the UCLA Department of Electrical Engineering, the NSF Graduate Research Fellowship.
The latest from Fred

Hidden network generating rules from partially observed complex networks
Complex biological, neuroscience, geoscience and social networks exhibit heterogeneous self-similar higher order topological structures that are usually characterized as being multifractal in nature. However, describing their topological complexity through a compact mathematical description and deciphering their topological governing rules has remained elusive and prevented a comprehensive understanding of networks. To overcome this challenge, we propose a weighted multifractal graph model capable of capturing the underlying generating rules of complex systems and characterizing their node heterogeneity and pairwise interactions. To infer the generating measure with hidden information, we introduce a variational expectation maximization framework. We demonstrate the robustness of the network...
Research Paper
Hidden network generating rules from partially observed complex networks
Complex biological, neuroscience, geoscience and social networks exhibit heterogeneous self-similar higher order topological structures that are usually characterized as being multifractal in nature. However, describing their topological complexity through a compact mathematical description and deciphering their topological governing rules has remained elusive and prevented a comprehensive understanding of networks. To overcome this challenge, we propose a weighted multifractal graph model…

Comparing the Value of Labeled and Unlabeled Data in Method-of-Moments Latent Variable Estimation
Labeling data for modern machine learning is expensive and time-consuming. Latent variable models can be used to infer labels from weaker, easier-to-acquire sources operating on unlabeled data. Such models can also be trained using labeled data, presenting a key question: should a user invest in few labeled or many unlabeled points? We answer this via a framework centered on model misspecification in method-of-moments latent variable estimation. Our core result is a bias-variance decomposition of the generalization error, which shows that the unlabeled-only approach incurs additional bias under misspecification. We then introduce a correction that provably removes this bias in certain...
Research Paper
Comparing the Value of Labeled and Unlabeled Data in Method-of-Moments Latent Variable Estimation
Labeling data for modern machine learning is expensive and time-consuming. Latent variable models can be used to infer labels from weaker, easier-to-acquire sources operating on unlabeled data. Such models can also be trained using labeled data, presenting a key question: should a user invest in few labeled or many unlabeled points? We answer this via a framework centered on model…

Cut out the annotator, keep the cutout: better segmentation with weak supervision
Constructing large, labeled training datasets for segmentation models is an expensive and labor-intensive process. This is a common challenge in machine learning, addressed by methods that require few or no labeled data points such as few-shot learning (FSL) and weakly-supervised learning (WS). Such techniques, however, have limitations when applied to image segmentation—FSL methods often produce noisy results and are strongly dependent on which few datapoints are labeled, while WS models struggle to fully exploit rich image information. We propose a framework that fuses FSL and WS for segmentation tasks, enabling users to train high-performing segmentation networks with very few hand-labeled...
Research Paper
Cut out the annotator, keep the cutout: better segmentation with weak supervision
Constructing large, labeled training datasets for segmentation models is an expensive and labor-intensive process. This is a common challenge in machine learning, addressed by methods that require few or no labeled data points such as few-shot learning (FSL) and weakly-supervised learning (WS). Such techniques, however, have limitations when applied to image segmentation—FSL methods often produce noisy results and are strongly…

Fast and Three-Rious: Speed up Weak Supervision With Triplet Methods
Weak supervision is a popular method for building machine learning models without relying on ground truth annotations. Instead, it generates probabilistic training labels by estimating the accuracies of multiple noisy labeling sources (e.g., heuristics, crowd workers). Existing approaches use latent variable estimation to model the noisy sources, but these methods can be computationally expensive, scaling superlinearly in the data. In this work, we show that, for a class of latent variable models highly applicable to weak supervision, we can find a closed-form solution to model parameters, obviating the need for iterative solutions like stochastic gradient descent (SGD). We use this...
Research Paper
Fast and Three-Rious: Speed up Weak Supervision With Triplet Methods
Weak supervision is a popular method for building machine learning models without relying on ground truth annotations. Instead, it generates probabilistic training labels by estimating the accuracies of multiple noisy labeling sources (e.g., heuristics, crowd workers). Existing approaches use latent variable estimation to model the noisy sources, but these methods can be computationally expensive, scaling superlinearly in the data. In…

Train and You’ll Miss It: Interactive Model Iteration With Weak Supervision…
Our goal is to enable machine learning systems to be trained interactively. This requires models that perform well and train quickly, without large amounts of hand-labeled data. We take a step forward in this direction by borrowing from weak supervision (WS), wherein models can be trained with noisy sources of signal instead of hand-labeled data. But WS relies on training downstream deep networks to extrapolate to unseen data points, which can take hours or days. Pre-trained embeddings can remove this requirement. We do not use the embeddings as features as in transfer learning (TL), which requires fine-tuning for high performance,...
Research Paper
Train and You’ll Miss It: Interactive Model Iteration With Weak Supervision…
Our goal is to enable machine learning systems to be trained interactively. This requires models that perform well and train quickly, without large amounts of hand-labeled data. We take a step forward in this direction by borrowing from weak supervision (WS), wherein models can be trained with noisy sources of signal instead of hand-labeled data. But WS relies on training…

Low-Dimensional Hyperbolic Knowledge Graph Embeddings
Knowledge graph (KG) embeddings learn lowdimensional representations of entities and relations to predict missing facts. KGs often exhibit hierarchical and logical patterns which must be preserved in the embedding space. For hierarchical data, hyperbolic embedding methods have shown promise for high-fidelity and parsimonious representations. However, existing hyperbolic embedding methods do not account for the rich logical patterns in KGs. In this work, we introduce a class of hyperbolic KG embedding models that simultaneously capture hierarchical and logical patterns. Our approach combines hyperbolic reflections and rotations with attention to model complex relational patterns. Experimental results on standard KG benchmarks show that...
Research Paper
Low-Dimensional Hyperbolic Knowledge Graph Embeddings
Knowledge graph (KG) embeddings learn lowdimensional representations of entities and relations to predict missing facts. KGs often exhibit hierarchical and logical patterns which must be preserved in the embedding space. For hierarchical data, hyperbolic embedding methods have shown promise for high-fidelity and parsimonious representations. However, existing hyperbolic embedding methods do not account for the rich logical patterns in KGs. In…
Ivy: Instrumental Variable Synthesis for Causal Inference
A popular way to estimate the causal effect of a variable x on y from observational data is to use an instrumental variable (IV): a third variable z that affects y only through x. The more strongly z is associated with x, the more reliable the estimate is, but such strong IVs are difficult to find. Instead, practitioners combine more commonly available IV candidates—which are not necessarily strong, or even valid, IVs—into a single "summary" that is plugged into causal effect estimators in place of an IV. In genetic epidemiology, such approaches are known as allele scores. Allele scores require...
Research Paper
Ivy: Instrumental Variable Synthesis for Causal Inference
A popular way to estimate the causal effect of a variable x on y from observational data is to use an instrumental variable (IV): a third variable z that affects y only through x. The more strongly z is associated with x, the more reliable the estimate is, but such strong IVs are difficult to find. Instead, practitioners combine more…

Training Complex Models with Multi-Task Weak Supervision
As machine learning models continue to increase in complexity, collecting large hand-labeled training sets has become one of the biggest roadblocks in practice. Instead, weaker forms of supervision that provide noisier but cheaper labels are often used. However, these weak supervision sources have diverse and unknown accuracies, may output correlated labels, and may label different tasks or apply at different levels of granularity. We propose a framework for integrating and modeling such weak supervision sources by viewing them as labeling different related sub-tasks of a problem, which we refer to as the multi-task weak supervision setting. We show that by...
Research Paper
Training Complex Models with Multi-Task Weak Supervision
As machine learning models continue to increase in complexity, collecting large hand-labeled training sets has become one of the biggest roadblocks in practice. Instead, weaker forms of supervision that provide noisier but cheaper labels are often used. However, these weak supervision sources have diverse and unknown accuracies, may output correlated labels, and may label different tasks or apply at different…
Multi-Resolution Weak Supervision for Sequential Data
Since manually labeling training data is slow and expensive, recent industrial and scientific research efforts have turned to weaker or noisier forms of supervision sources. However, existing weak supervision approaches fail to model multi-resolution sources for sequential data, like video, that can assign labels to individual elements or collections of elements in a sequence. A key challenge in weak supervision is estimating the unknown accuracies and correlations of these sources without using labeled data. Multi-resolution sources exacerbate this challenge due to complex correlations and sample complexity that scales in the length of the sequence. We propose Dugong, the first framework...
Research Paper
Multi-Resolution Weak Supervision for Sequential Data
Since manually labeling training data is slow and expensive, recent industrial and scientific research efforts have turned to weaker or noisier forms of supervision sources. However, existing weak supervision approaches fail to model multi-resolution sources for sequential data, like video, that can assign labels to individual elements or collections of elements in a sequence. A key challenge in weak supervision…

