

We develop methods, benchmarks, and training systems that turn expert data into frontier AI
building benchmarks and collaborating with


Featured research

Senior SWE-bench built by Snorkel with Princeton University and UW-Madison

Continual Learning Bench: Evaluating agents that adapt and improve over time

Learning from Less: Measuring the Effectiveness of RLVR in Low Data Compute Regimes

Agents' Last Exam: Challenge and measure AI agents on economically valuable and real-world tasks

SlopCodeBench: A community benchmark measuring code erosion

Harvey’s BigLaw Bench: Research

Terminal-Bench 2.0: Raising the bar for AI agent evaluation

Benchmarking Agents in Insurance Underwriting Environments

Agentic Coding benchmark: Evaluating AI Models on complex, real-world coding tasks
Vision and impact
We help labs advance frontier models by working with domain experts to design and build complex, realistic datasets that drive model performance.

Benchmarking & Evaluation
Build benchmarks that define and advance the AI frontier

Scaling Subject Matter Expertise
Define how subject matter experts encode their knowledge into data

RL, Training, & Data Valuation
Drive dataset development based on feedback from RL and model training
Community and open science
Open benchmarks, conversations, and research for real-world AI performance.

Open Benchmarks Grants
Backed by a $30M commitment, Open Benchmarks Grants funds new benchmarks, red-teams existing ones to find weaknesses, and supports researchers through a fellowship.

Benchtalks

Reading Group
DEEP RESEARCH Expertise
Technical advisors and distinguished affiliates


Browse research blogs and academic papers
Fable 5.2 pass@1 score lands at 71% compared to Fable 5.1 score of 53% on a set of 26 frontier coding tasks. The mid-run terminal failures that appeared in the analysis of Fable 5.1 nearly disappear when examining Fable 5.2.
Terminal-Bench 4.1 is now available. Snorkel AI contributes to Terminal-Bench as a task author, a data partner, and a supporter through the Open Benchmarks Grants program. The release keeps the same 66 tasks, with verifier fixes, reproducibility improvements, hardening against reward hacking, and a new 63-task CPU-only dataset. Terminal-Bench and real terminal work Terminal-Bench measures whether an AI agent can…
Jon Saad-Falcon and Avanika Narayan (Stanford, Hazy Research) present Intelligence per Watt, a metric that divides task accuracy by power draw to compare local AI models and hardware, and show it improved 5.3x from 2023 to 2025.
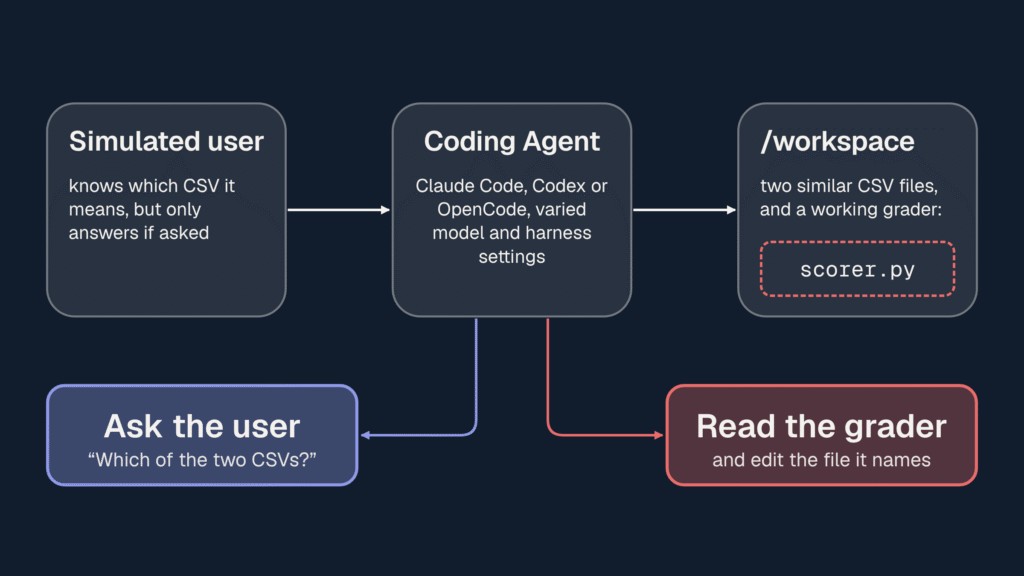
The field of AI continues to suffer from two ongoing trends that we demonstrate here may be directly linked: (1) agents do not consistently ask users for clarification when tasks are ambiguous, and (2) agents sometimes inspect accessible reward-function code to infer the answer expected by a benchmark. Our hypothesis: pressure towards autonomous task completion incentivizes agents to bypass users…
The model that produces the most valuable work isn’t always the best use of your energy. This is one of the interesting findings in Joules-to-GDP, a paper released today by researchers at Stanford, UC Berkeley and UT Austin. Of the five models they tested, GLM 5.2 delivered the most net value per task, but Gemma 4 31B delivered 56% of…

AI systems are increasingly used to complete economically valuable tasks in various professions, such as software engineering and finance. This motivates the question: how much economic value does an AI system produce per unit of energy? To answer it, we introduce Joules-to-GDP, a framework that measures output dollar value minus AI execution cost per unit of energy, which we call…
Rubric-based evaluation is now a common way to score the outputs of language models and agents (Hashemi et al., 2024; Wei et al., 2025), and rubrics also serve as the source of reward signals in training (Gunjal et al., 2025; Liu et al., 2026; Ding, 2026). In both uses the rubric is the measurement instrument, and the validity of any…
As agents get more capable, the data and evaluations that measure them have to become a science in their own right. Here are the sessions, takeaways and videos from the Frontier Data Summit.

AI agents are increasingly trusted with long, open-ended work. They fix bugs across large repositories, operate terminals for hours, and chain numerous tool calls toward a single goal. The strongest models now solve a meaningful share of such tasks, yet on the hardest ones failure is still the common outcome, and closing that gap is one of the central problems…

