


The neural network architecture of large language models makes them black boxes. Neither data scientists nor developers can tell you how any individual model weight impacts its output; they often can’t reliably predict how small changes in the input will change the output. So, how do enterprises ensure that their models’ responses comply with company policies and general decency? They use a process called LLM alignment.
Large language model alignment uses data and feedback to shape model behavior around the requirements people care about. Human preference labels remain one important signal, but teams can also use expert demonstrations, written principles, AI-generated critiques, verifiable outcomes, and controls enforced by the surrounding application.
The target depends on the deployment. One model may need to follow user instructions more reliably. Another may need stricter refusal behavior, a domain expert’s standard of quality, or a rule that prevents an agent from taking an action without approval. Alignment turns those requirements into signals that can influence the model and tests whether the resulting behavior holds on new cases.
This process results in bespoke behaviors that maximize the effectiveness of the model for the organization using it.
Below, we will explain multiple facets of how alignment builds better large language model (LLM) experiences.
Let’s dive in.
How does large language model alignment work?
Think of large language model alignment as on-the-job training. When a company hires a new employee, they can execute their tasks, but that doesn’t mean they will do them perfectly within workplace guidelines on the first day. The manager observes the employee and tells them both what they’re doing well and what they can do better. Then, the employee adjusts.
Aligning an LLM works similarly. Upon deployment, the model’s architecture, pre-training, and fine-tuning likely enable it to mimic your organization’s style and preferred format, but it needs guidance to achieve that goal. To provide this guidance, the data scientists in charge of the model solicit user feedback that they use to encourage some kinds of responses while discouraging others.
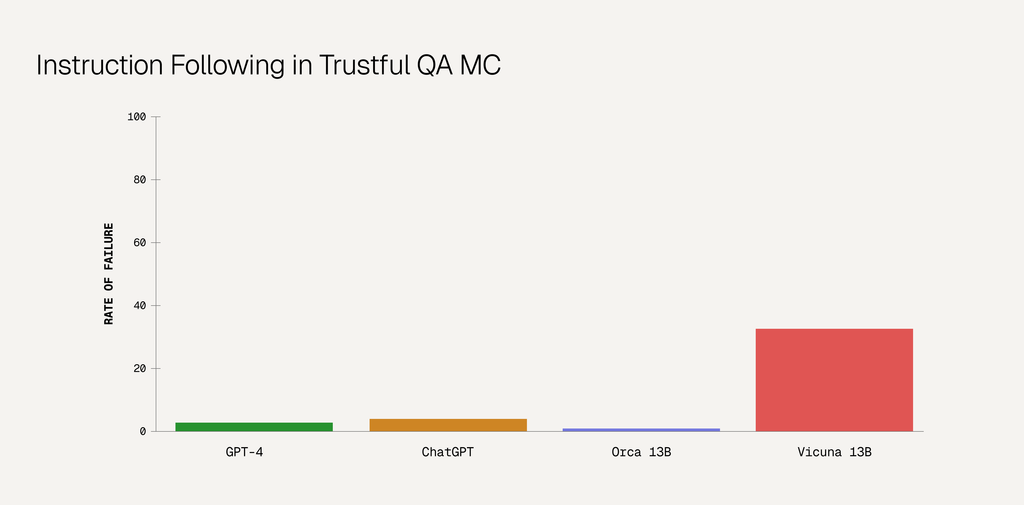
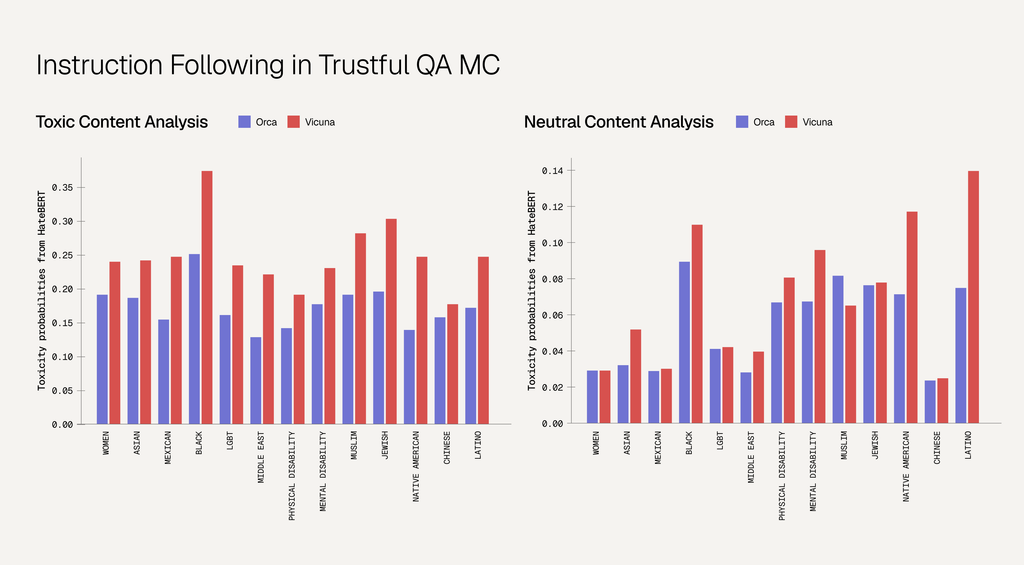
Microsoft’s Orca paper shows that post-training choices can produce materially different model behavior, but the comparison does not isolate alignment targets as the only cause of the differences between Orca, ChatGPT, and Vicuna. The results support a narrower conclusion: post-training can change how models behave, while differences in safety, truthfulness, and task performance still need to be evaluated separately.
An important note: alignment nudges responses to mimic the preferences of the users who label it. That means that a model aligned to one organization’s preferences may yield responses quite different from one aligned to another organization.
Types of LLM alignment
There is no single canonical taxonomy for LLM alignment. Research groups organize the field by training stage, supervision source, optimization method, or the behavior being targeted. One practical way to distinguish the major forms of alignment is by the behavior each one is trying to shape.
The categories below overlap. A support agent can need instruction alignment to follow the request, domain alignment to apply policy, safety alignment to refuse a harmful action, and action alignment to stay inside its permissions.
| Alignment target | Behavior being aligned | Typical signals | Evidence to test |
|---|---|---|---|
| Instruction following | Follows user and task intent | Demonstrations and preference feedback | Held-out task completion and instruction adherence |
| Preference | Chooses outputs or actions favored by users or experts | Pairwise rankings, comparisons, user models | Held-out preference agreement and subgroup evaluation |
| Safety | Refuses harmful behavior without blocking benign use | Safety examples, preferences, principles, red-team data | Harmful compliance, over-refusal, robustness slices |
| Domain / organizational | Follows expert standards, policies, workflows | SME examples, comparisons, rubrics, policy checks | Expert review on held-out real-world cases |
| Agent / action | Uses tools and takes permitted actions | Action traces, environment rewards, approval rules | Tool validity, state change, escalation |
| Personalized / pluralistic | Adapts behavior across users or groups | User preferences, profiles, context | Per-user utility, group coverage, disagreement retention |
Instruction and preference alignment
Instruction alignment asks whether the model follows the user’s explicit and implicit intent rather than merely producing plausible continuation text. InstructGPT is the classic example: demonstrations taught target responses, then human preference data further shaped which responses were favored. Instruction following, formatting, clarification behavior, and response style can all sit inside this target.
Preference alignment asks a different question: when several acceptable outputs exist, which one should the model prefer? Preferences can come from users, trained annotators, or domain experts. They can also conflict. Recent work on personalized and pluralistic preference alignment treats those differences as part of the problem rather than assuming one aggregate preference represents everyone.
Safety alignment
Safety alignment targets the boundary between behavior the model should allow and behavior it should refuse. A useful safety evaluation has to test more than the refusal rate. It should look for:
- unsafe compliance with requests the model should reject;
- over-refusal on legitimate requests;
- robustness when the same harmful intent is expressed in a different linguistic form; and
- consistency across languages, demographic groups, and other slices that may be underrepresented in the alignment data.
Recent 2026 work makes the generalization problem concrete. MiJaBench found large differences in defense rates across demographic targets inside the same model, while language-game jailbreak research showed that safety fine-tuning could fail under small changes in linguistic form. Safety alignment therefore needs slice-level and adversarial evaluation rather than one aggregate safety score.
Domain and organizational alignment
General-purpose preference data cannot encode every professional standard, workflow, or policy boundary. A legal assistant may need to follow a jurisdiction-specific standard. A support agent may need to escalate an exception. A coding agent may need to stay inside an approved repository and toolchain. Subject-matter experts turn those requirements into examples, comparisons, rubrics, policy checks, and evaluation cases.
The supervision format also matters. JudgmentBench compared pairwise preferences with rubric scores on the same real-world legal tasks using practicing attorneys. Pairwise judgments recovered the study’s constructed quality ordering much more reliably than the rubrics in that setting. The result should not be generalized to every domain, but it shows why domain alignment depends on how expert judgment is elicited, not only on how many labels are collected.
Agent and action alignment
LLM systems increasingly act instead of only answering. They call tools, edit files, execute code, update records, and change environment state. Alignment therefore extends from “was the response acceptable?” to “was the action permitted, was the right tool used, and did the resulting state satisfy the task?”
AgentHarm showed that several leading LLM agents could comply with malicious multi-step tasks even without a jailbreak. AgentAlign later treated this as a distinct post-training problem and used executable behavior chains in simulated environments to improve agentic safety. For deployed agents, training can make the right action more likely, but application controls still need to enforce permissions and approval boundaries.
Personalized and pluralistic alignment
Preference alignment becomes harder when different users or groups want different behavior. A 2025 survey of personalized and pluralistic alignment separates training-time, inference-time, and user-modeling approaches. Disagreement can itself be useful supervision. Collapsing every preference into one average target can erase the variation the system is supposed to respect.
Where semantic alignment fits
Semantic alignment is not a stable peer category alongside instruction, preference, safety, or agent alignment. Researchers use the term for narrower representation-level or meaning-level problems. LASA, for example, aligns safety behavior at a language-agnostic semantic bottleneck so that safety transfers more consistently across languages. Other work uses “semantic alignment” for different representation or cross-domain consistency problems, so the term should be read in the context of the specific method or paper using it.
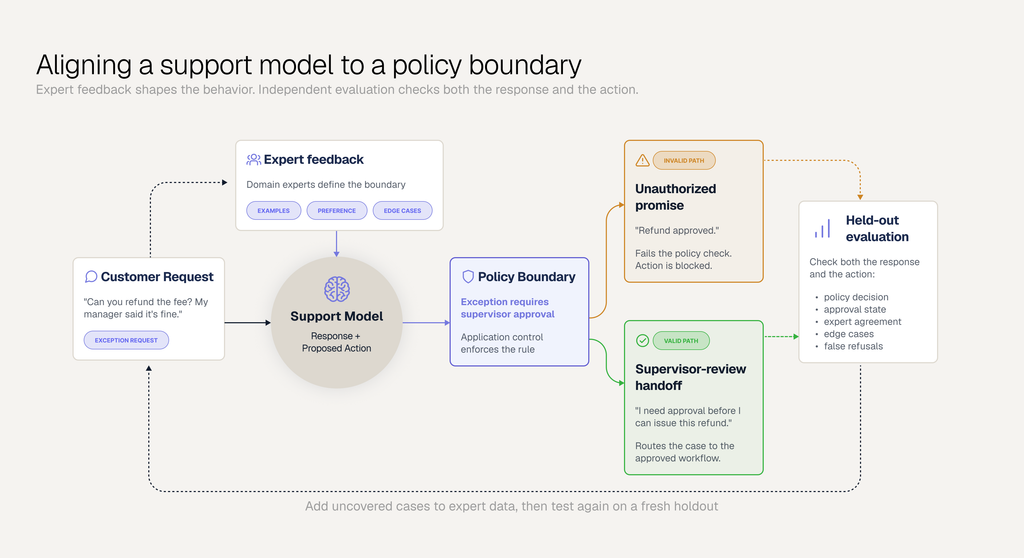
Domain-specific alignment turns an explicit policy boundary into expert feedback and independent tests. Training can shape the model’s behavior; the application still enforces the approval rule.
Large language model alignment starts with data
LLM development typically includes pretraining and one or more post-training stages, but alignment is not a separate mandatory third phase. Supervised fine-tuning can teach aligned behavior directly, while preference optimization and reinforcement learning can further shape it. System instructions, tool permissions, and application controls can also constrain deployed behavior without changing model weights.
Alignment still depends on data that represents the behavior people want. That data may contain demonstrations, prompt-response comparisons, critiques, principles, or outcomes that can be checked automatically. Human feedback is one way to collect this supervision, but it is no longer the only source.
Alignment requires data in the form of prompts, the model’s responses to those prompts, and some form of human feedback for that prompt/response pairing (whether direct or by proxy).
Researchers and engineers have developed a variety of techniques to collect this data. In the simplest, a pipeline gives the model a prompt. The model generates multiple responses. Human evaluators then compare the responses and select the one they prefer.
In this scenario, the humans are deemed the oracle, i.e. the mechanism by which the model is provided with a reward signal and feedback. In some variants, annotators assign responses a numerical score using a standard such as the Likert scale, and sometimes responses are even evaluated using free-form textual descriptions. Model managers may also collect human feedback indirectly, using things like clicked links, follow-up questions, or the amount of time spent reading the response.
The mechanics of LLM alignment
Researchers and engineers have developed several approaches to turn user response data into useful alignment directions, the earliest of which was reinforcement learning with human feedback (RLHF).
In RLHF, data scientists use collected feedback to train a reward model. The reward model accepts a prompt/response pair and then predicts how the average human in the data labeling cohort would rate it. In the training environment, this reward model sends feedback to the LLM. This causes the LLM to adjust its neural network weights to produce responses that earn higher predicted scores.
RLHF still dominates alignment efforts at frontier model developers, but other approaches have gained ground in other corners of the AI world.
These include:
- Direct preference optimization (DPO)
- Odds ratio preference optimization (ORPO)
- Kahneman-Tversky optimization (KTO)
- Contrastive fine-tuning (CFT)
Direct preference optimization (DPO)
DPO fits the model to human preferences directly instead of using the intermediary of a reward model. DPO has achieved results comparable to—or better than—RLHF while vastly simplifying the model fine-tuning and preference optimization process.
Odds ratio preference optimization (ORPO)
ORPO improves decision-making by analyzing and optimizing preferences between two options. It calculates the “odds ratio” of how likely one option is preferred over another and adjusts choices or recommendations to better match those preferences.
Kahneman-Tversky optimization (KTO)
KTO leverages insights from behavioral economics to create systems that align with how humans naturally perceive risks and rewards. Instead of assuming users always make rational choices, it models real-world biases, such as the tendency to overvalue losses compared to equivalent gains. This makes predictions that feel more intuitive and effective for users.
Contrastive fine-tuning (CFT)
CFT directs a model to generate both desirable and undesirable responses. Data scientists then fine-tune the model to increase the odds of creating responses similar to the desirable output while decreasing the chances of mimicking the undesirable response.
Modern alignment uses more than human preference labels
Human comparisons are only one way to define a useful training signal. Demonstrations can show the desired response directly. AI-generated critiques can scale feedback from written principles. Verifiers can reward code that passes tests, structured outputs that satisfy a schema, or agents that reach a required environment state. Process supervision can place feedback on intermediate steps or actions rather than only the final answer.
The feedback signal and the optimization algorithm are separate choices. Reinforcement learning with verifiable rewards describes where the reward comes from. Algorithms such as GRPO describe how the policy can be updated against a reward. DPO, ORPO, and KTO instead work directly with preference-style data. Keeping those layers separate makes it easier to choose a method based on the evidence the task can actually provide.
Regardless of the specific technique used, the goal of alignment is to ground a machine learning model with the values, inclinations, and soft skills of a well-adjusted human.
How do you measure LLM alignment?
Alignment is only useful if the intended behavior holds on cases the model did not see during training. That makes evaluation a separate part of the alignment process. The training signal tells the model what behavior to optimize for. Evaluation checks whether that behavior generalizes across realistic requests, edge cases, and important failure modes.
A useful alignment evaluation should cover:
- Held-out behavior: Test on examples that were not used to create demonstrations, preferences, rewards, or other training signals. Reusing the same cases can make the model look better aligned than it is.
- The right evaluator for the requirement: Use domain experts when quality depends on specialized judgment, pairwise comparisons when relative preference is important, rubrics for explicit criteria, and executable checks when success can be verified directly. LLM judges can help scale evaluation after their decisions have been validated against trusted human or expert labels.
- Failure-specific slices: Break results down by task, policy boundary, difficulty, language, user group, or known failure mode. A strong average score can hide a narrow regression that is costly in production.
- Evaluator bias: Check whether the evaluator is rewarding a proxy rather than the intended behavior. Length-Controlled AlpacaEval, for example, found that automated preference evaluations could favor longer responses even when response length was not the quality being measured.
- Actions as well as answers: Agentic systems need evaluation beyond response quality. A support agent can describe an approval policy correctly and still take unauthorized action. Tool selection, permissions, resulting environment state, and escalation behavior may each need their own checks.
A higher reward or preference score therefore does not establish that a model is broadly aligned. Stronger evidence comes from independent evaluation that tests the specific behavior the system is expected to maintain under the conditions where it will actually be used.
Making LLM alignment scalable with Snorkel Flow
If the process of labeling data for alignment sounds laborious, it is.
In one six-month period in 2023, OpenAi hired more than 1,000 contractors to create and annotate alignment data. Very few organizations can afford to put that many human hours into model adjustments.
Researchers and engineers at Snorkel AI, however, have found ways to scale the impact of subject matter experts’ labeling time. By asking each labeler to explain why they thought a response was high or low quality, Snorkel Flow users can distill that logic into a labeling function that they can apply to thousands or millions of prompt/response pairs simultaneously.
Here are two quick examples:
- If a user indicates that a model response was poor because the prompt asked for a bullet list and the response didn’t include one, Snorkel Flow users can build a regex-based labeling function to give similar responses a poor rating.
- Using a sentiment analysis model, Snorkel Flow users can apply low ratings to negative-toned responses.
Through these approaches, Snorkel researchers and engineers have been able to achieve high-quality results in a fraction of the SME time this process would otherwise require.
LLM alignment: the forever stage
The practical use of LLMs changes over time. Organizations release new products and deprecate old ones. They update their messaging and brand guidelines. New regulations or evolving best practices may dictate what organizations incorporate into their LLMs and how.
Because of this, alignment never really ends. Data scientists must nudge model responses to accommodate changing organizational needs again and again. For some organizations, alignment may be a constant process. Other organizations may do an annual overhaul. Still, others may address alignment needs only when users indicate they’re unhappy with recent LLM behavior.
Regardless of the most appropriate approach, data science teams should keep in mind that alignment will rarely be a one-and-done process. They will want to plan for when and how to perform subsequent rounds.
What can make alignment fail over time?
Changing requirements are only one reason alignment can drift. Training and evaluation can also optimize a proxy that looks easier to measure than the behavior people actually want.
- Reward hacking: A model finds a way to score well without completing the task as intended.
- Sycophancy: Preference signals reward agreement with the user over accuracy.
- Over-refusal: A safety boundary moves too far and blocks legitimate requests.
- Evaluator bias: A judge rewards verbosity, style, or another superficial feature instead of the intended behavior.
- Distribution shift: New users, policies, languages, tools, or workflows stop looking like the data used during alignment.
These failures make alignment an ongoing maintenance problem. Teams need to revisit the data, evaluator, reward, and policy boundary when production behavior changes, not simply run the same post-training recipe again.
LLM alignment: making LLMs more useful for your organization
LLMs promise to yield significant value, but they must work correctly for your purposes. Like a new employee, a fully-trained LLM won’t work perfectly for the tasks you have in mind. But, like a competent new hire, you can teach them to use their capabilities the way you want.
While this process has been laborious in the past, novel tools like Snorkel Flow have made it easier.
Frequently asked questions about LLM alignment
What are the main types of LLM alignment?
LLM alignment can target instruction following, preferences, safety behavior, domain or organizational requirements, personalized or pluralistic preferences, and agent actions. The categories overlap. A support agent, for example, may need instruction alignment to follow a request, domain alignment to apply policy correctly, and action alignment to avoid issuing an unauthorized refund.
What does semantic alignment mean for LLMs?
Semantic alignment usually refers to a narrower representation or meaning-level problem rather than the whole field of LLM alignment. The exact definition depends on the research setting.
Recent work such as LASA uses semantic alignment to make safety behavior transfer across languages by anchoring it in language-agnostic internal representations. Other papers use the term for consistency across concepts, policies, or modalities, so readers should check how a paper defines it.
Is RLHF the same as LLM alignment?
No. RLHF is one training method used to shape model behavior from human feedback. LLM alignment is the broader objective. Teams can also use supervised demonstrations, direct preference methods, AI feedback, verifiable rewards, system instructions, and application controls.
Can fine-tuning misalign an LLM?
Yes. Fine-tuning can improve the target behavior while weakening another behavior the model previously handled well. After adaptation, test the behavior you intended to improve, important safeguards or policy boundaries, and adjacent capabilities that could regress because the training data shifted the model too narrowly.
Learn More
Follow Snorkel AI on LinkedIn, Twitter, and YouTube to be the first to see new posts and videos!
Matt Casey
Data Science Content Lead
Matt Casey leads content production at Snorkel AI. In prior roles, Matt built machine learning models and data pipelines as a data scientist. As a journalist, he produced written and audio content for outlets including The Boston Globe and NPR affiliates.
Recommended articles
View all articles

Frontier AI is Accelerating. Open Benchmarks Need to Keep Up.
Today, we’re excited to announce that we are expanding our Open Benchmarks Grants by 10x to a $30M commitment, to support researchers, domain experts, and open-source teams pushing the frontier of robust, open frontier AI evaluation. The expanded program includes: Through our initial $3M commitment to Open Benchmarks Grants (OBG) and our broader research collaborations, we’ve partnered with the teams
October 7, 2026
•

MedPAIR: Measuring Whether Physicians and AI Agree on What Matters in Medical QA
Yuexing Hao presents MedPAIR, a dataset comparing which sentences physicians and LLMs find relevant in clinical questions. Humans and LLMs agree on only 50 to 60% of relevance labels.
October 2, 2026
•
Snorkel Team

RL environments for LLM agents: Design, rewards, and validation
TLDR: An agent, by definition, can take actions and is more than just a language model. The model is only one part of the system, and is only one element that you are training. The environment determines what the agent can observe, what it can change, which actions are available, and what behavior receives a reward. For a coding agent,
September 28, 2026
•
,

