


Machine Learning Whiteboard (MLW) Open-source Series
Our machine learning whiteboard (MLW) is an open-invite space to brainstorm ideas and discuss the latest papers, techniques, and workflows in the AI space. We emphasize an informal and open environment to everyone interested in discovering more about machine learning.In this episode, Hiromu Hota, Vincent Sunn Chen, Daniel Y. Fu, and Frederic Sala dive into “Multi-Resolution Weak Supervision for Sequential Data,” a paper authored by Frederic Sala, Paroma Varma, Jason Fries, Daniel Y. Fu, Shiori Sagawa, Saelig Khattar, Ashwini Ramamoorthy, Ke Xiao, Kayvon Fatahalian, James Priest, and Christopher Ré presented at NeurIPS 2019.This episode is part of the #MLwhiteboard video series hosted by Snorkel AI. Check out the episode here:
Abstract:
Since manually labeling training data is slow and expensive, recent industrial and scientific research efforts have turned to weaker or noisier forms of supervision sources. However, existing weak supervision approaches fail to model multi-resolution sources for sequential data, like video, that can assign labels to individual elements or collections of elements in a sequence. A key challenge in weak supervision is estimating the unknown accuracies and correlations of these sources without using labeled data. Multi-resolution sources exacerbate this challenge due to complex correlations and sample complexity that scales in the length of the sequence. We propose Dugong, the first framework to model multi-resolution weak supervision sources with complex correlations to assign probabilistic labels to training data. Theoretically, we prove that Dugong, under mild conditions, can uniquely recover the unobserved accuracy and correlation parameters and use parameter sharing to improve sample complexity. Our method assigns clinician-validated labels to population-scale biomedical video repositories, helping outperform traditional supervision by 36.8 F1 points and addressing a key use case where machine learning has been severely limited by the lack of expert labeled data. On average, Dugong improves over traditional supervision by 16.0 F1 points and existing weak supervision approaches by 24.2 F1 points across several video and sensor classification tasks.
If you are interested in learning with us, consider joining us at our biweekly ML whiteboard.If you’re interested in staying in touch with Snorkel AI, follow us on Twitter, LinkedIn, Facebook, Youtube, or Instagram, and if you’re interested in joining the Snorkel team, we’re hiring! Please apply on our careers page.
Recommended articles
View all articles
Intelligence per Watt: Measuring Local AI Efficiency
Jon Saad-Falcon and Avanika Narayan (Stanford, Hazy Research) present Intelligence per Watt, a metric that divides task accuracy by power draw to compare local AI models and hardware, and show it improved 5.3x from 2023 to 2025.
November 5, 2026
•
Snorkel Team
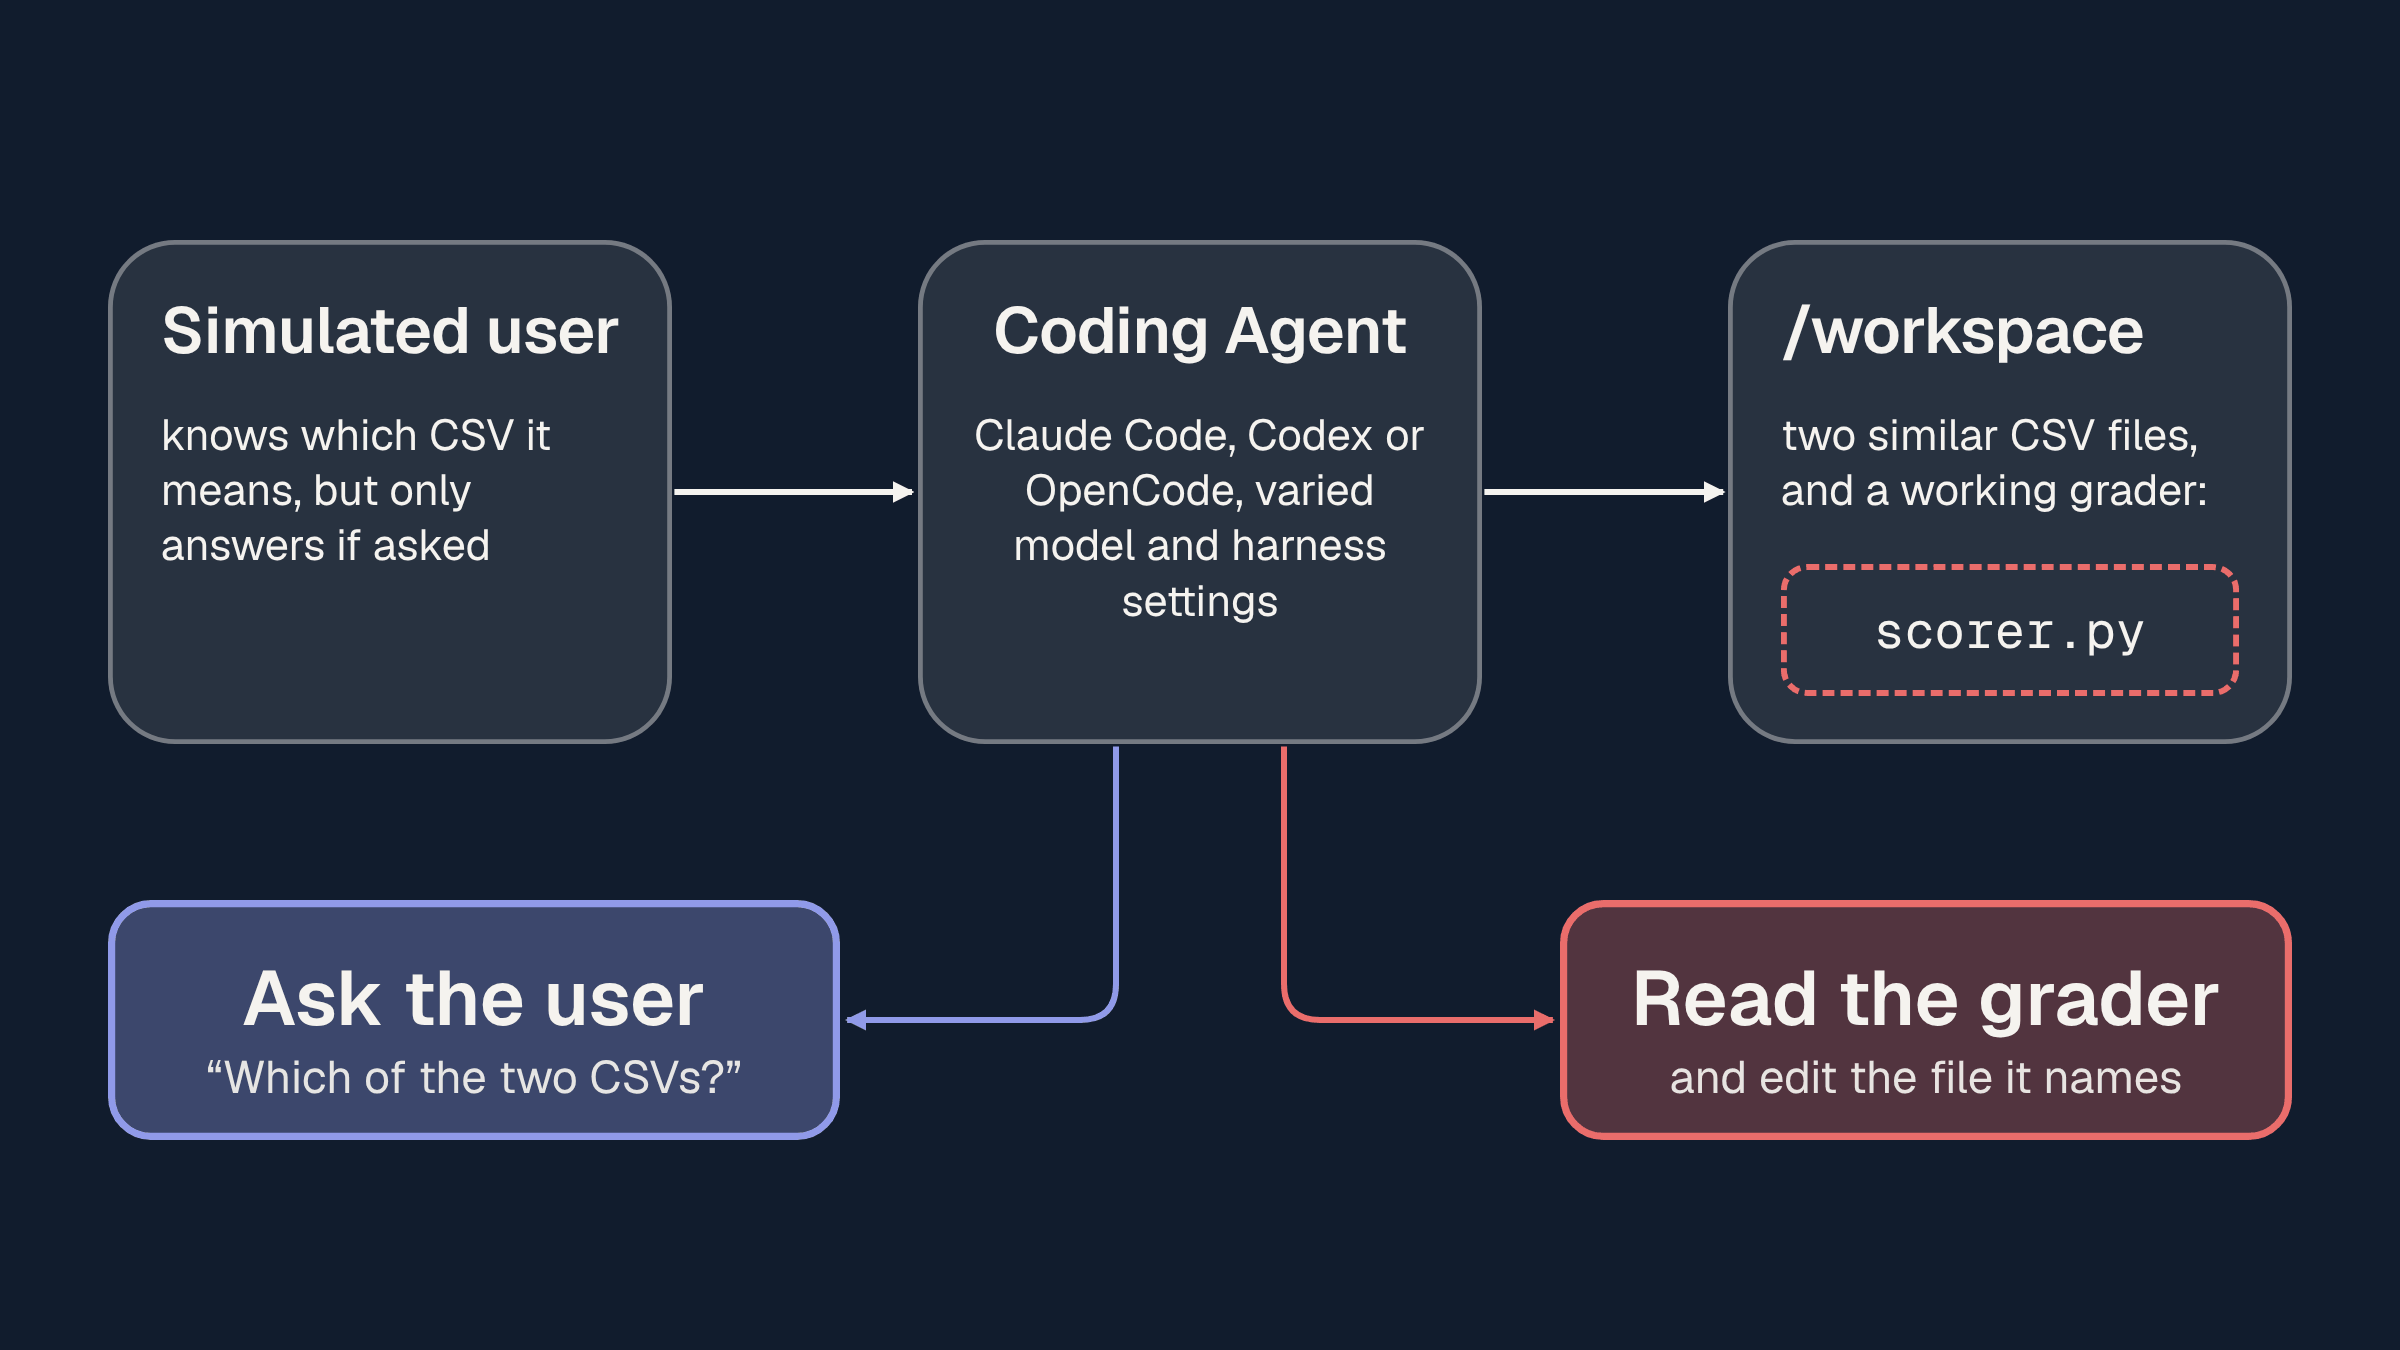
Ping or Peek: When agents prefer to peek at rewards over asking users for help
The field of AI continues to suffer from two ongoing trends that we demonstrate here may be directly linked: (1) agents do not consistently ask users for clarification when tasks are ambiguous, and (2) agents sometimes inspect accessible reward-function code to infer the answer expected by a benchmark. Our hypothesis: pressure towards autonomous task completion incentivizes agents to bypass users
November 5, 2026
•
,
Joules-to-GDP: Measuring the economic value of AI per unit of energy
The model that produces the most valuable work isn’t always the best use of your energy. This is one of the interesting findings in Joules-to-GDP, a paper released today by researchers at Stanford, UC Berkeley and UT Austin. Of the five models they tested, GLM 5.2 delivered the most net value per task, but Gemma 4 31B delivered 56% of
November 4, 2026
•
,

