Twelve speakers shared their insights into the present and future of foundation models at our Foundation Model Summit in January. Summit attendees watched the sessions live and asked questions, but now you can see what they saw; we have released nine Foundation Model Summit videos on our YouTube channel.
The videos touch on how foundation models (FMs) and Large Language Models (LLMs) enable valuable applications, how data-centric development is the key to closing the gap between AI’s power and companies’ ability to gain value from it and why FMs mean that companies need to refresh their model-management frameworks. The sessions also touch on generative AI’s potential and why generative AI is not quite ready for prime time.
Take a look at the videos below.
Opening Address
Alex Ratner, CEO and co-founder of Snorkel AI, set the tone for the day’s events by highlighting the breakthrough that foundation models/LLMs represent for AI, along with the growing gap between AI’s power and companies’ ability to gain value from it.
Towards Unified Foundational Model for Vision and Language Alignment
Amanpreet Singh, research team lead at Hugging Face, presents an overview of new, more generalized foundation models that can perform tasks across modalities. He also highlighted new frameworks for assessing the performance of foundation models.
Trends in Enterprise ML and the Potential Impact of Foundation Models
Carlo Giovine, a partner at McKinsey QuantumBlack, together with David Harvey, a staff expert at the same firm, told the online audience that companies are not moving fast enough to capture the value potential of AI/ML.
The Ethical Implications of Building A Real-Life Skynet
Joe Penna, Head of Entertainment Technology at Stability AI, walked the audience through his career—from YouTube creator to feature film director to his work at Stability AI—before showing how generative AI could have saved his productions time and money. He demonstrated AI technologies that would let him generate ideas for movie posters, insert his actors into photographs for ease of shot-planning, artificially change the lighting in post-production and even change a camera angle after the shot had been completed.
Tutorial on Foundation Models and Fine-tuning
Ananya Kumar, ML researcher at Stanford University, gave an overview of foundation models and why data scientists’ instinct to fine-tune these models may be misguided.
Kumar’s work found that fine-tuning Foundation Models often improves their performance on the test data, but can lead to worse performance on real-world, out-of-distribution examples; fine-tuning, he said, distorts the feature space. His work found that using a method such as linear probing to build and train a layer on top of the model while keeping the foundation weights frozen yields better results for out-of-distribution examples.
AMA: How are Foundation Models Changing the Way We Build Data Management Systems?
Simran Arora, ML researcher at Stanford University, outlined an approach that she and her collaborators used to get better performance from large language models without doing any additional training on the LLMs themselves.
Challenges and Ethics of DLM and LLM Adoption in the Enterprise
Ali Arsanjani, director of cloud partner engineering at Google, highlighted some non-obvious challenges and benefits that Foundation Models present for enterprises—including the inadequacy of current machine learning pipelines to handle FM development workflows.
A Practical Approach to Delivering Enterprise Value with Foundation Models
Jimmy Lin, NLP product lead at Sambanova Systems, outlines the impracticality of businesses deploying generalized foundation models. The model is just the starting point, he said, and businesses can get a better return by observing a four-stage pipeline: start with a generalized model, fine-tune that model with a dataset specific to your domain, further fine-tune the model with a dataset specific to your task, and then deploy the model.
Generative AI is… Not Enough?
Jay Alammar, director and engineering fellow at Cohere, thinks you should tame your enthusiasm for generative AIs. The performance of the current generation of models is not reliably impressive, he said, but also noted that the models themselves are only part of the solution. These models will truly show their value, he predicted, when paired with other technologies such as search engines.
Like our Foundation Model Summit videos? Subscribe on YouTube!
Our Snorkel AI YouTube channel features videos from our past virtual conferences, interviews with AI and ML researchers, and more.
Matt Casey
Data Science Content Lead
Matt Casey leads content production at Snorkel AI. In prior roles, Matt built machine learning models and data pipelines as a data scientist. As a journalist, he produced written and audio content for outlets including The Boston Globe and NPR affiliates.
Recommended articles
View all articles
Paper2Agent: Turning Research Papers Into Interactive AI Agents
Jiacheng Miao (Stanford HAI) presents Paper2Agent, a framework that turns a research paper and its code into an interactive AI agent, scoring 91.2% on 300 benchmark questions against 80.3% for Claude Code with the repo.
November 19, 2026
•
Snorkel Team
Training agents for professional work when success is rare
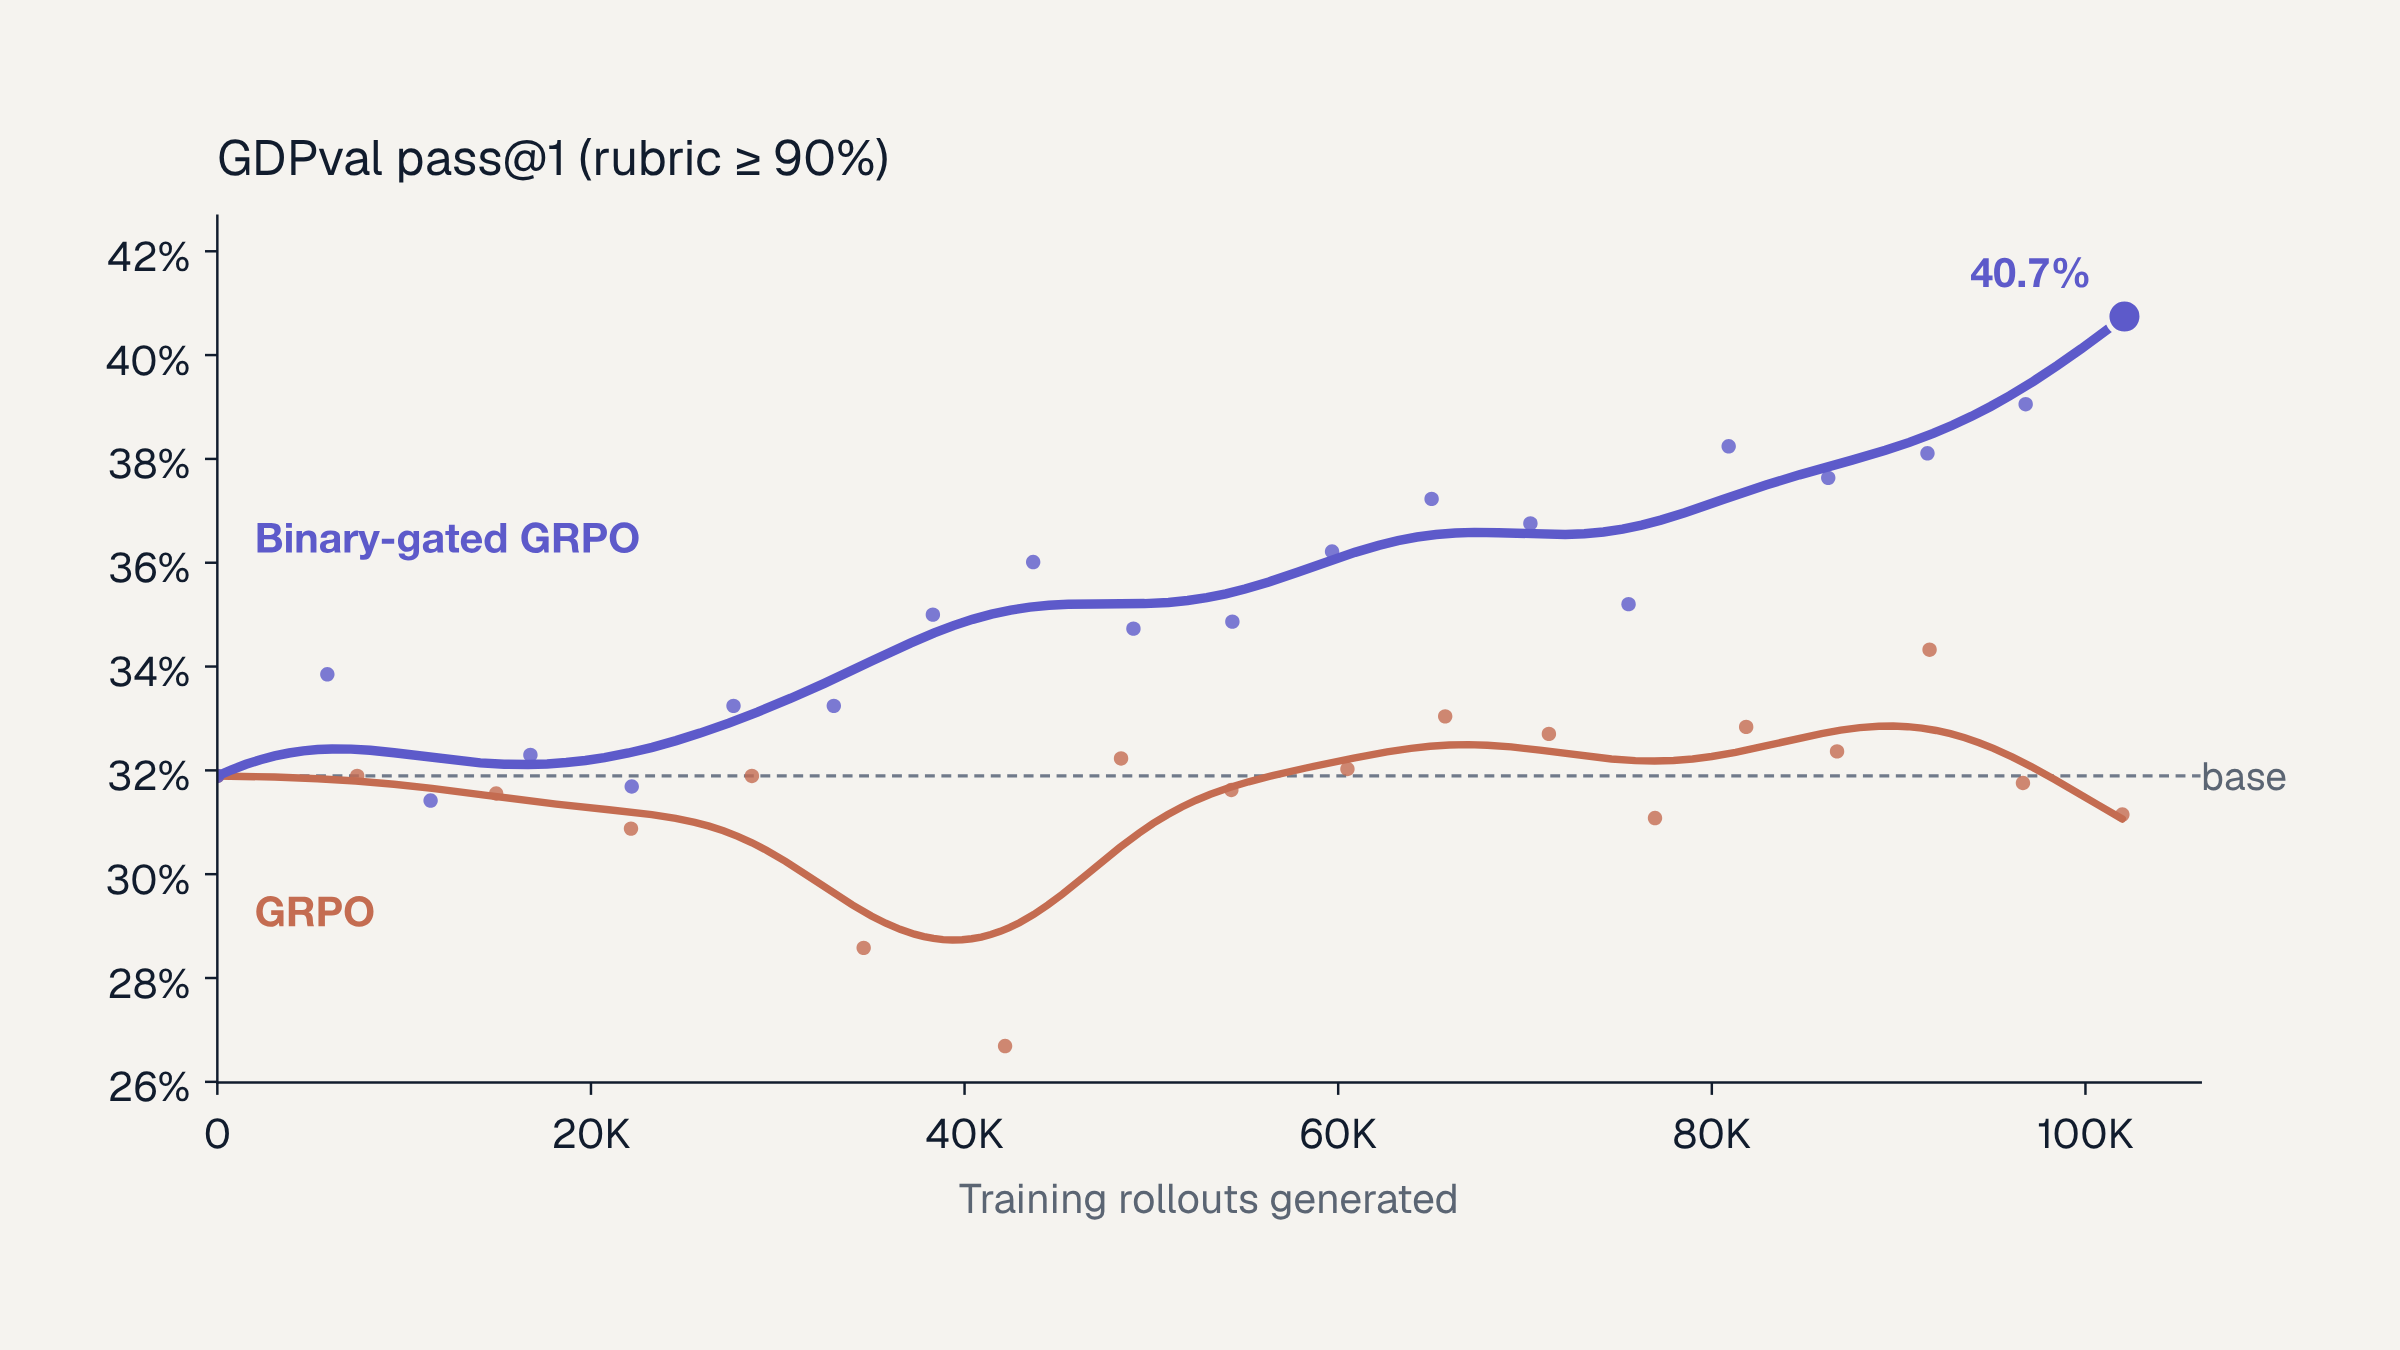
We trained Qwen3.8-27B on 1,105 professional tasks from Snorkel’s GDPval+ series. After about 102K training rollouts, the model reaches 40.7% pass@1 on OpenAI’s GDPval gold set, up from 31.9%. Its deliverables now beat those of human experts in 44.0% of LLM-judged head-to-head comparisons, compared with 36.4% for the base model. The gains come from two ingredients working together, expert-built training
November 19, 2026
•