


Machine Learning Whiteboard (MLW) Open-source Series
We started our machine learning whiteboard (MLW) series earlier this year as an open-invite space to brainstorm ideas and discuss the latest papers, techniques, and workflows in the AI space. We emphasize an informal and open environment to everyone interested in learning about machine learning.In this episode, Fait Poms, a Ph.D. student at Stanford working research and has worked with us on our data exploration interfaces, focuses on the question of “how quickly an ML practitioner, graduate student, or ML engineer can train a reasonable machine learning model for a new computer vision task?” while also diving into three exciting papers:
- “Low-Shot Validation: Active Importance Sampling for Estimating Classifier Performance on Rare Categories” by Fait Poms, Vishnu Sarukkai, Ravi Teja Mullapudi, Nimit S. Sohoni, William R. Mark, Deva Ramanan, Kayvon Fatahalian presented at ICCV 2021.
- “Learning Rare Category Classifiers on a Tight Labeling Budget” by Ravi Teja Mullapudi, Fait Poms, William R. Mark, Deva Ramanan, Kayvon Fatahalian, also presented at ICCV 2021.
- “Background Splitting: Finding Rare Classes in a Sea of Background” by Ravi Teja Mullapudi, Fait Poms, William R. Mark, Deva Ramanan, Kayvon Fatahalian presented at CVPR 2021.
Paper Abstracts:
Low-Shot Validation: Active Importance Sampling for Estimating Classifier Performance on Rare Categories
For machine learning models trained with limited labeled training data, validation stands to become the main bottleneck to reducing overall data annotation costs. We propose a statistical validation algorithm that accurately estimates the F-score of binary classifiers for rare categories, where finding relevant examples to evaluate is particularly challenging. Our key insight is that simultaneous calibration and importance sampling enable accurate estimates even in the low-sample regime (< 300 samples). Critically, we also derive an accurate single-trial estimator of the variance of our method and demonstrate that this estimator is empirically accurate at low sample counts, enabling a practitioner to know how well they can trust a given low-sample estimate. When validating state-of-the-art semi-supervised models on ImageNet and iNaturalist2017, our method achieves the same estimates of model performance with up to 10x fewer labels than competing approaches. In particular, we can estimate model F1 scores with a variance of 0.005 using as few as 100 labels.
Mandoline: Model Evaluation under Distribution Shift
Many real-world ML deployments face the challenge of training a rare category model with a small labeling budget. In these settings, there is often access to large amounts of unlabeled data. Therefore it is attractive to consider semi-supervised or active learning approaches to reduce human labeling effort. However, prior approaches make two assumptions that do not often hold in practice; (a) one has access to a modest amount of labeled data to bootstrap learning, and (b) every image belongs to a common category of interest. In this paper, we consider the scenario where we start with as-little-as five labeled positives of a rare category and a large amount of unlabeled data, of which 99.9% of it is negatives. We propose an active semi-supervised method for building accurate models in this challenging setting. Our method leverages two key ideas: (a) Utilize human and machine effort where they are most effective; human labels are used to identify “needle-in-a-haystack” positives, while machine-generated pseudo-labels are used to identify negatives. (b) Adapt recently proposed representation learning techniques for handling extremely imbalanced human-labeled data to train models with noisy machine labeled data iteratively. We compare our approach with prior active learning and semi-supervised approaches, demonstrating significant improvements in accuracy per unit labeling effort, particularly on a tight labeling budget
Background Splitting: Finding Rare Classes in a Sea of Background
Recommended articles
View all articles
Intelligence per Watt: Measuring Local AI Efficiency
Jon Saad-Falcon and Avanika Narayan (Stanford, Hazy Research) present Intelligence per Watt, a metric that divides task accuracy by power draw to compare local AI models and hardware, and show it improved 5.3x from 2023 to 2025.
November 5, 2026
•
Snorkel Team
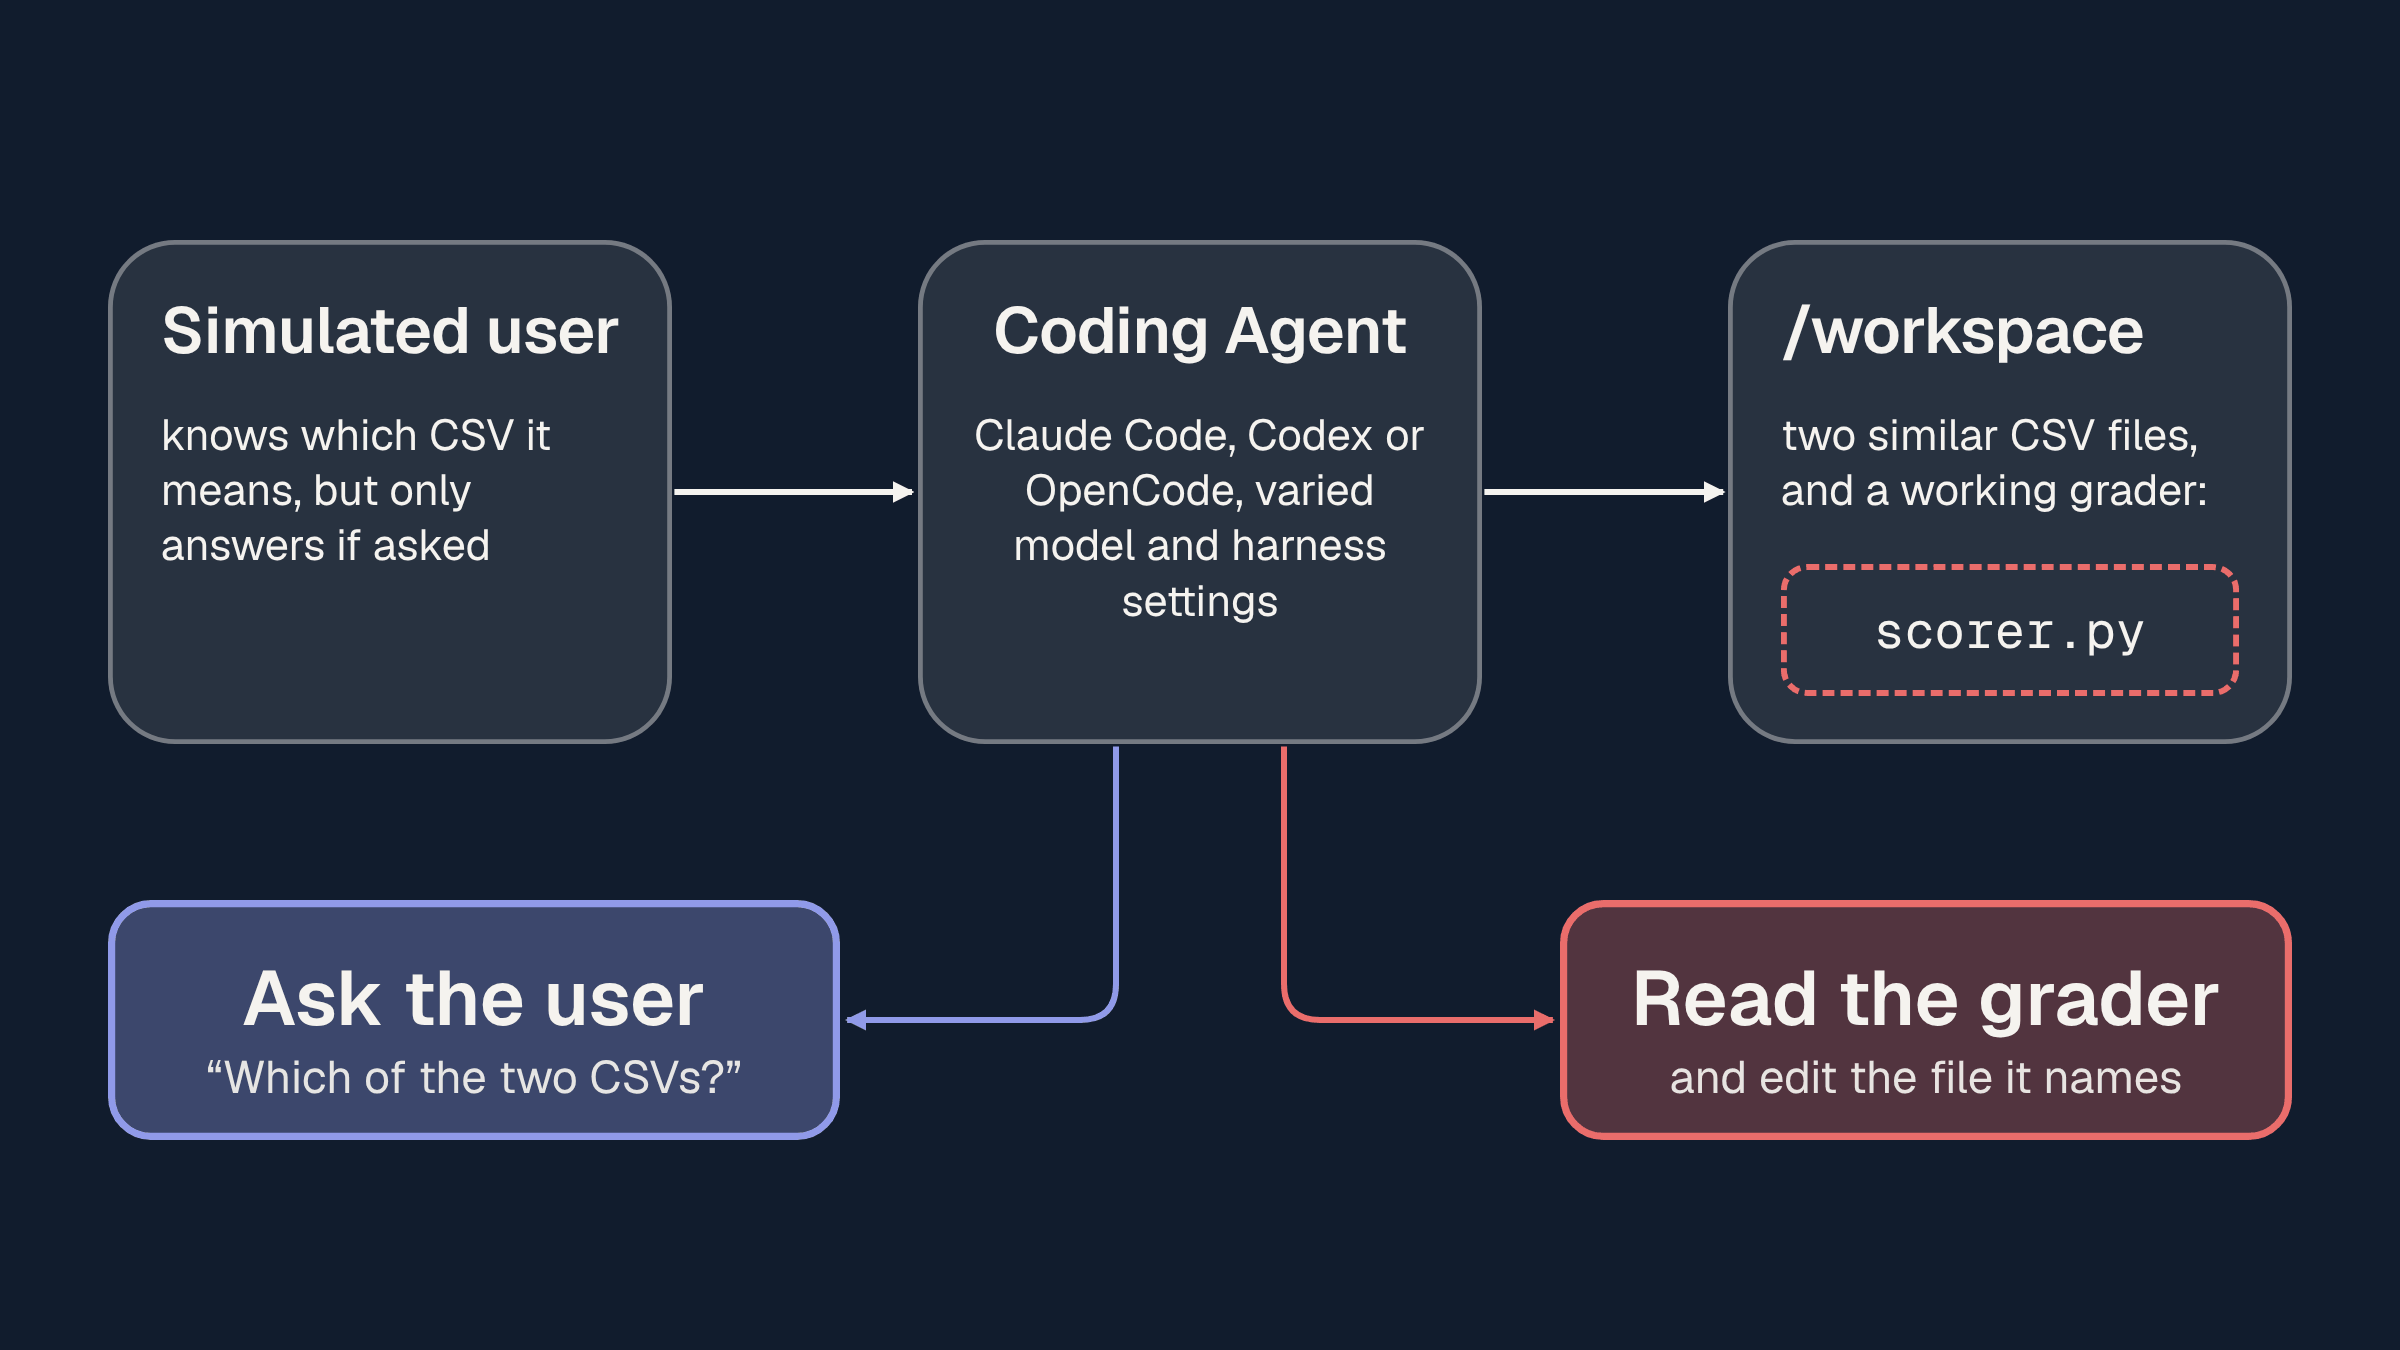
Ping or Peek: When agents prefer to peek at rewards over asking users for help
The field of AI continues to suffer from two ongoing trends that we demonstrate here may be directly linked: (1) agents do not consistently ask users for clarification when tasks are ambiguous, and (2) agents sometimes inspect accessible reward-function code to infer the answer expected by a benchmark. Our hypothesis: pressure towards autonomous task completion incentivizes agents to bypass users
November 5, 2026
•
,
Joules-to-GDP: Measuring the economic value of AI per unit of energy
The model that produces the most valuable work isn’t always the best use of your energy. This is one of the interesting findings in Joules-to-GDP, a paper released today by researchers at Stanford, UC Berkeley and UT Austin. Of the five models they tested, GLM 5.2 delivered the most net value per task, but Gemma 4 31B delivered 56% of
November 4, 2026
•
,

