

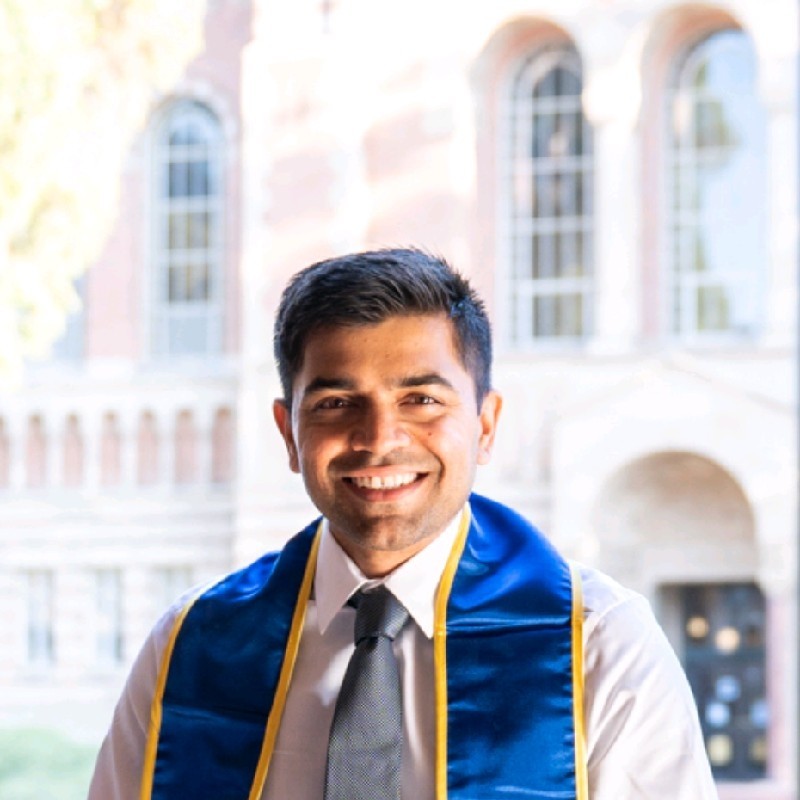
author
Applied Research Scientist
,
Snorkel AI
Vivek Krishnamurthy is currently conducting research at the intersection of Computer Vision and Natural Language. He is focused on fine-tuning multi-modal FMs with customer data to facilitate a range of downstream tasks, including classification and image retrieval.
The latest from Vivek

Blog
CRFM’s HELM and enterprise LLM evaluation beyond accuracy
As Snorkel AI prepares to build better enterprise LLM evaluations, we spoke with Yifan Mail from Stanford’s CRFM HELM project.
Reference-based Weak Supervision for Answer Sentence Selection using Web Data
Answer sentence selection (AS2) modeling requires annotated data, i.e., hand-labeled question-answer pairs. We present a strategy to collect weakly supervised answers for a question based on its reference to improve AS2 modeling. Specifically, we introduce Reference-based Weak Supervision (RWS), a fully automatic large-scale data pipeline that harvests high-quality weakly-supervised answers from abundant Web data requiring only a question-reference pair as input. We study the efficacy and robustness of RWS in the setting of TANDA, a recent state-of-the-art fine-tuning approach specialized for AS2. Our experiments indicate that the produced data consistently bolsters TANDA. We achieve the state of the art in...
Research Paper
Reference-based Weak Supervision for Answer Sentence Selection using Web Data
Answer sentence selection (AS2) modeling requires annotated data, i.e., hand-labeled question-answer pairs. We present a strategy to collect weakly supervised answers for a question based on its reference to improve AS2 modeling. Specifically, we introduce Reference-based Weak Supervision (RWS), a fully automatic large-scale data pipeline that harvests high-quality weakly-supervised answers from abundant Web data requiring only a question-reference pair as…

