

author
PhD Student
,
University of Wisconsin-Madison
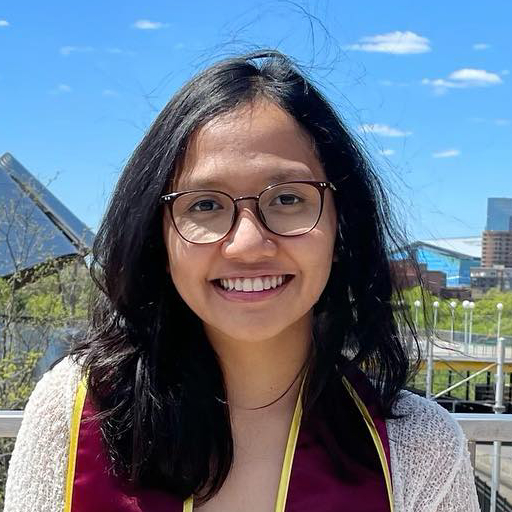
Dyah Adila hails from Indonesia and studies under Fred Sala. She had interned at Amazon AWS AI and JP Morgan Chase, Singapore. Her research interests center on building robust and reliable machine learning solutions— especially in settings where access to labeled data is limited.
The latest from Dyah
Mitigating Source Bias for Fairer Weak Supervision
Weak supervision enables efficient development of training sets by reducing the need for ground truth labels. However, the techniques that make weak supervision attractive -- such as integrating any source of signal to estimate unknown labels -- also entail the danger that the produced pseudolabels are highly biased. Surprisingly, given everyday use and the potential for increased bias, weak supervision has not been studied from the point of view of fairness. We begin such a study, starting with the observation that even when a fair model can be built from a dataset with access to ground-truth labels, the corresponding dataset...
Research Paper
Mitigating Source Bias for Fairer Weak Supervision
Weak supervision enables efficient development of training sets by reducing the need for ground truth labels. However, the techniques that make weak supervision attractive — such as integrating any source of signal to estimate unknown labels — also entail the danger that the produced pseudolabels are highly biased. Surprisingly, given everyday use and the potential for increased bias, weak supervision…

Causal Omnivore: Fusing Noisy Estimates of Spurious Correlations
Spurious correlations are one of the biggest pain points for users of modern machine learning. To handle this issue, many approaches attempt to learn features that are causally linked to the prediction variable. Such techniques, however, suffer from various flaws—they are often prohibitively complex or based on heuristics and strong assumptions that may fail in practice. There is no one-size-fits-all causal feature identification approach. To address this challenge, we propose a simple way to fuse multiple noisy estimates of causal features. Our approach treats the underlying causal structure as a latent variable and exploits recent developments in estimating latent structures...
Research Paper
Causal Omnivore: Fusing Noisy Estimates of Spurious Correlations
Spurious correlations are one of the biggest pain points for users of modern machine learning. To handle this issue, many approaches attempt to learn features that are causally linked to the prediction variable. Such techniques, however, suffer from various flaws—they are often prohibitively complex or based on heuristics and strong assumptions that may fail in practice. There is no one-size-fits-all…

AutoWS-Bench-101: Benchmarking Automated Weak Supervision with 100 Labels
Weak supervision (WS) is a powerful method to build labeled datasets for training supervised models in the face of little-to-no labeled data. It replaces hand-labeling data with aggregating multiple noisy-but-cheap label estimates expressed by labeling functions (LFs). While it has been used successfully in many domains, weak supervision's application scope is limited by the difficulty of constructing labeling functions for domains with complex or high-dimensional features. To address this, a handful of methods have proposed automating the LF design process using a small set of ground truth labels. In this work, we introduce AutoWS-Bench-101: a framework for evaluating automated WS...
Research Paper
AutoWS-Bench-101: Benchmarking Automated Weak Supervision with 100 Labels
Weak supervision (WS) is a powerful method to build labeled datasets for training supervised models in the face of little-to-no labeled data. It replaces hand-labeling data with aggregating multiple noisy-but-cheap label estimates expressed by labeling functions (LFs). While it has been used successfully in many domains, weak supervision’s application scope is limited by the difficulty of constructing labeling functions for…

Shoring Up the Foundations: Fusing Model Embeddings and Weak Supervision
Foundation models offer an exciting new paradigm for constructing models with out-of-the-box embeddings and a few labeled examples. However, it is not clear how to best apply foundation models without labeled data. A potential approach is to fuse foundation models with weak supervision frameworks, which use weak label sources -- pre-trained models, heuristics, crowd-workers -- to construct pseudolabels. The challenge is building a combination that best exploits the signal available in both foundation models and weak sources. We propose Liger, a combination that uses foundation model embeddings to improve two crucial elements of existing weak supervision techniques. First, we produce...
Research Paper
Shoring Up the Foundations: Fusing Model Embeddings and Weak Supervision
Foundation models offer an exciting new paradigm for constructing models with out-of-the-box embeddings and a few labeled examples. However, it is not clear how to best apply foundation models without labeled data. A potential approach is to fuse foundation models with weak supervision frameworks, which use weak label sources — pre-trained models, heuristics, crowd-workers — to construct pseudolabels. The challenge…

