

author
Co-Founder and Head of Research
,
Snorkel AI
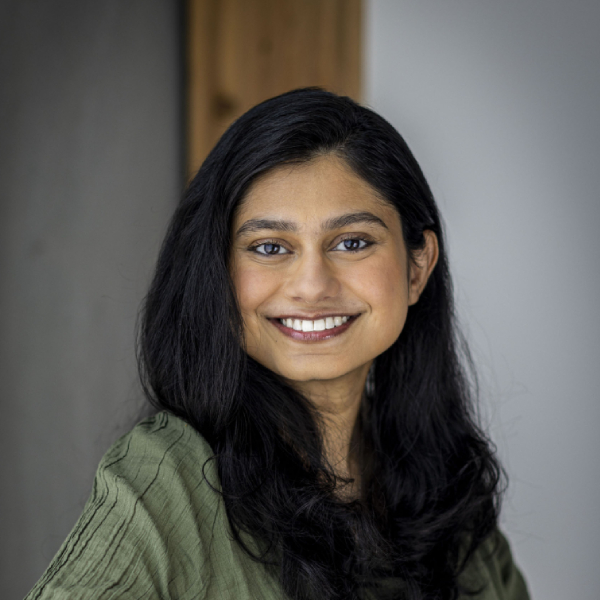
Paroma Varma is the co-founder and Head of Research at Snorkel AI, and earned her doctorate in electrical engineering from Stanford University. Her research focused on democratizing machine learning for domain experts who lack access to large datasets necessary for training intricate models, thus making complex AI technologies more accessible and impactful for a broader audience. She applied these methods in diverse fields such as medical imaging and autonomous driving.
The latest from Paroma
Utilizing Weak Supervision to Infer Complex Objects in Autonomous Driving Data
While the detection and classification of simple objects encountered during autonomous driving sessions has been widely researched, the detection of complex objects and situations based on the combinations of objects in a scene remains relatively overlooked. This is especially difficult due to the cost of gathering labels for each complex scenario of interest before training a specialized model. To address this bottleneck of training data, we explore the applicability of weak supervision, or relying on higher level, noisier forms of supervision to label training data. Specifically, we use data programming, a paradigm that can learn the accuracy and dependency structure...
Research Paper
Utilizing Weak Supervision to Infer Complex Objects in Autonomous Driving Data
While the detection and classification of simple objects encountered during autonomous driving sessions has been widely researched, the detection of complex objects and situations based on the combinations of objects in a scene remains relatively overlooked. This is especially difficult due to the cost of gathering labels for each complex scenario of interest before training a specialized model. To address…

Snuba: Automating Weak Supervision to Label Training Data
As deep learning models are applied to increasingly diverse problems, a key bottleneck is gathering enough high-quality training labels tailored to each task. Users therefore turn to weak supervision, relying on imperfect sources of labels like pattern matching and user-defined heuristics. Unfortunately, users have to design these sources for each task. This process can be time consuming and expensive: domain experts often perform repetitive steps like guessing optimal numerical thresholds and developing informative text patterns. To address these challenges, we present Snuba, a system to automatically generate heuristics using a small labeled dataset to assign training labels to a large,...
Research Paper
Snuba: Automating Weak Supervision to Label Training Data
As deep learning models are applied to increasingly diverse problems, a key bottleneck is gathering enough high-quality training labels tailored to each task. Users therefore turn to weak supervision, relying on imperfect sources of labels like pattern matching and user-defined heuristics. Unfortunately, users have to design these sources for each task. This process can be time consuming and expensive: domain…

Scene Graph Prediction With Limited Labels
Visual knowledge bases such as Visual Genome power numerous applications in computer vision, including visual question answering and captioning, but suffer from sparse, incomplete relationships. All scene graph models to date are limited to training on a small set of visual relationships that have thousands of training labels each. Hiring human annotators is expensive, and using textual knowledge base completion methods are incompatible with visual data. In this paper, we introduce a semi-supervised method that assigns probabilistic relationship labels to a large number of unlabeled images using few labeled examples. We analyze visual relationships to suggest two types of image-agnostic...
Research Paper
Scene Graph Prediction With Limited Labels
Visual knowledge bases such as Visual Genome power numerous applications in computer vision, including visual question answering and captioning, but suffer from sparse, incomplete relationships. All scene graph models to date are limited to training on a small set of visual relationships that have thousands of training labels each. Hiring human annotators is expensive, and using textual knowledge base completion…
Multi-Resolution Weak Supervision for Sequential Data
Since manually labeling training data is slow and expensive, recent industrial and scientific research efforts have turned to weaker or noisier forms of supervision sources. However, existing weak supervision approaches fail to model multi-resolution sources for sequential data, like video, that can assign labels to individual elements or collections of elements in a sequence. A key challenge in weak supervision is estimating the unknown accuracies and correlations of these sources without using labeled data. Multi-resolution sources exacerbate this challenge due to complex correlations and sample complexity that scales in the length of the sequence. We propose Dugong, the first framework...
Research Paper
Multi-Resolution Weak Supervision for Sequential Data
Since manually labeling training data is slow and expensive, recent industrial and scientific research efforts have turned to weaker or noisier forms of supervision sources. However, existing weak supervision approaches fail to model multi-resolution sources for sequential data, like video, that can assign labels to individual elements or collections of elements in a sequence. A key challenge in weak supervision…

Learning Dependency Structures for Weak Supervision Models
Labeling training data is a key bottleneck in the modern machine learning pipeline. Recent weak supervision approaches combine labels from multiple noisy sources by estimating their accuracies without access to ground truth labels; however, estimating the dependencies among these sources is a critical challenge. We focus on a robust PCAbased algorithm for learning these dependency structures, establish improved theoretical recovery rates, and outperform existing methods on various real-world tasks. Under certain conditions, we show that the amount of unlabeled data needed can scale sublinearly or even logarithmically with the number of sources m, improving over previous efforts that ignore the...
Research Paper
Learning Dependency Structures for Weak Supervision Models
Labeling training data is a key bottleneck in the modern machine learning pipeline. Recent weak supervision approaches combine labels from multiple noisy sources by estimating their accuracies without access to ground truth labels; however, estimating the dependencies among these sources is a critical challenge. We focus on a robust PCAbased algorithm for learning these dependency structures, establish improved theoretical recovery…

Training Classifiers with Natural Language Explanations
Training accurate classifiers requires many labels, but each label provides only limited information (one bit for binary classification). In this work, we propose BabbleLabble, a framework for training classifiers in which an annotator provides a natural language explanation for each labeling decision. A semantic parser converts these explanations into programmatic labeling functions that generate noisy labels for an arbitrary amount of unlabeled data, which is used to train a classifier. On three relation extraction tasks, we find that users are able to train classifiers with comparable F1 scores from 5–100× faster by providing explanations instead of just labels. Furthermore, given...
Research Paper
Training Classifiers with Natural Language Explanations
Training accurate classifiers requires many labels, but each label provides only limited information (one bit for binary classification). In this work, we propose BabbleLabble, a framework for training classifiers in which an annotator provides a natural language explanation for each labeling decision. A semantic parser converts these explanations into programmatic labeling functions that generate noisy labels for an arbitrary amount…
Inferring Generative Model Structure With Static Analysis
Obtaining enough labeled data to robustly train complex discriminative models is a major bottleneck in the machine learning pipeline. A popular solution is combining multiple sources of weak supervision using generative models. The structure of these models affects training label quality, but is difficult to learn without any ground truth labels. We instead rely on these weak supervision sources having some structure by virtue of being encoded programmatically. We present Coral, a paradigm that infers generative model structure by statically analyzing the code for these heuristics, thus reducing the data required to learn structure significantly. We prove that Coral's sample...
Research Paper
Inferring Generative Model Structure With Static Analysis
Obtaining enough labeled data to robustly train complex discriminative models is a major bottleneck in the machine learning pipeline. A popular solution is combining multiple sources of weak supervision using generative models. The structure of these models affects training label quality, but is difficult to learn without any ground truth labels. We instead rely on these weak supervision sources having…

Socratic Learning: Augmenting Generative Models to Incorporate Latent Subsets in Training Data
A challenge in training discriminative models like neural networks is obtaining enough labeled training data. Recent approaches use generative models to combine weak supervision sources, like user-defined heuristics or knowledge bases, to label training data. Prior work has explored learning accuracies for these sources even without ground truth labels, but they assume that a single accuracy parameter is sufficient to model the behavior of these sources over the entire training set. In particular, they fail to model latent subsets in the training data in which the supervision sources perform differently than on average. We present Socratic learning, a paradigm that...
Research Paper
Socratic Learning: Augmenting Generative Models to Incorporate Latent Subsets in Training Data
A challenge in training discriminative models like neural networks is obtaining enough labeled training data. Recent approaches use generative models to combine weak supervision sources, like user-defined heuristics or knowledge bases, to label training data. Prior work has explored learning accuracies for these sources even without ground truth labels, but they assume that a single accuracy parameter is sufficient to…

